Overcoming Unnoticed Data Corruption in Amazon SageMaker HyperPod: Detection and Recovery Strategies
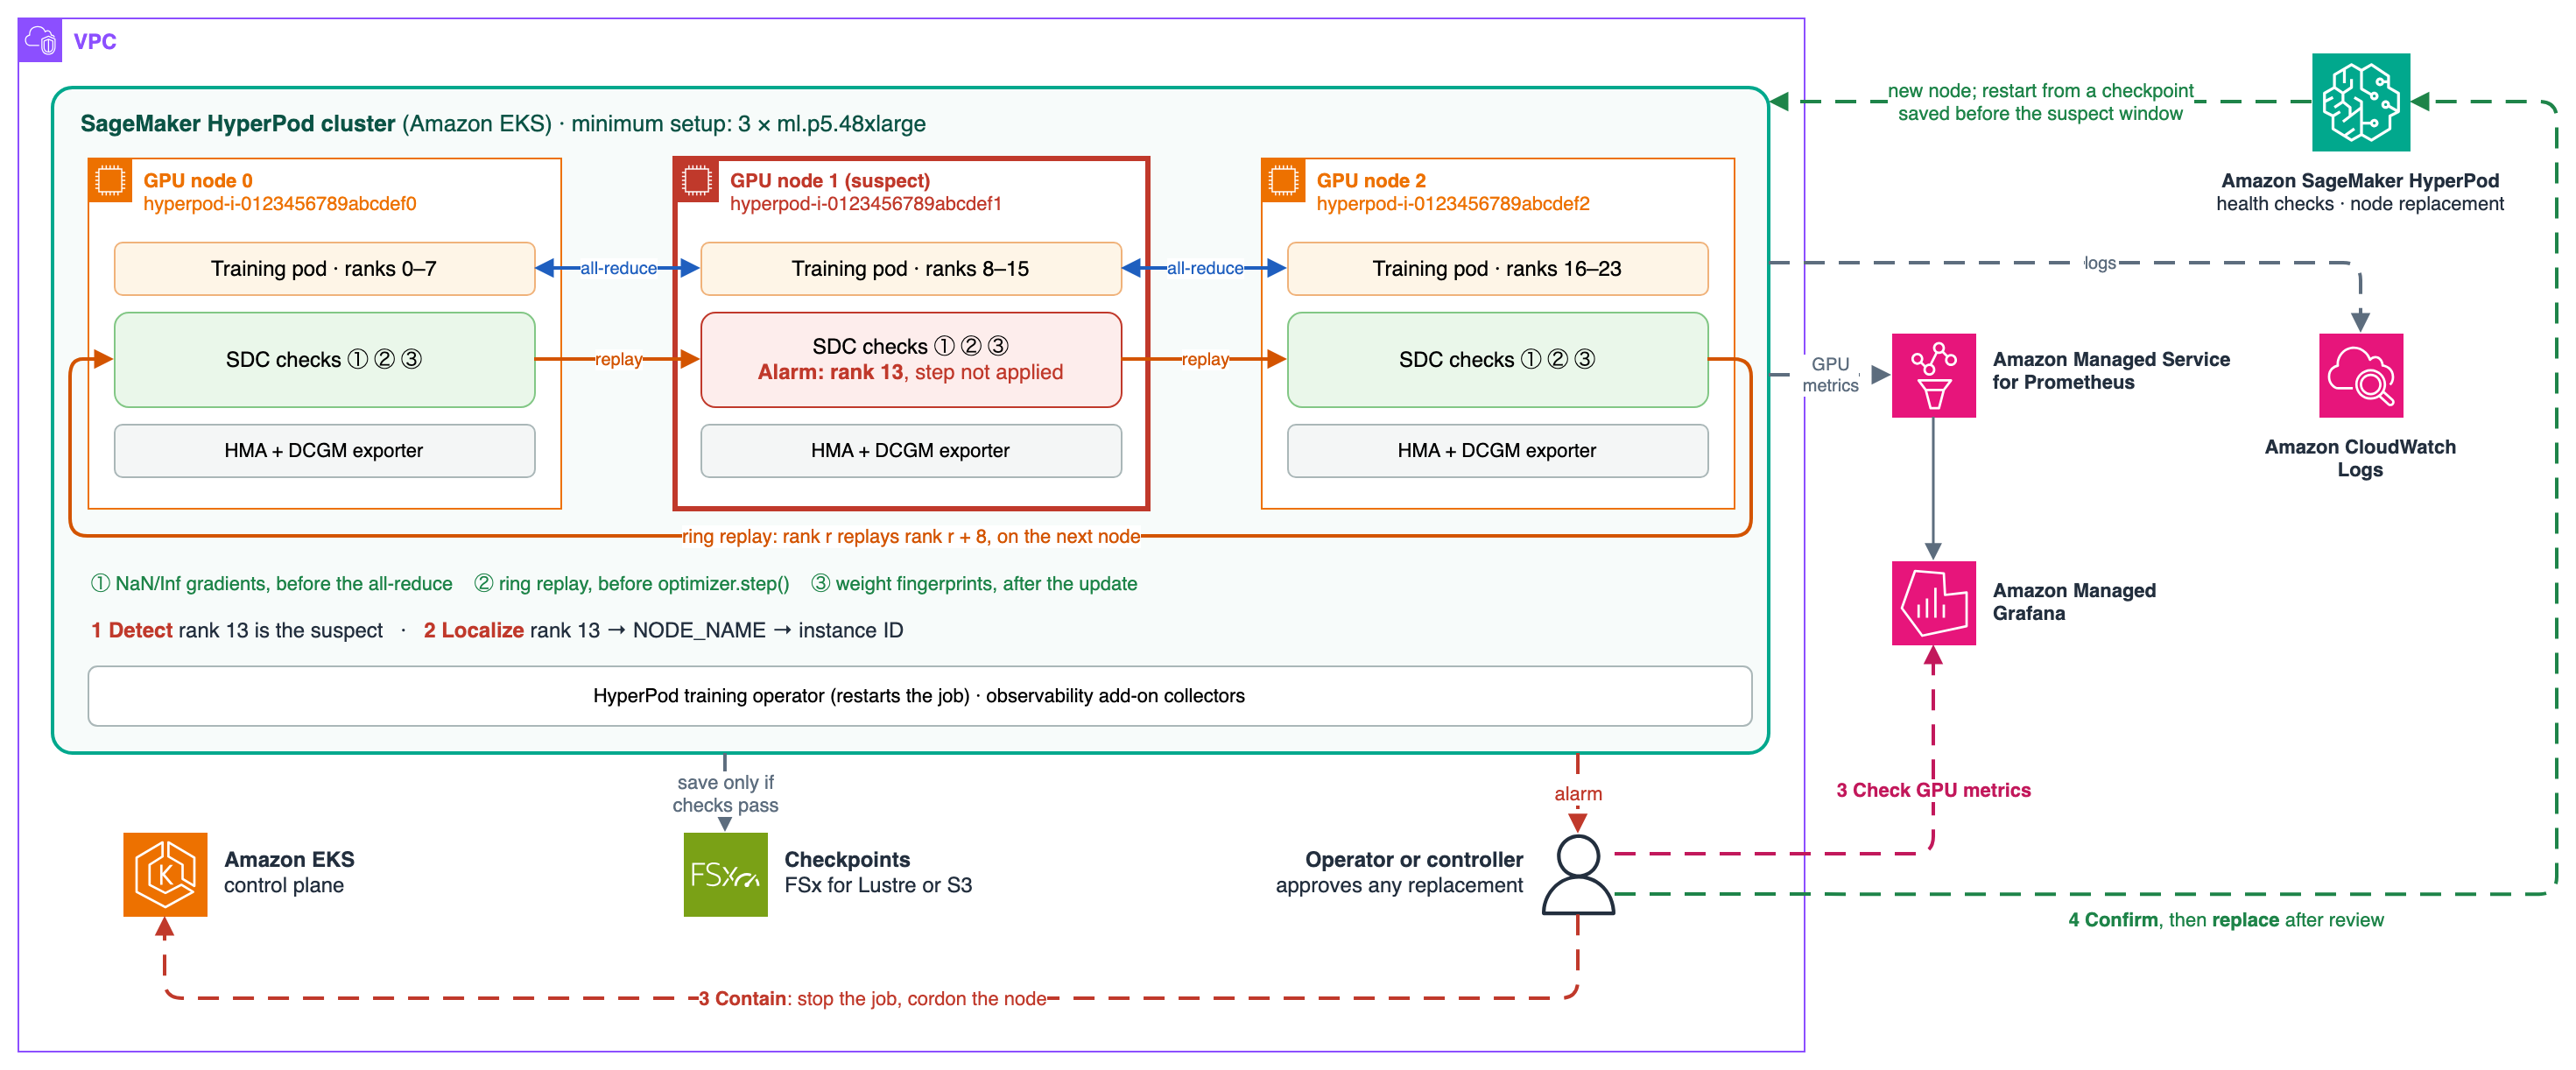
Silent data corruption (SDC) in machine learning training occurs when hardware, such as a GPU, returns incorrect but plausible numbers without raising errors. This can lead to the propagation of incorrect data into gradients and weights in distributed training, resulting in a weaker model or unexplained divergence. Detection of SDC is challenging as it does not trigger hardware errors and can s...
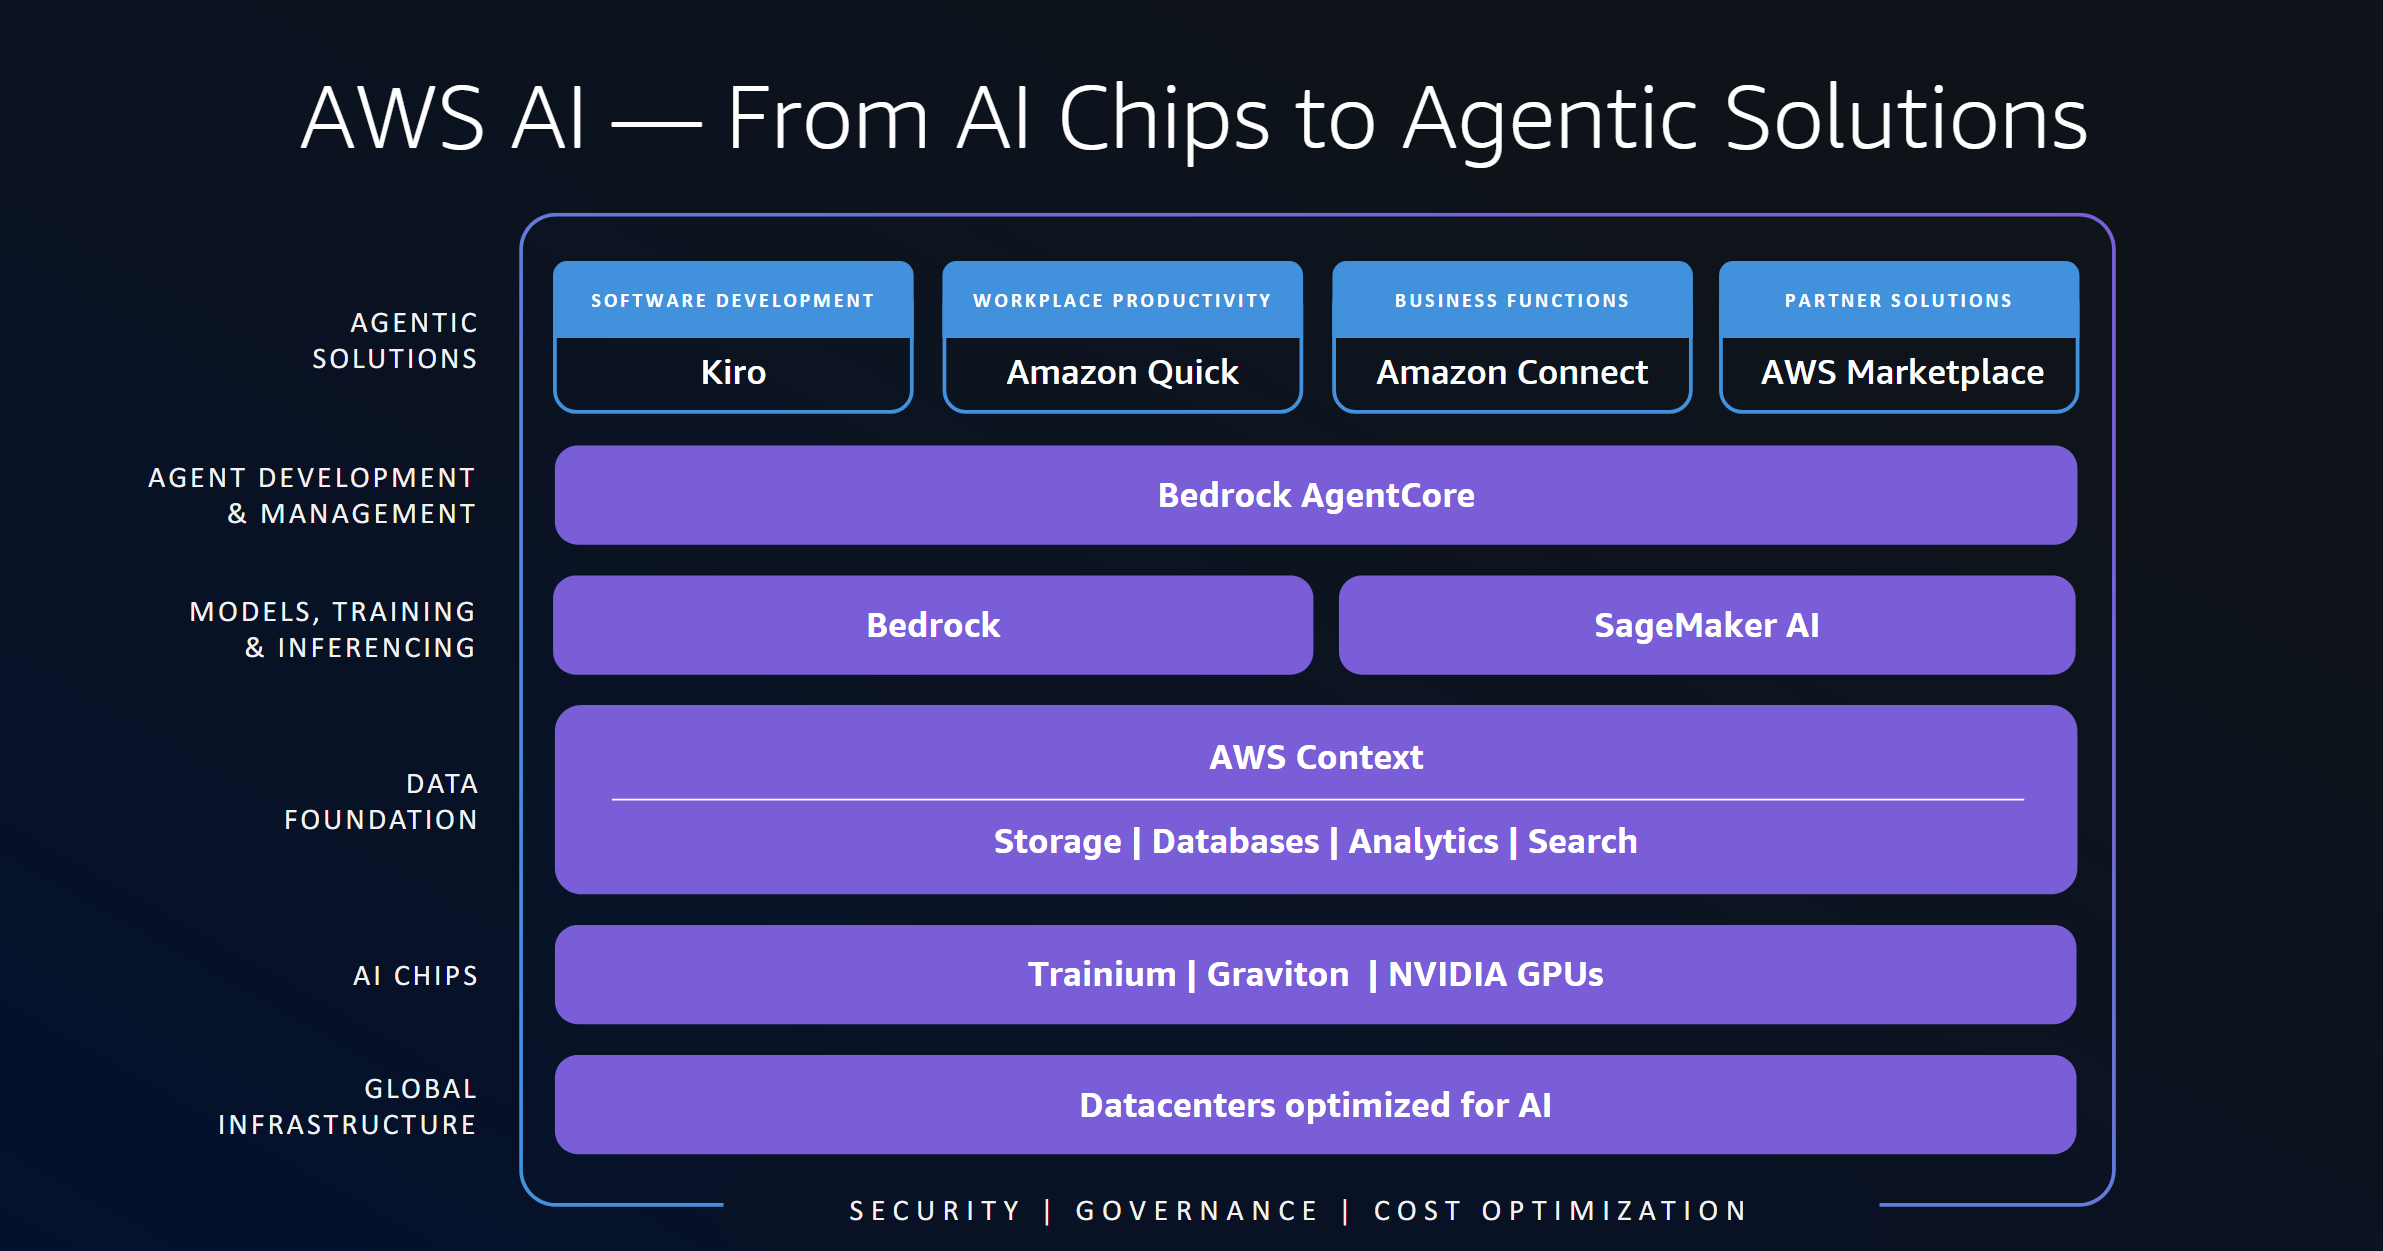
Amazon Web Services (AWS) will host its annual learning event, re:Invent, from November 30th to December 4th. Attendees can engage in various AWS technology areas through keynotes, interactive activities, and over 2,000 sessions, including 140 in the AI/ML track. Sessions are available for different skill levels, and some can be accessed on demand. re:Invent offers breakout sessions, chalk-talk...
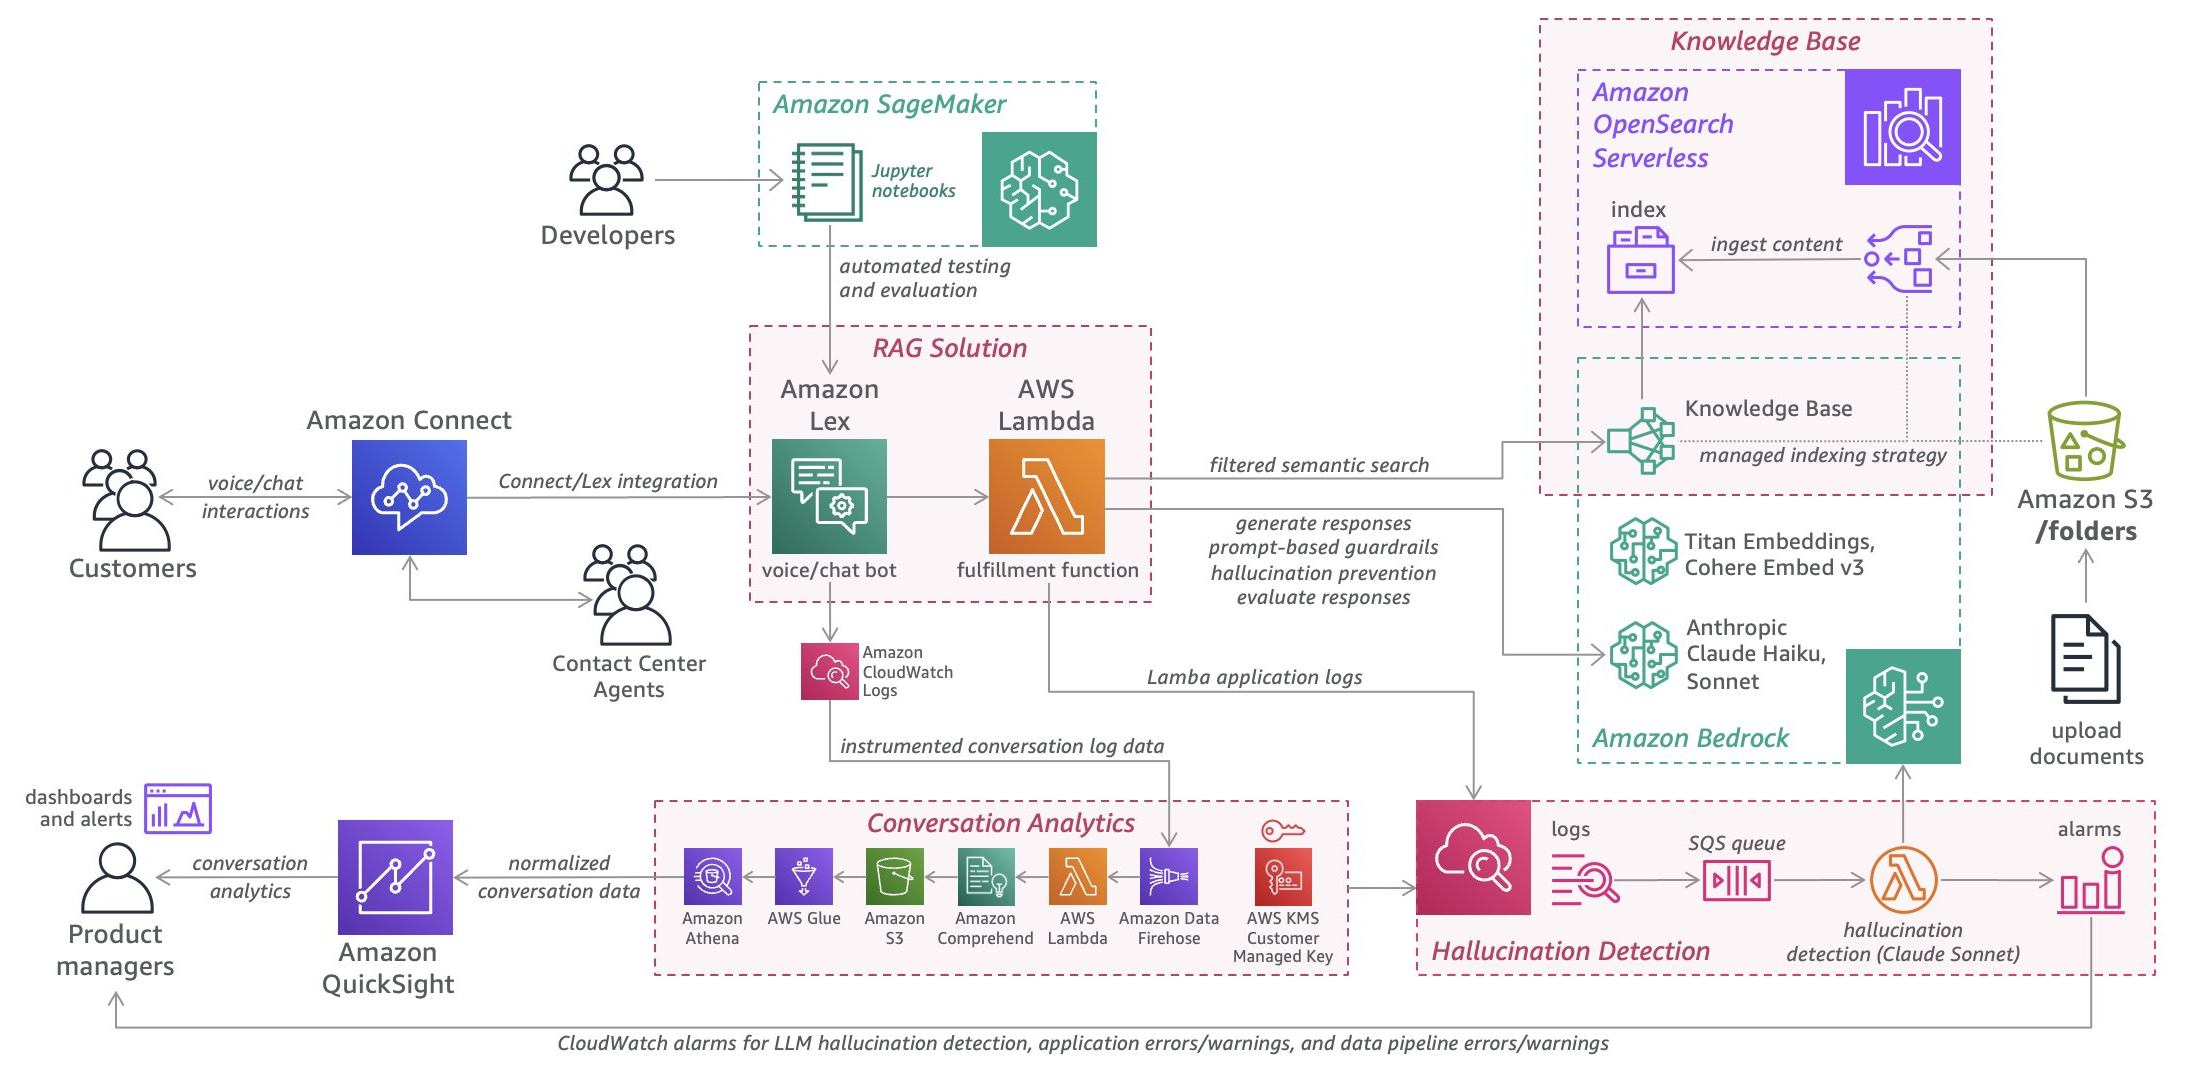
In this post, you will discover how reusable assets from the AWS Generative AI Innovation Center can help reduce development time and costs for generative AI solutions. These assets, including Retrieval Augmented Generation pipelines, document processors, and agent scaffolding, can save teams months of development time as shown by companies like DoorDash, Lyft, and Ricoh. The post also explains...
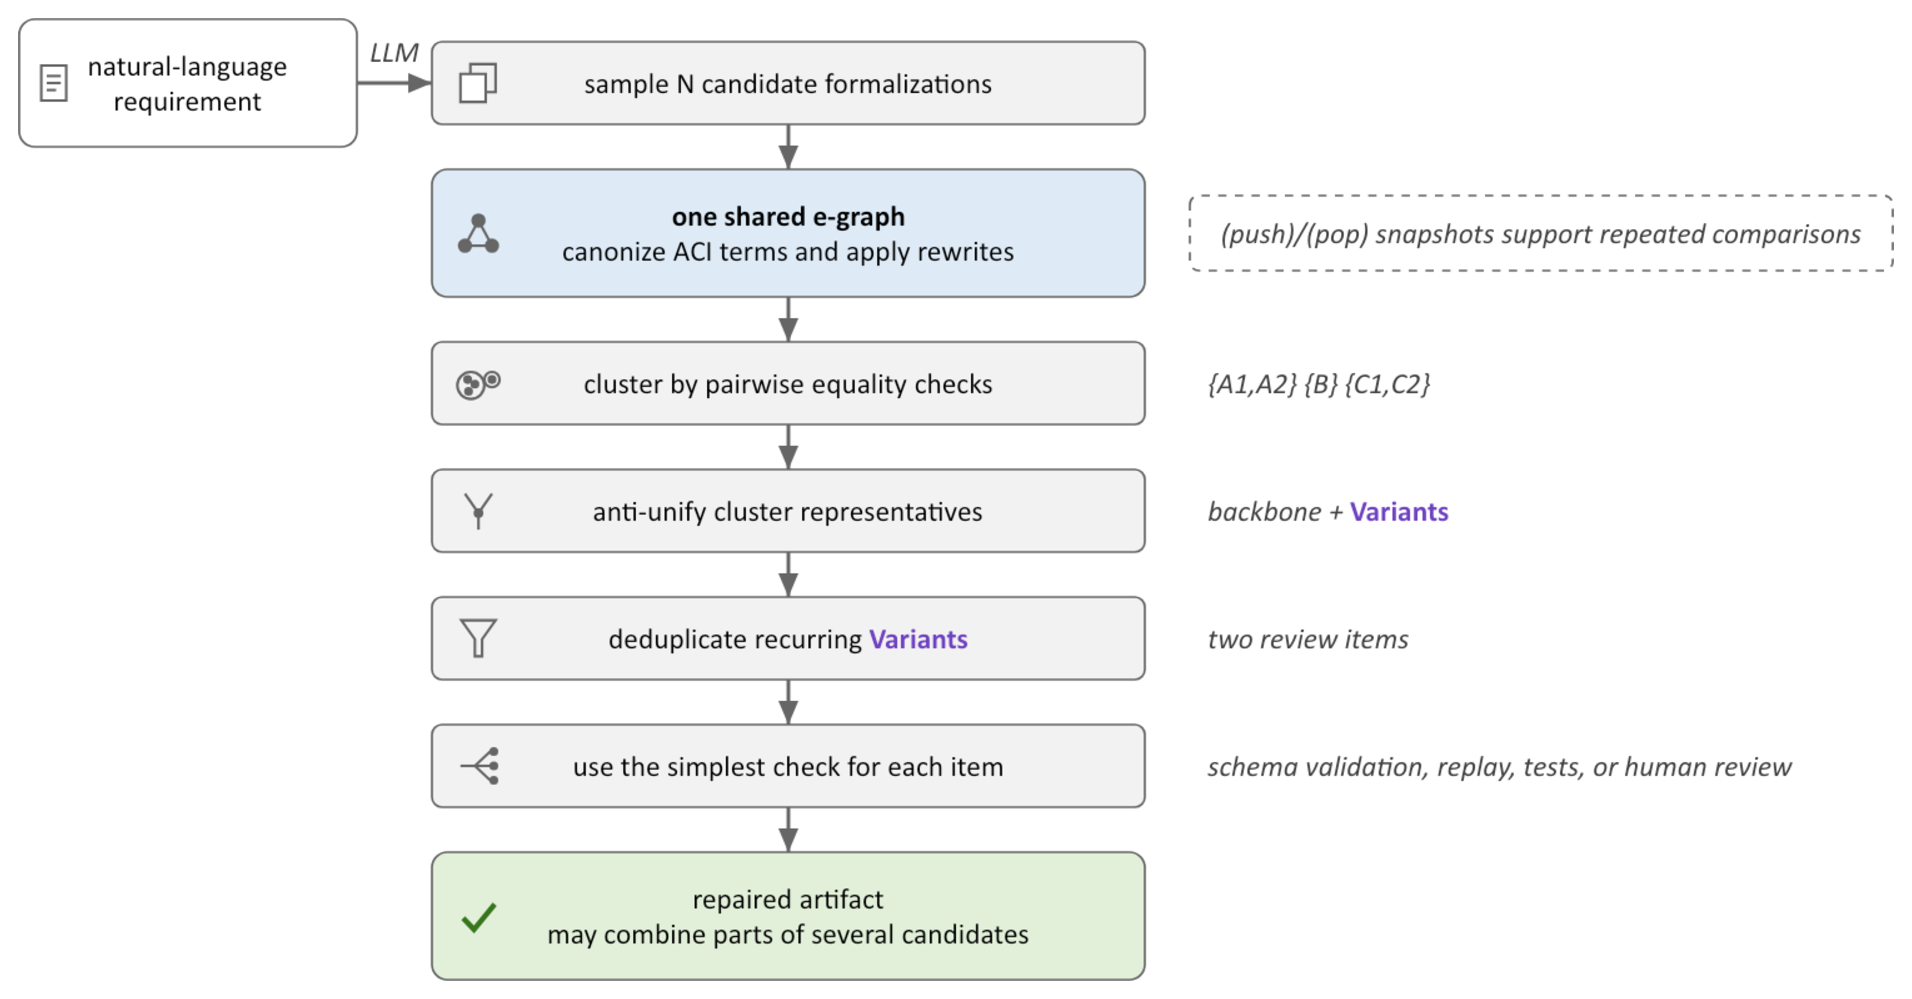
In code review, using a textual difference between files can be misleading due to syntactic changes that don't affect meaning. A semantic diff, computed using anti-unification, identifies shared parts and disagreements between policies. This is useful when generating formal language models from natural language or comparing different policy formats like Cedar, Dogwood, or OpenShell policies. Ag...
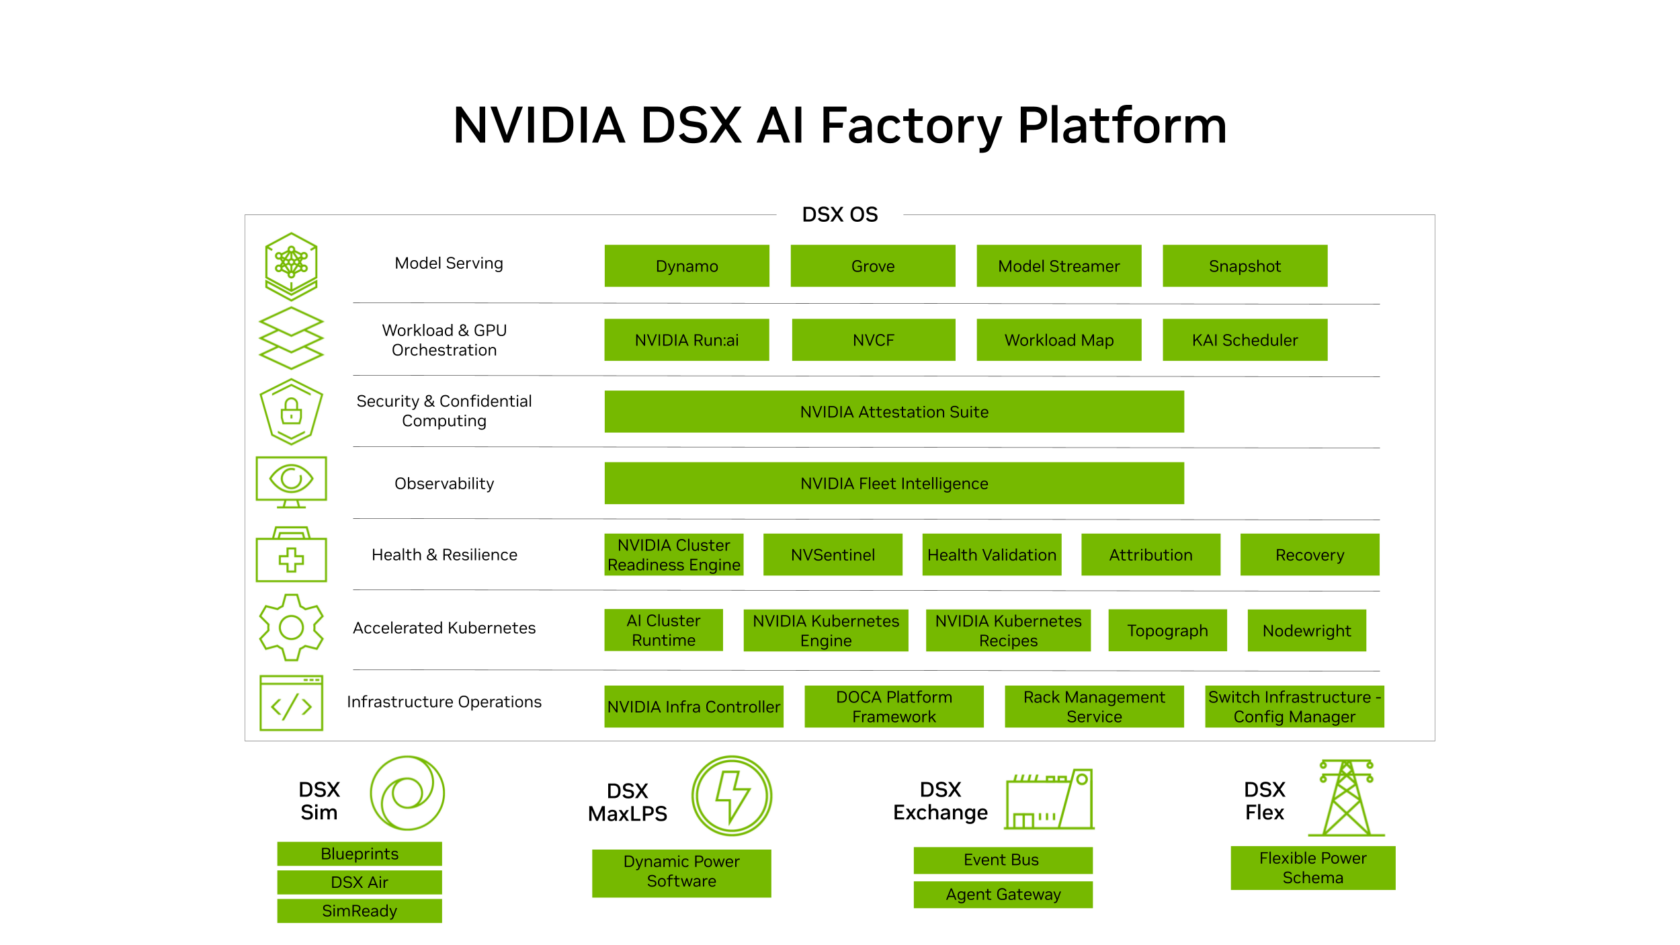
NVIDIA is strengthening its commitment to the open source Kubernetes system, which manages applications across thousands of AI factories, by contributing new tools to enhance security and scaling at the KubeCon + CloudNativeCon conference. NVIDIA is contributing NVIDIA OpenShell, an open source runtime for securing and governing autonomous agents, to the Cloud Native Computing Foundation (CNCF)...
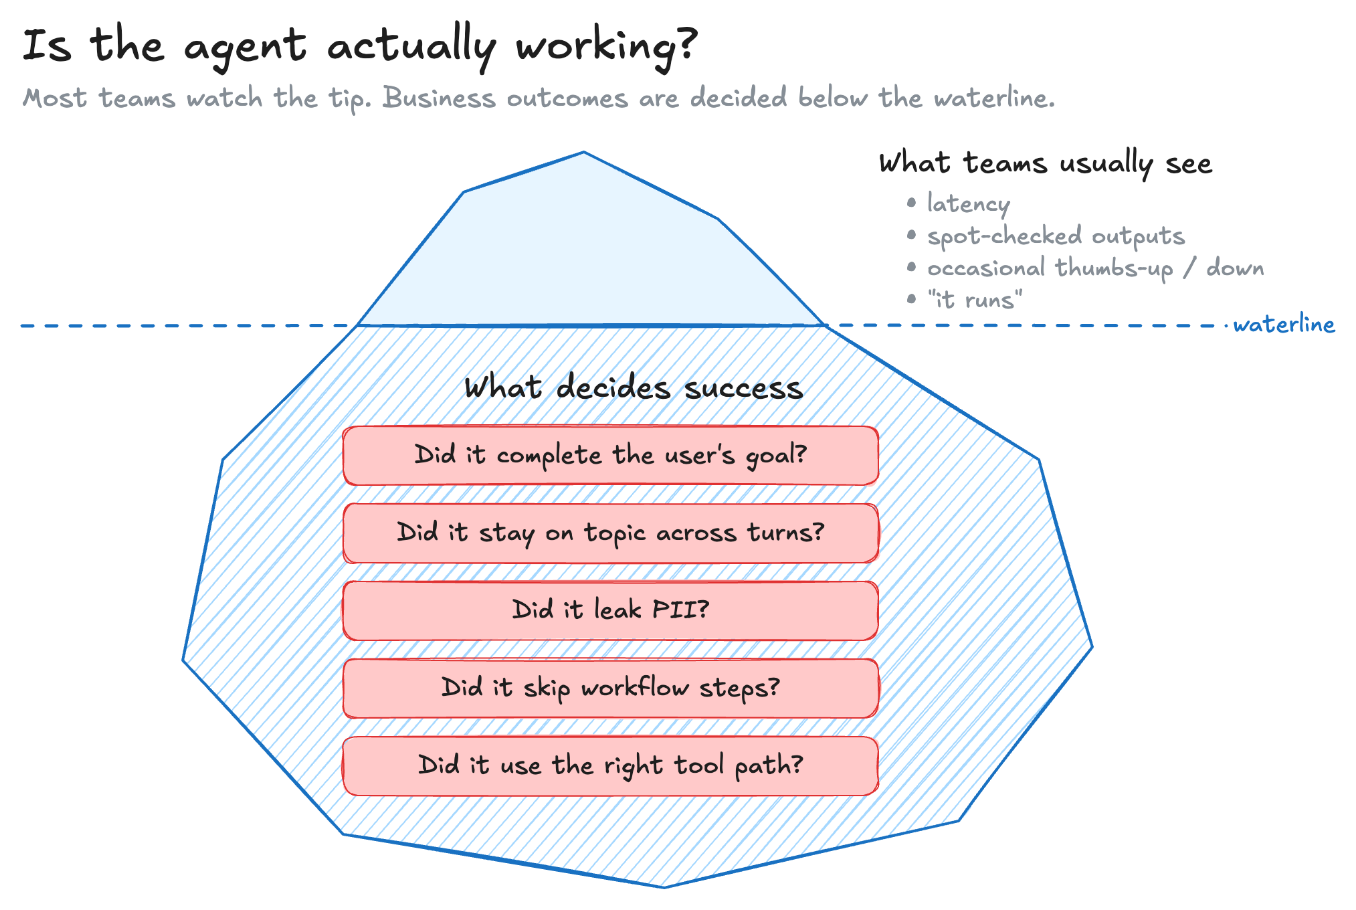
When deploying an agent in production, ensuring it's effectively meeting business requirements at scale is a common challenge. Teams often rely on surface signals such as completion rates and latency, but these do not provide insight into whether the agent is finishing tasks, staying on topic, leaking PII, or accurately following intended steps. This issue is addressed through agent evaluation....
In the given study, the author explores the performance of two encoding techniques for tree-based machine learning models, focusing on gradient boosting regression with decision tree weak learners. The first technique, referred to as super simple, uses ordinal encoding for categorical variables. The second technique, referred to as complex, employs smoothed-target encoding for continuous variab...
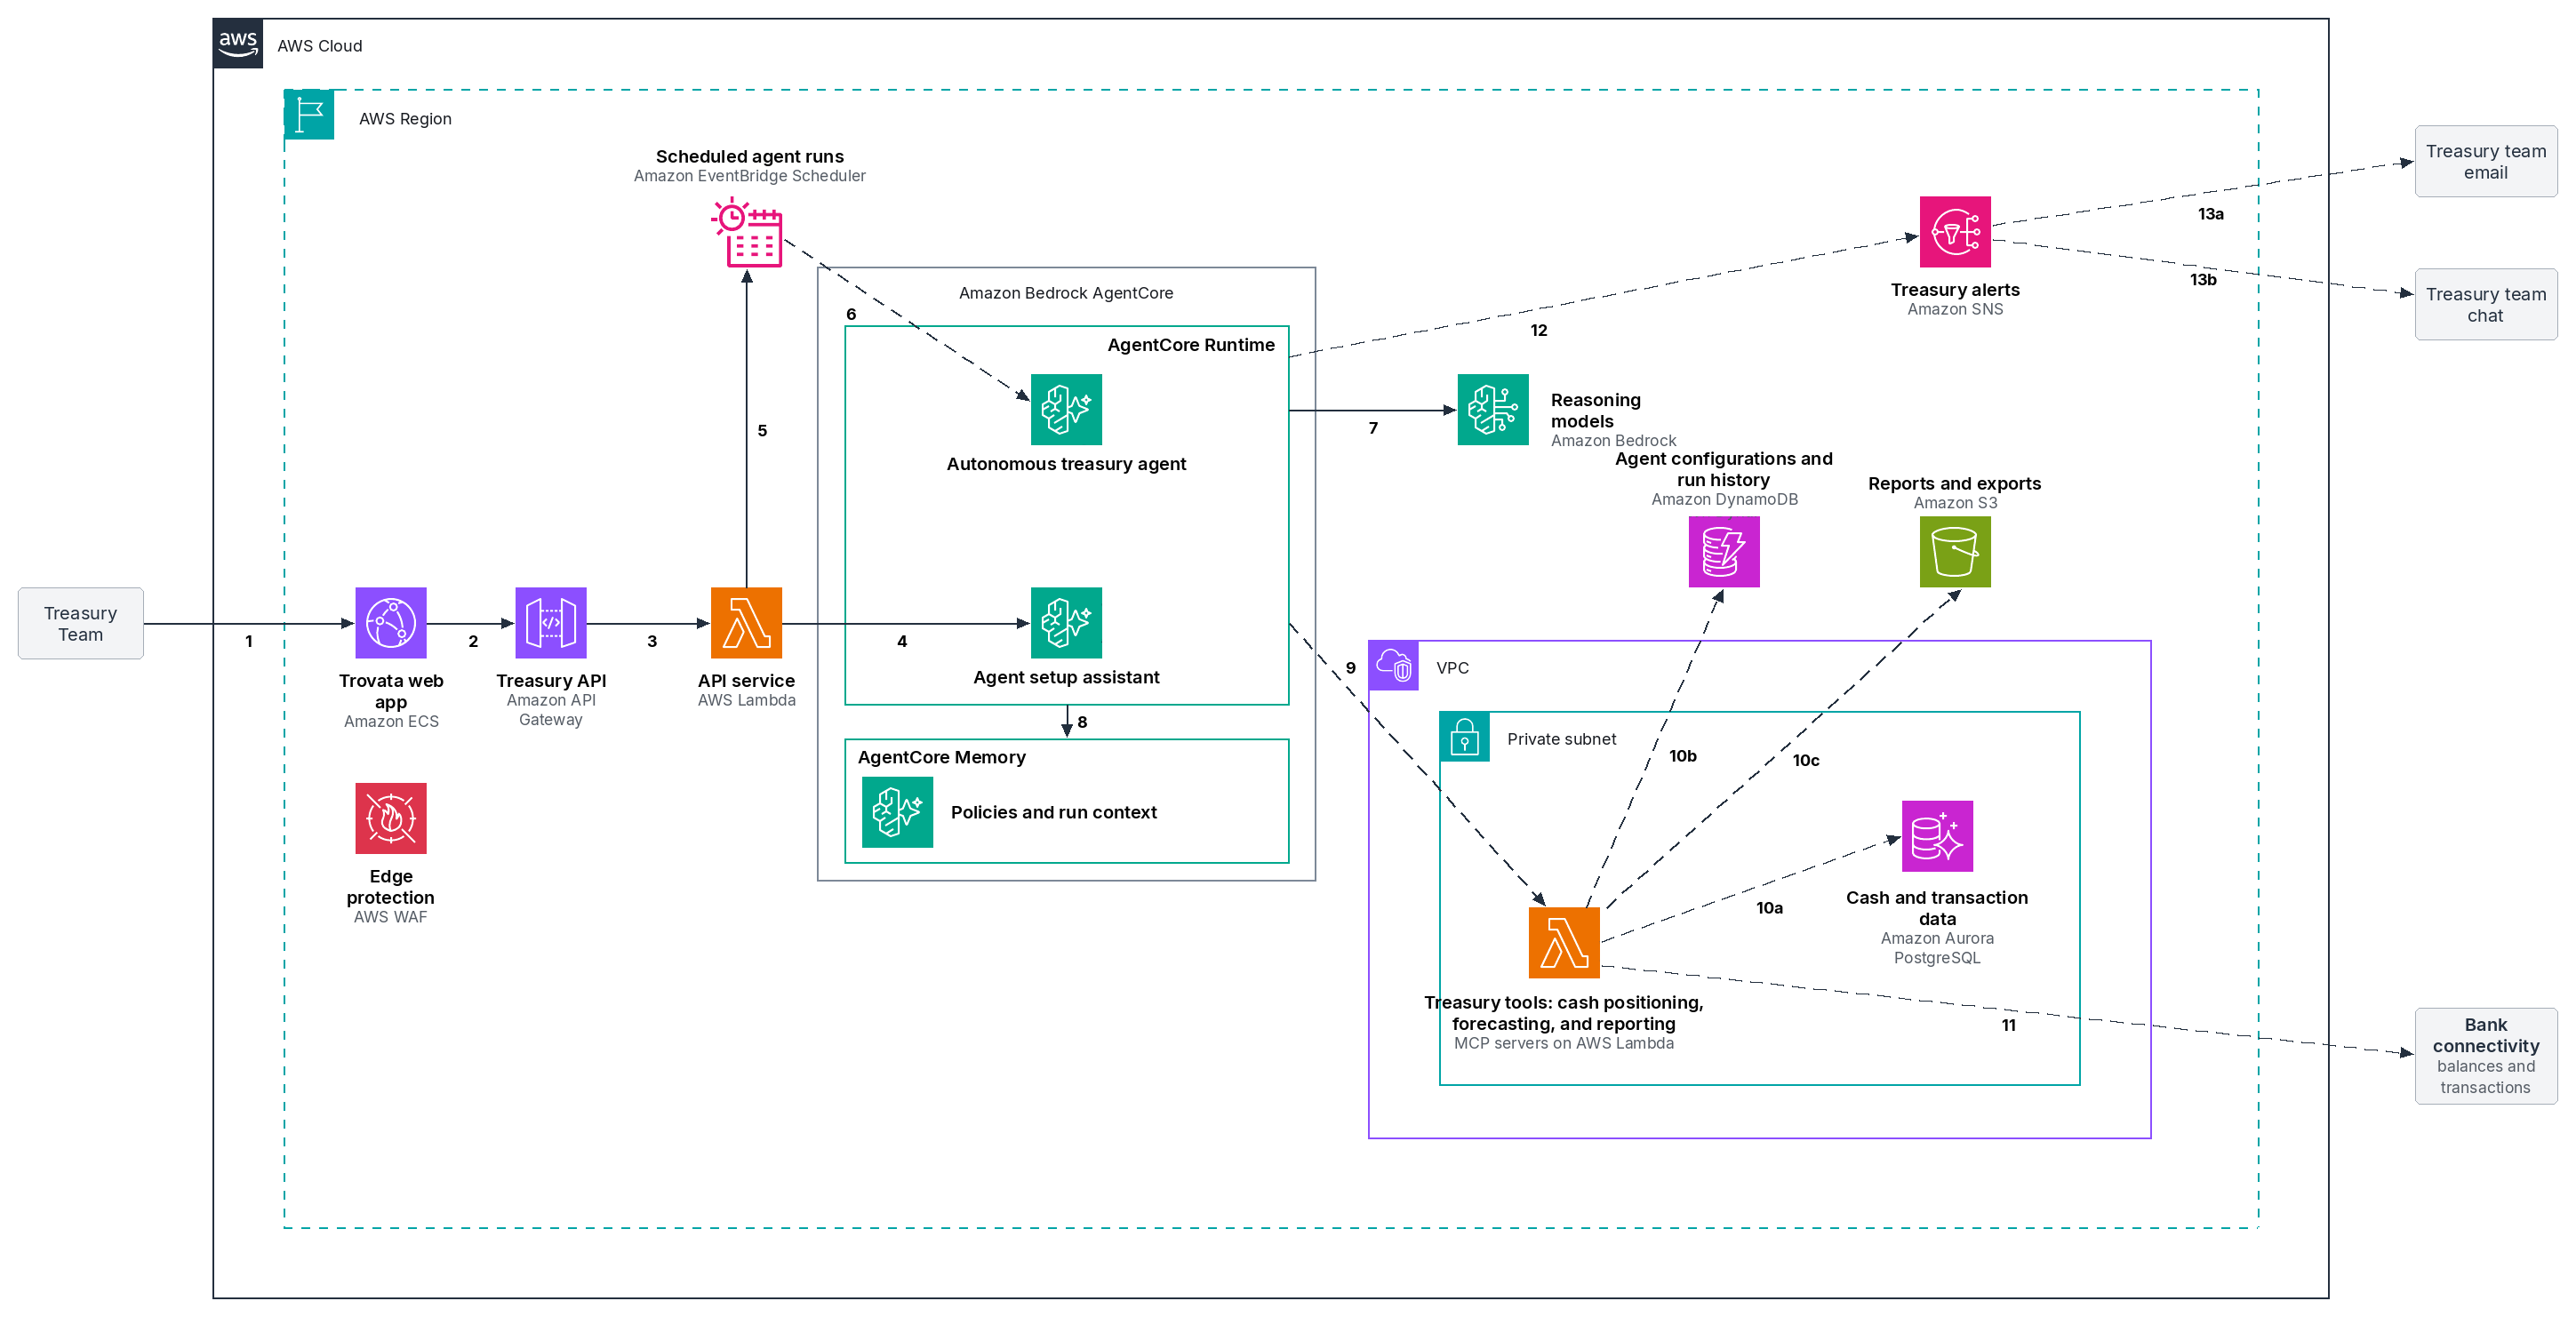
Trovata is an AI-driven platform for corporate cash and liquidity management, offering direct access to over 10,000 banks through a single system. Treasury teams face challenges with fragmented banking data, manual reporting, and outdated Treasury Management Systems (TMS). Trovata's innovative solution addresses these issues by introducing autonomous agents that act on behalf of treasury teams,...
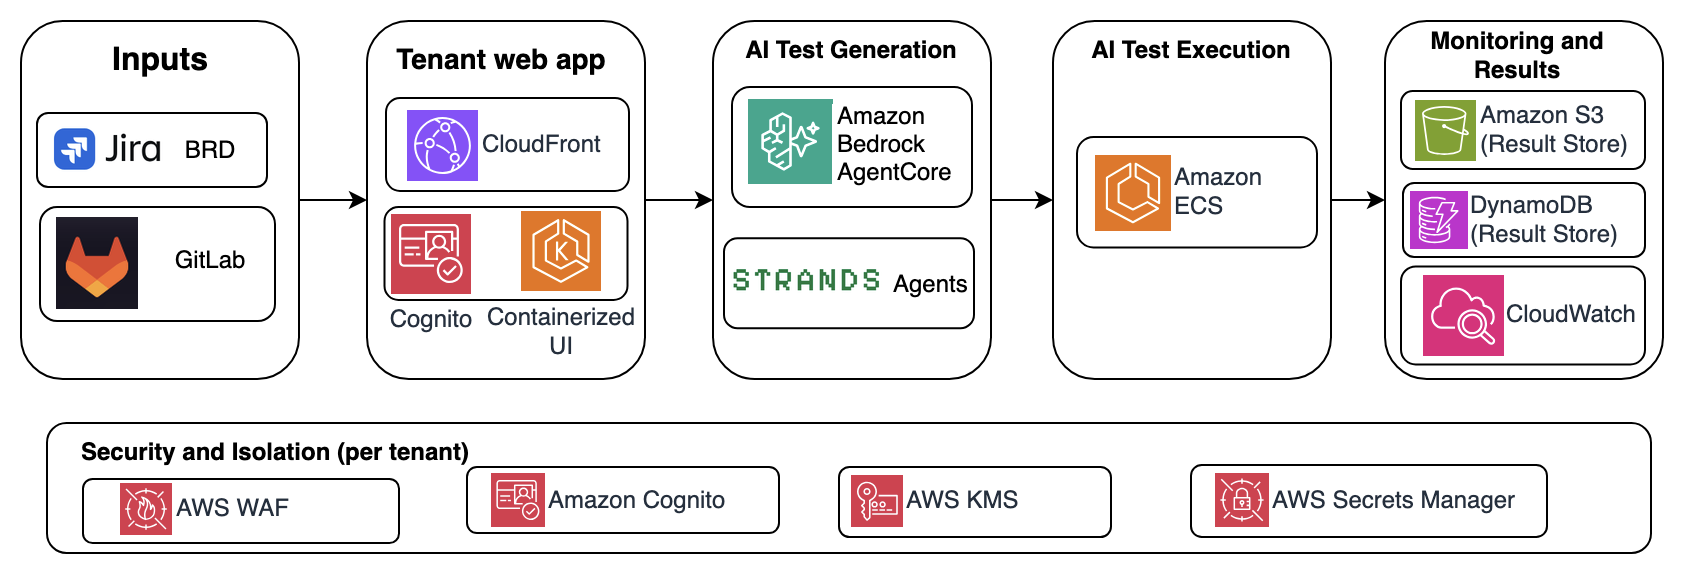
Tata Consultancy Services (TCS) identified that for Banking, Financial Services, and Insurance (BFSI) clients, the slowest part of a release is not writing application code, but rather the chain of work that follows. This includes interpreting requirements, designing scenarios, writing and maintaining automation, preparing execution environments, investigating failures, and assembling evidence ...
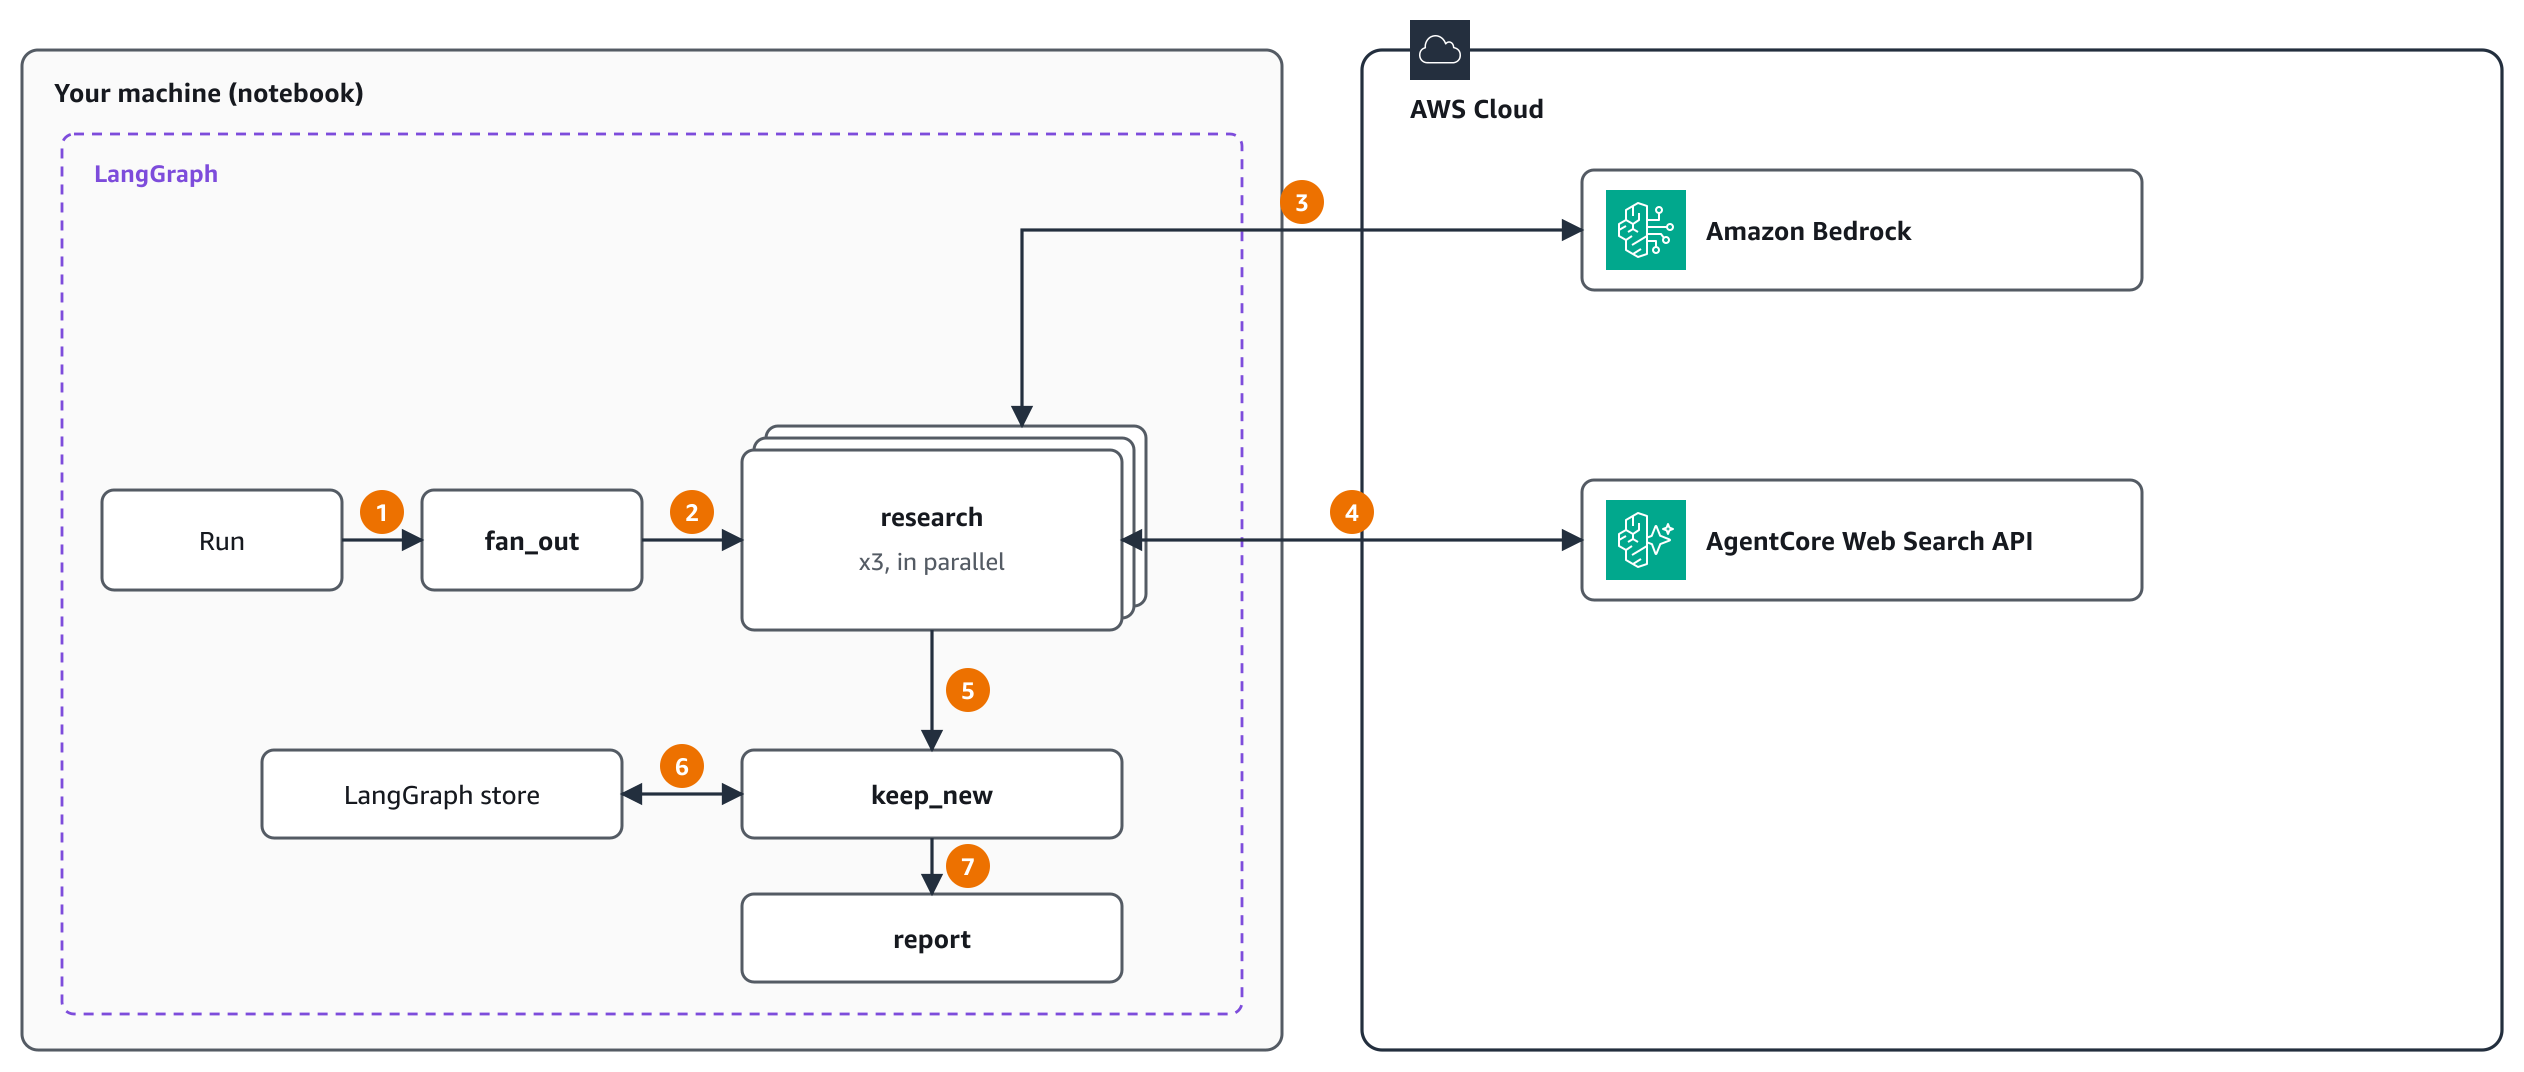
In this summary, we highlight Amazon Bedrock AgentCore's new feature, the Web Search API. This API enables AI agents to access current web results through a single API call, using their existing AWS credentials. The results include titles, URLs, publication dates, and extracts relevant to the query, while users can also specify domain restrictions and publication date ranges. The Web Search API...
Moonshot AI's new post-trained version of Kimi K3.1, named Kimi K3.1 Pro Highspeed, is now accessible on Amazon Bedrock. With the same open-weight architecture and context window, this upgraded model benefits from additional post-training compute, focusing on long-horizon tasks and reducing factual errors. It enhances professional functions, including financial modeling and document processing,...
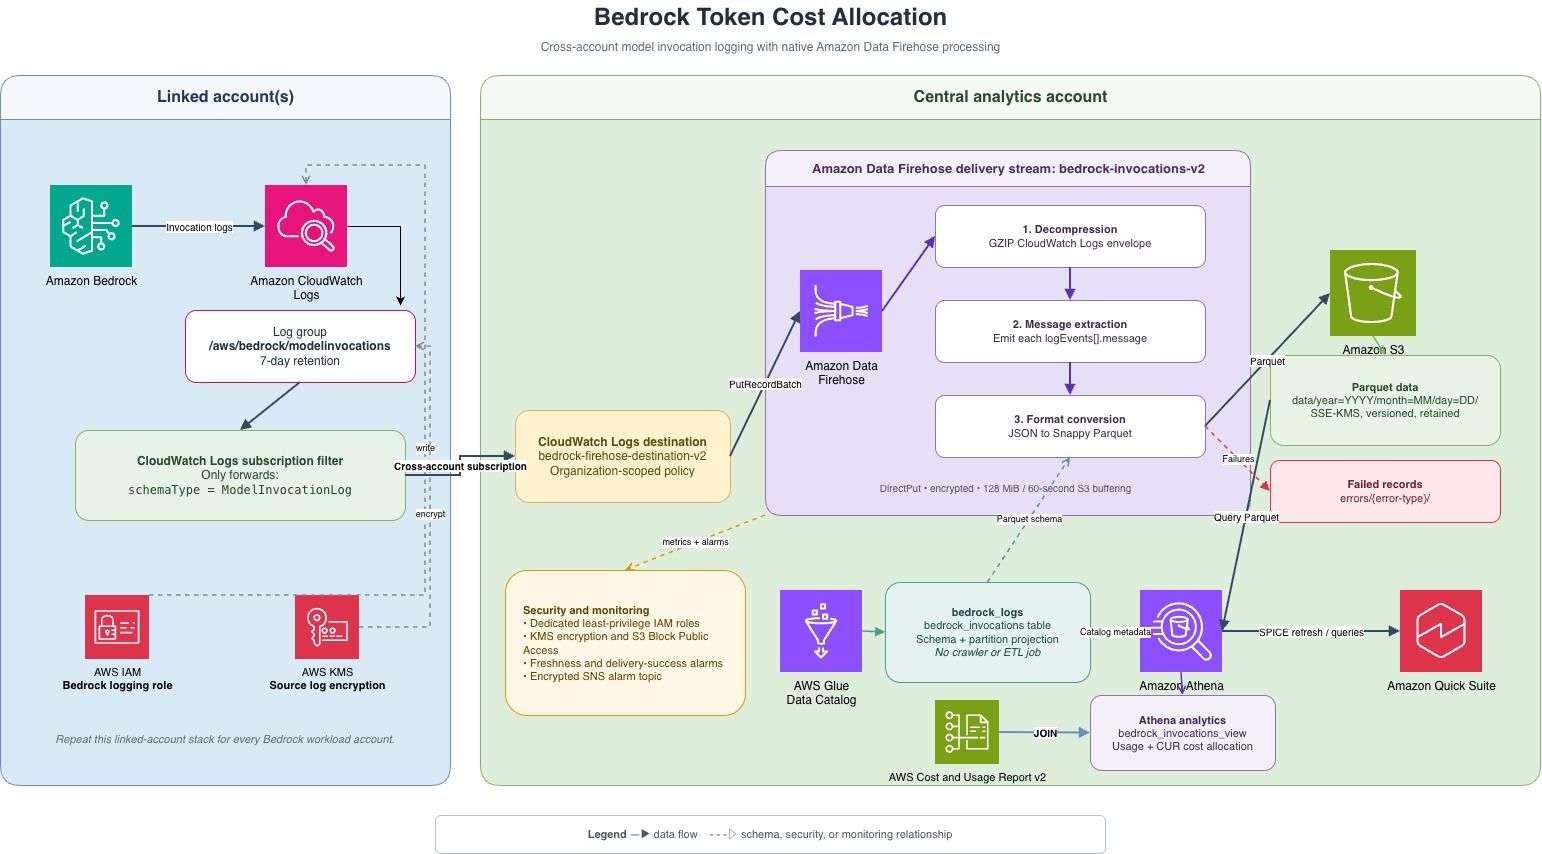
In this summary, I will describe a solution for observability data lake needs in Amazon Bedrock workloads. When running multiple model invocations daily across different accounts, it becomes challenging to understand what happened after a request was sent. Questions arise, such as which prompt was used, the model response, token usage, handling model, and response quality. As a platform or ML e...
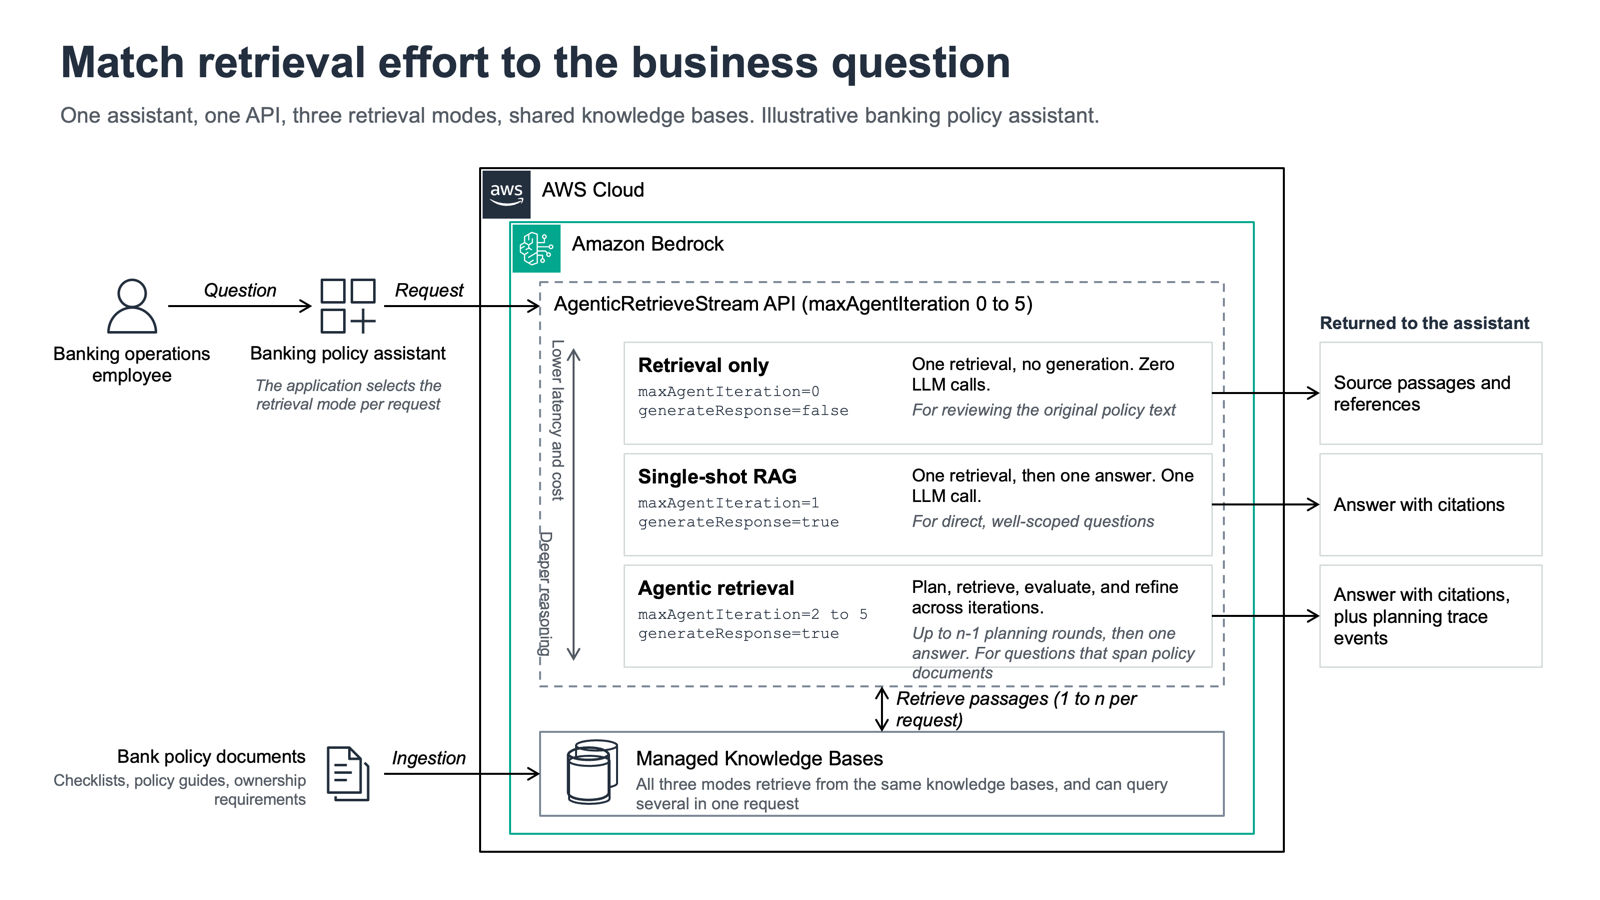
An internal AI assistant in a banking operations context helps an employee with two different types of information requests. For a checklist lookup, the assistant uses single-shot Retrieval Augmented Generation (RAG) from Amazon Bedrock Managed Knowledge Base for a quick and single answer. For a cross-policy comparison between sole proprietorships, LLCs, and partnerships, the assistant uses age...
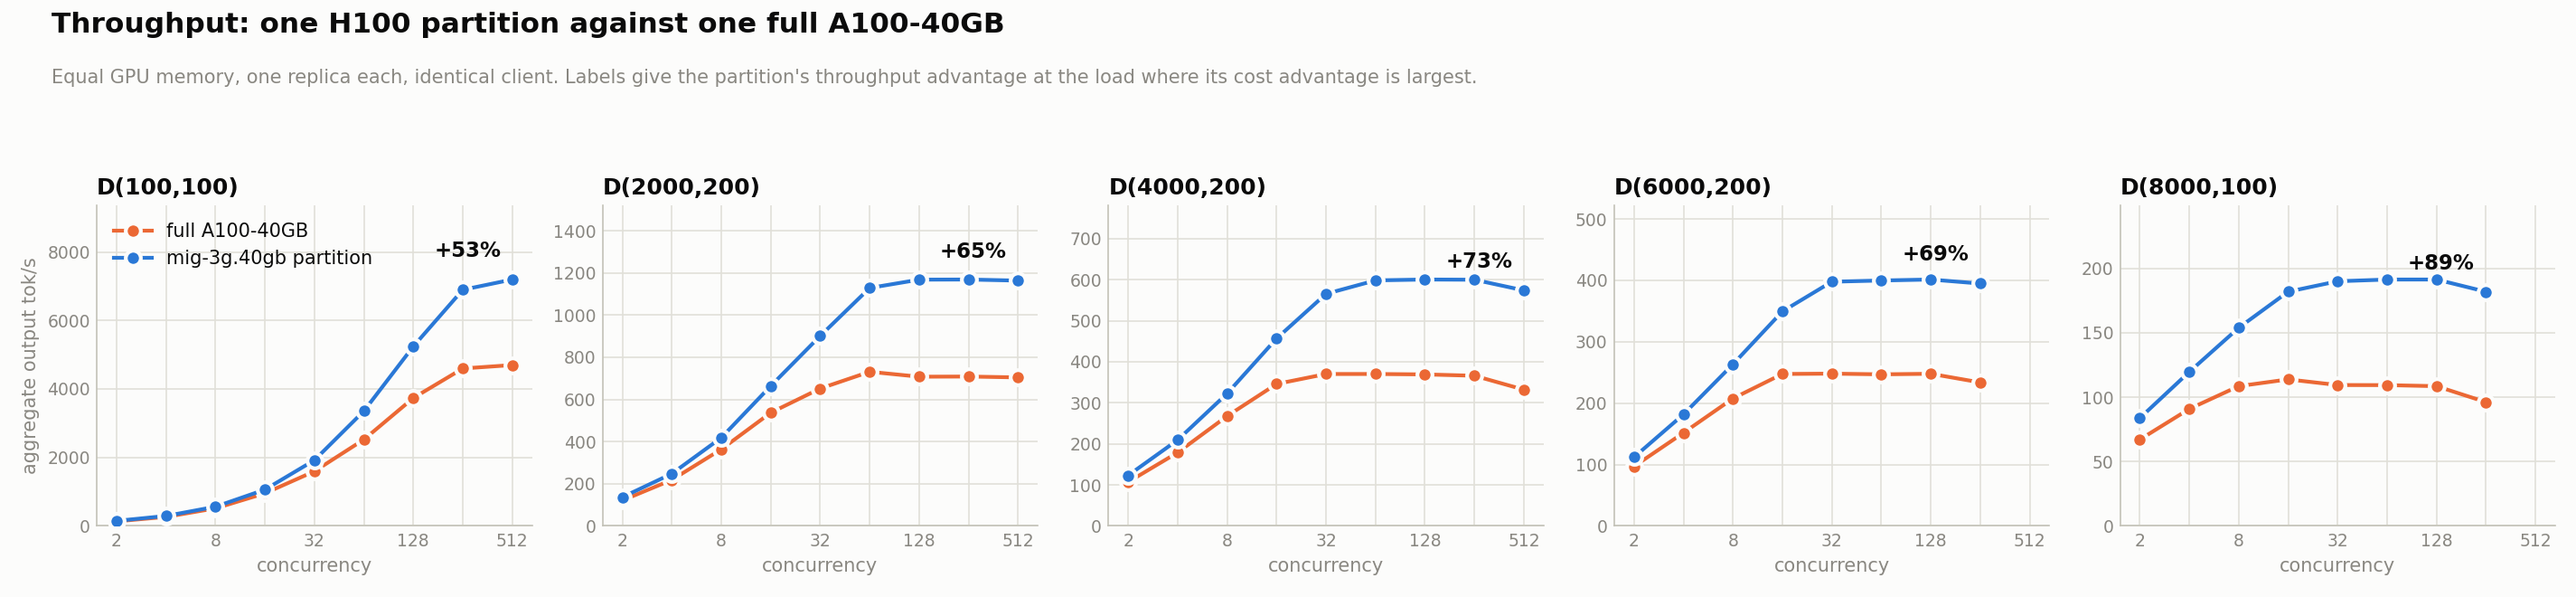
When deploying machine learning models on Amazon SageMaker GPU endpoints, the smallest available GPU unit is a whole accelerator. This limitation results in increased costs as each deployment requires a full GPU, limiting the number of models that can be hosted on an instance and potentially leading to underutilization or overpaying for capabilities. Amazon SageMaker Inference now supports GPU ...
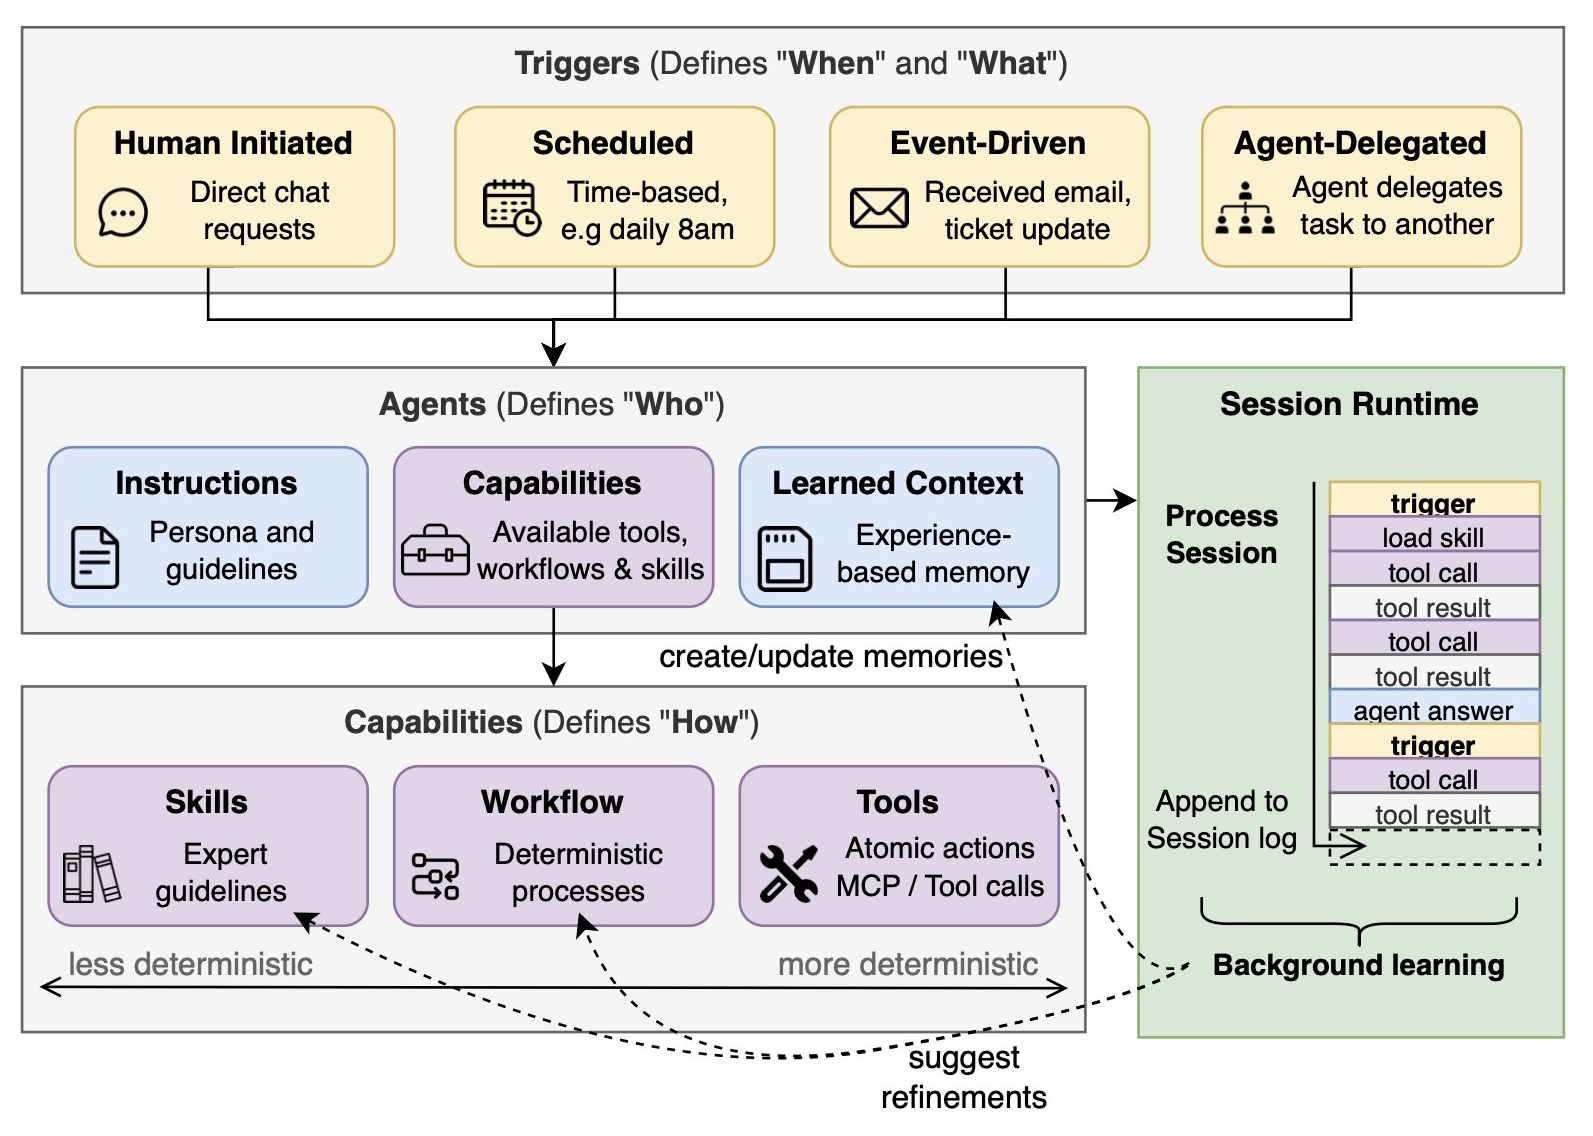
In this text, the author discusses the challenges of defining primitives in a system where agents take actions instead of just answering questions. The author mentions the repetition of ideas under different names, such as an actor, signal, packaged procedure, and memory. The author introduces a taxonomy of primitives based on the questions "When?", "What?", "Who?", and "How?". Triggers are dis...