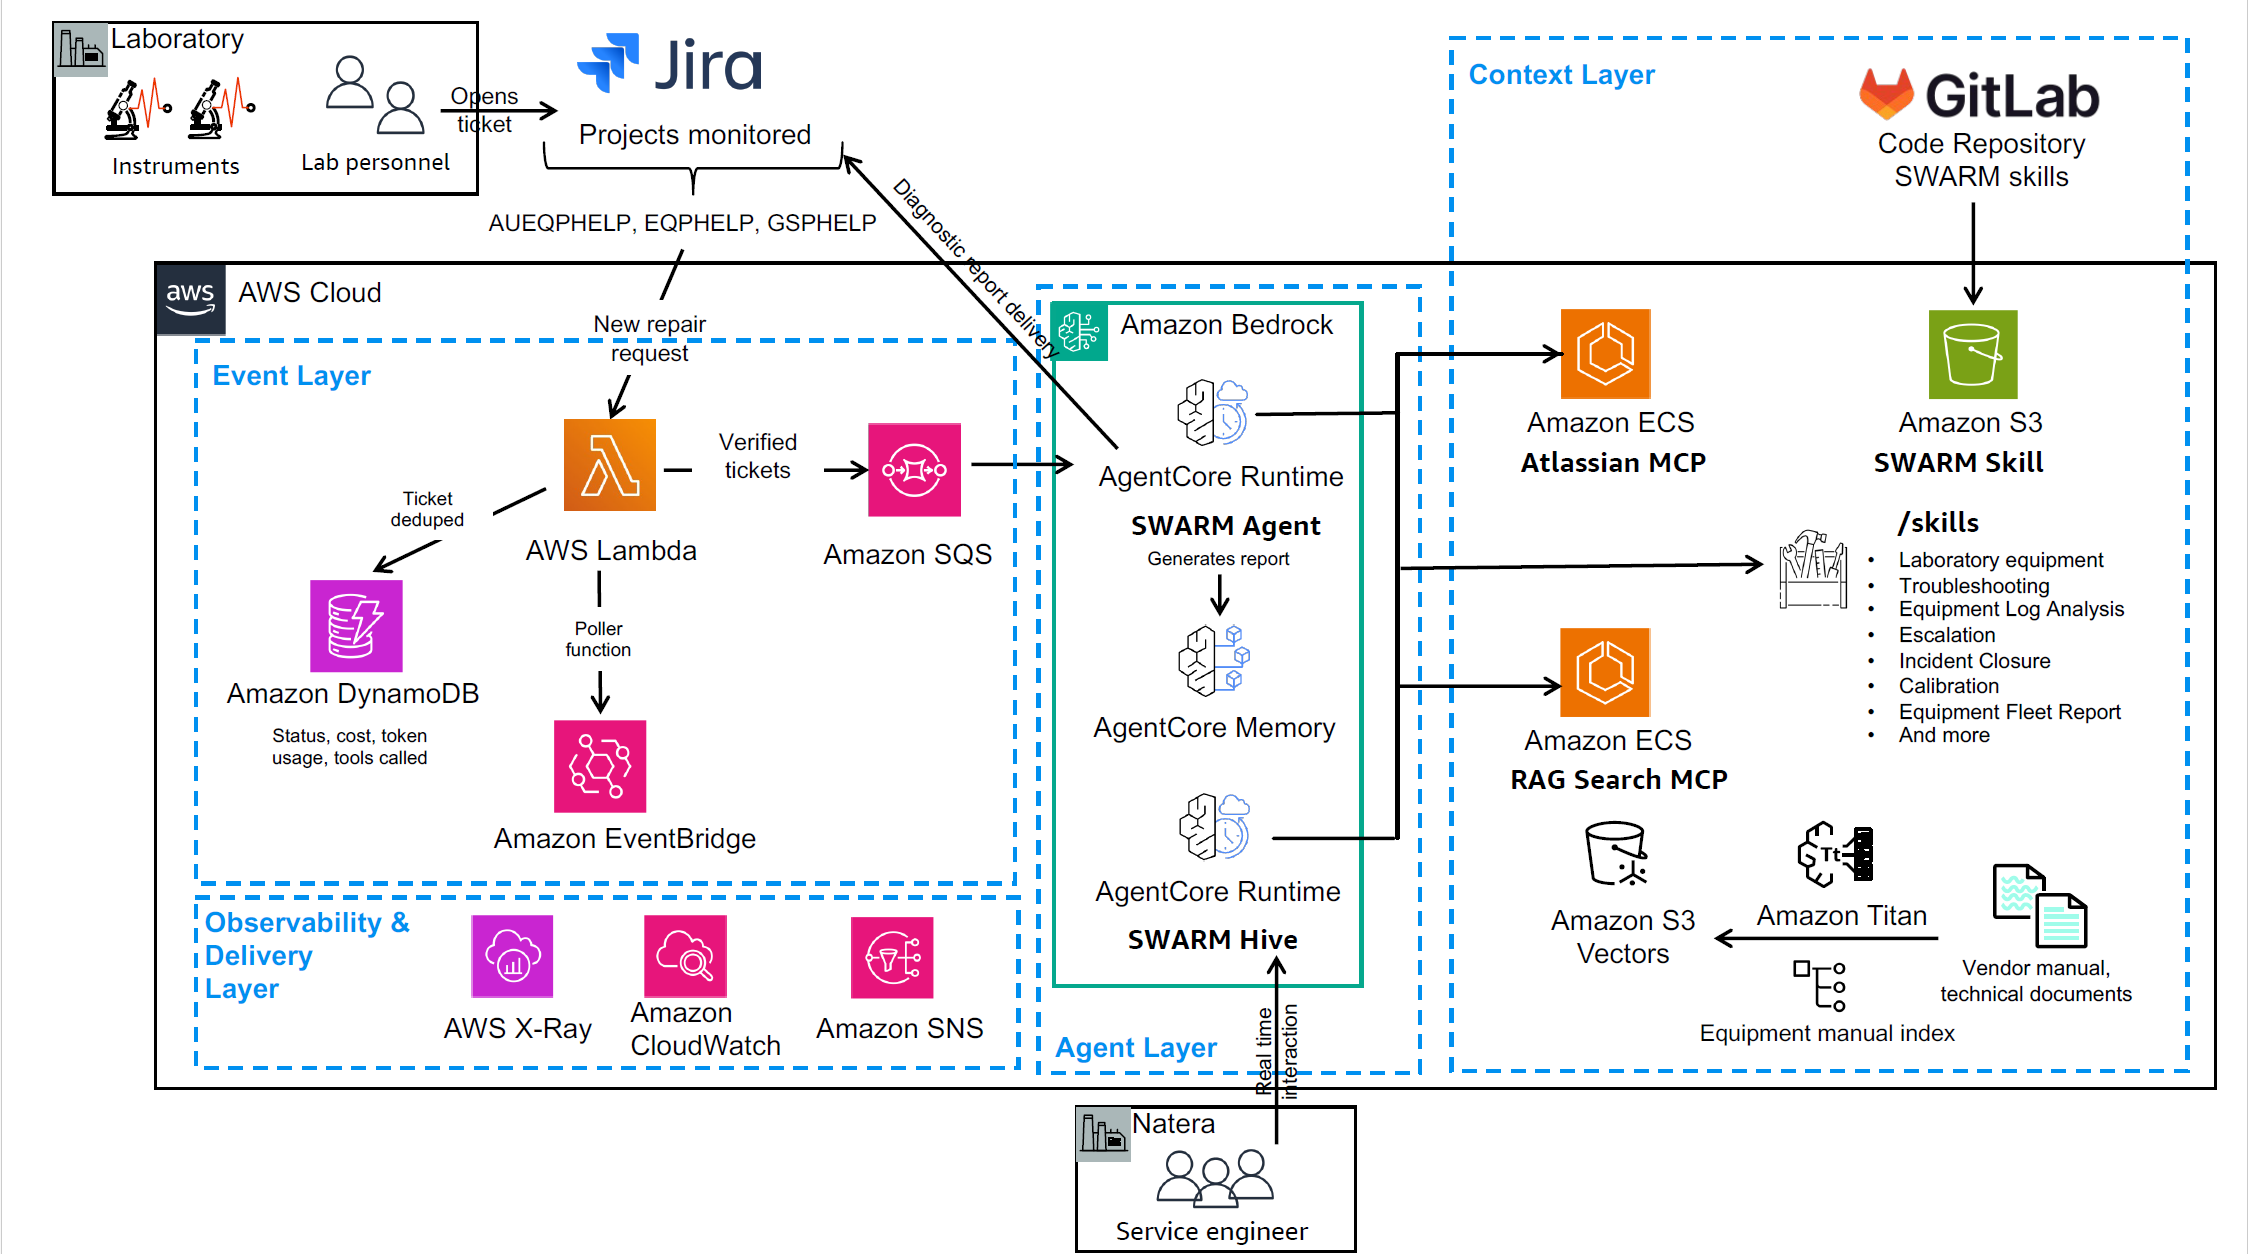
At Natera, a leader in cell-free DNA (cfDNA) testing, keeping lab instruments up and running is critical, because equipment downtime disrupts sample processing. Natera’s lab engineering team, led by Ariel Jirau worked with AWS to build SWARM (Systematic Workflow Analytics and Resolutions Manager), an agentic AI system for lab operations. This post walks through how the Natera team built an a...
Your Amazon Bedrock inference bill can keep climbing after you tune prompts and application logic. Request-level choices can still change how many tokens the service processes and the rate applied to them. Cache duration, service tier, reasoning effort, and maxTokens can affect cost without changing your model or prompt. Each choice depends on the model and workload. This post shows how we t...
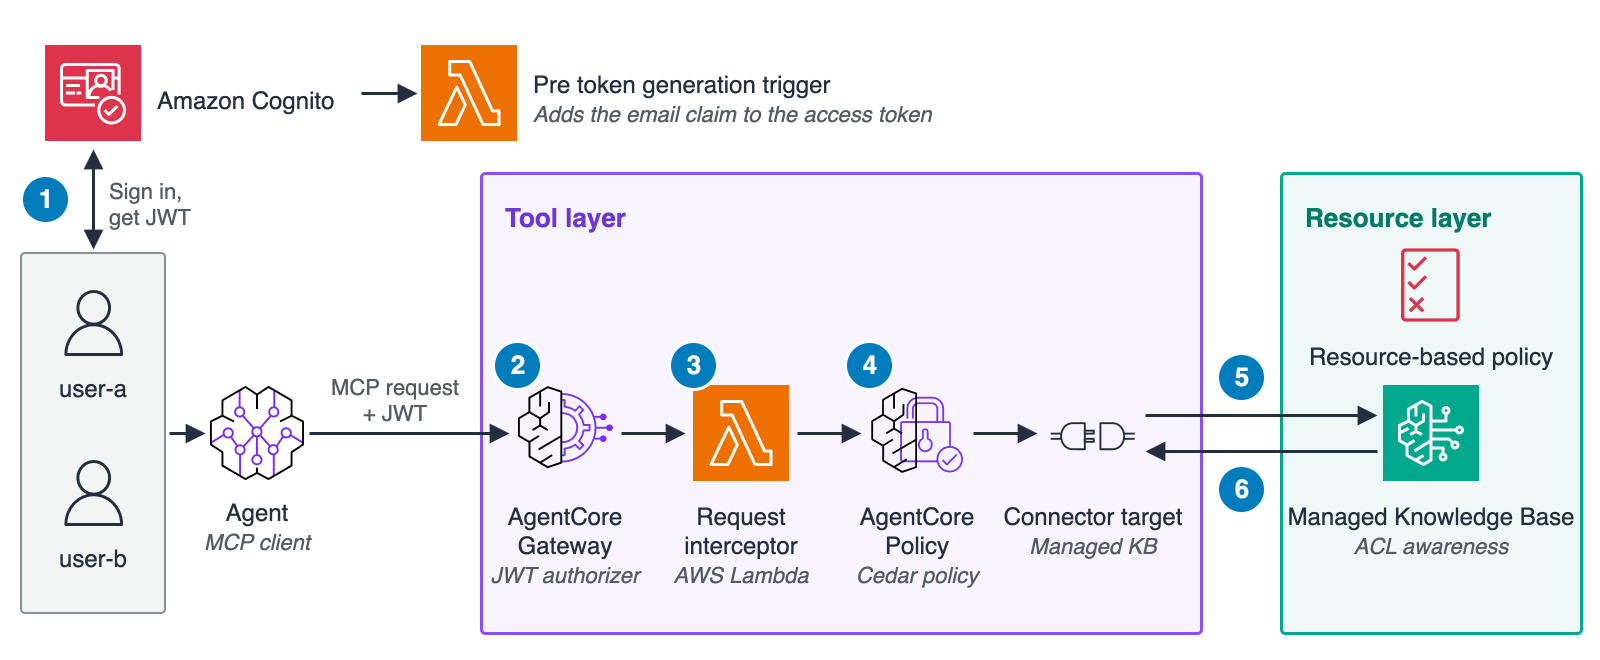
More enterprises are building AI agents into their daily work, and a common pattern is an agent that searches internal documents to compose its answers. A single organization might soon run hundreds of agents, each connected to many data sources and tools. This raises a question. When an agent searches on behalf of a user, can you make sure that it uses only the information that user is allo...
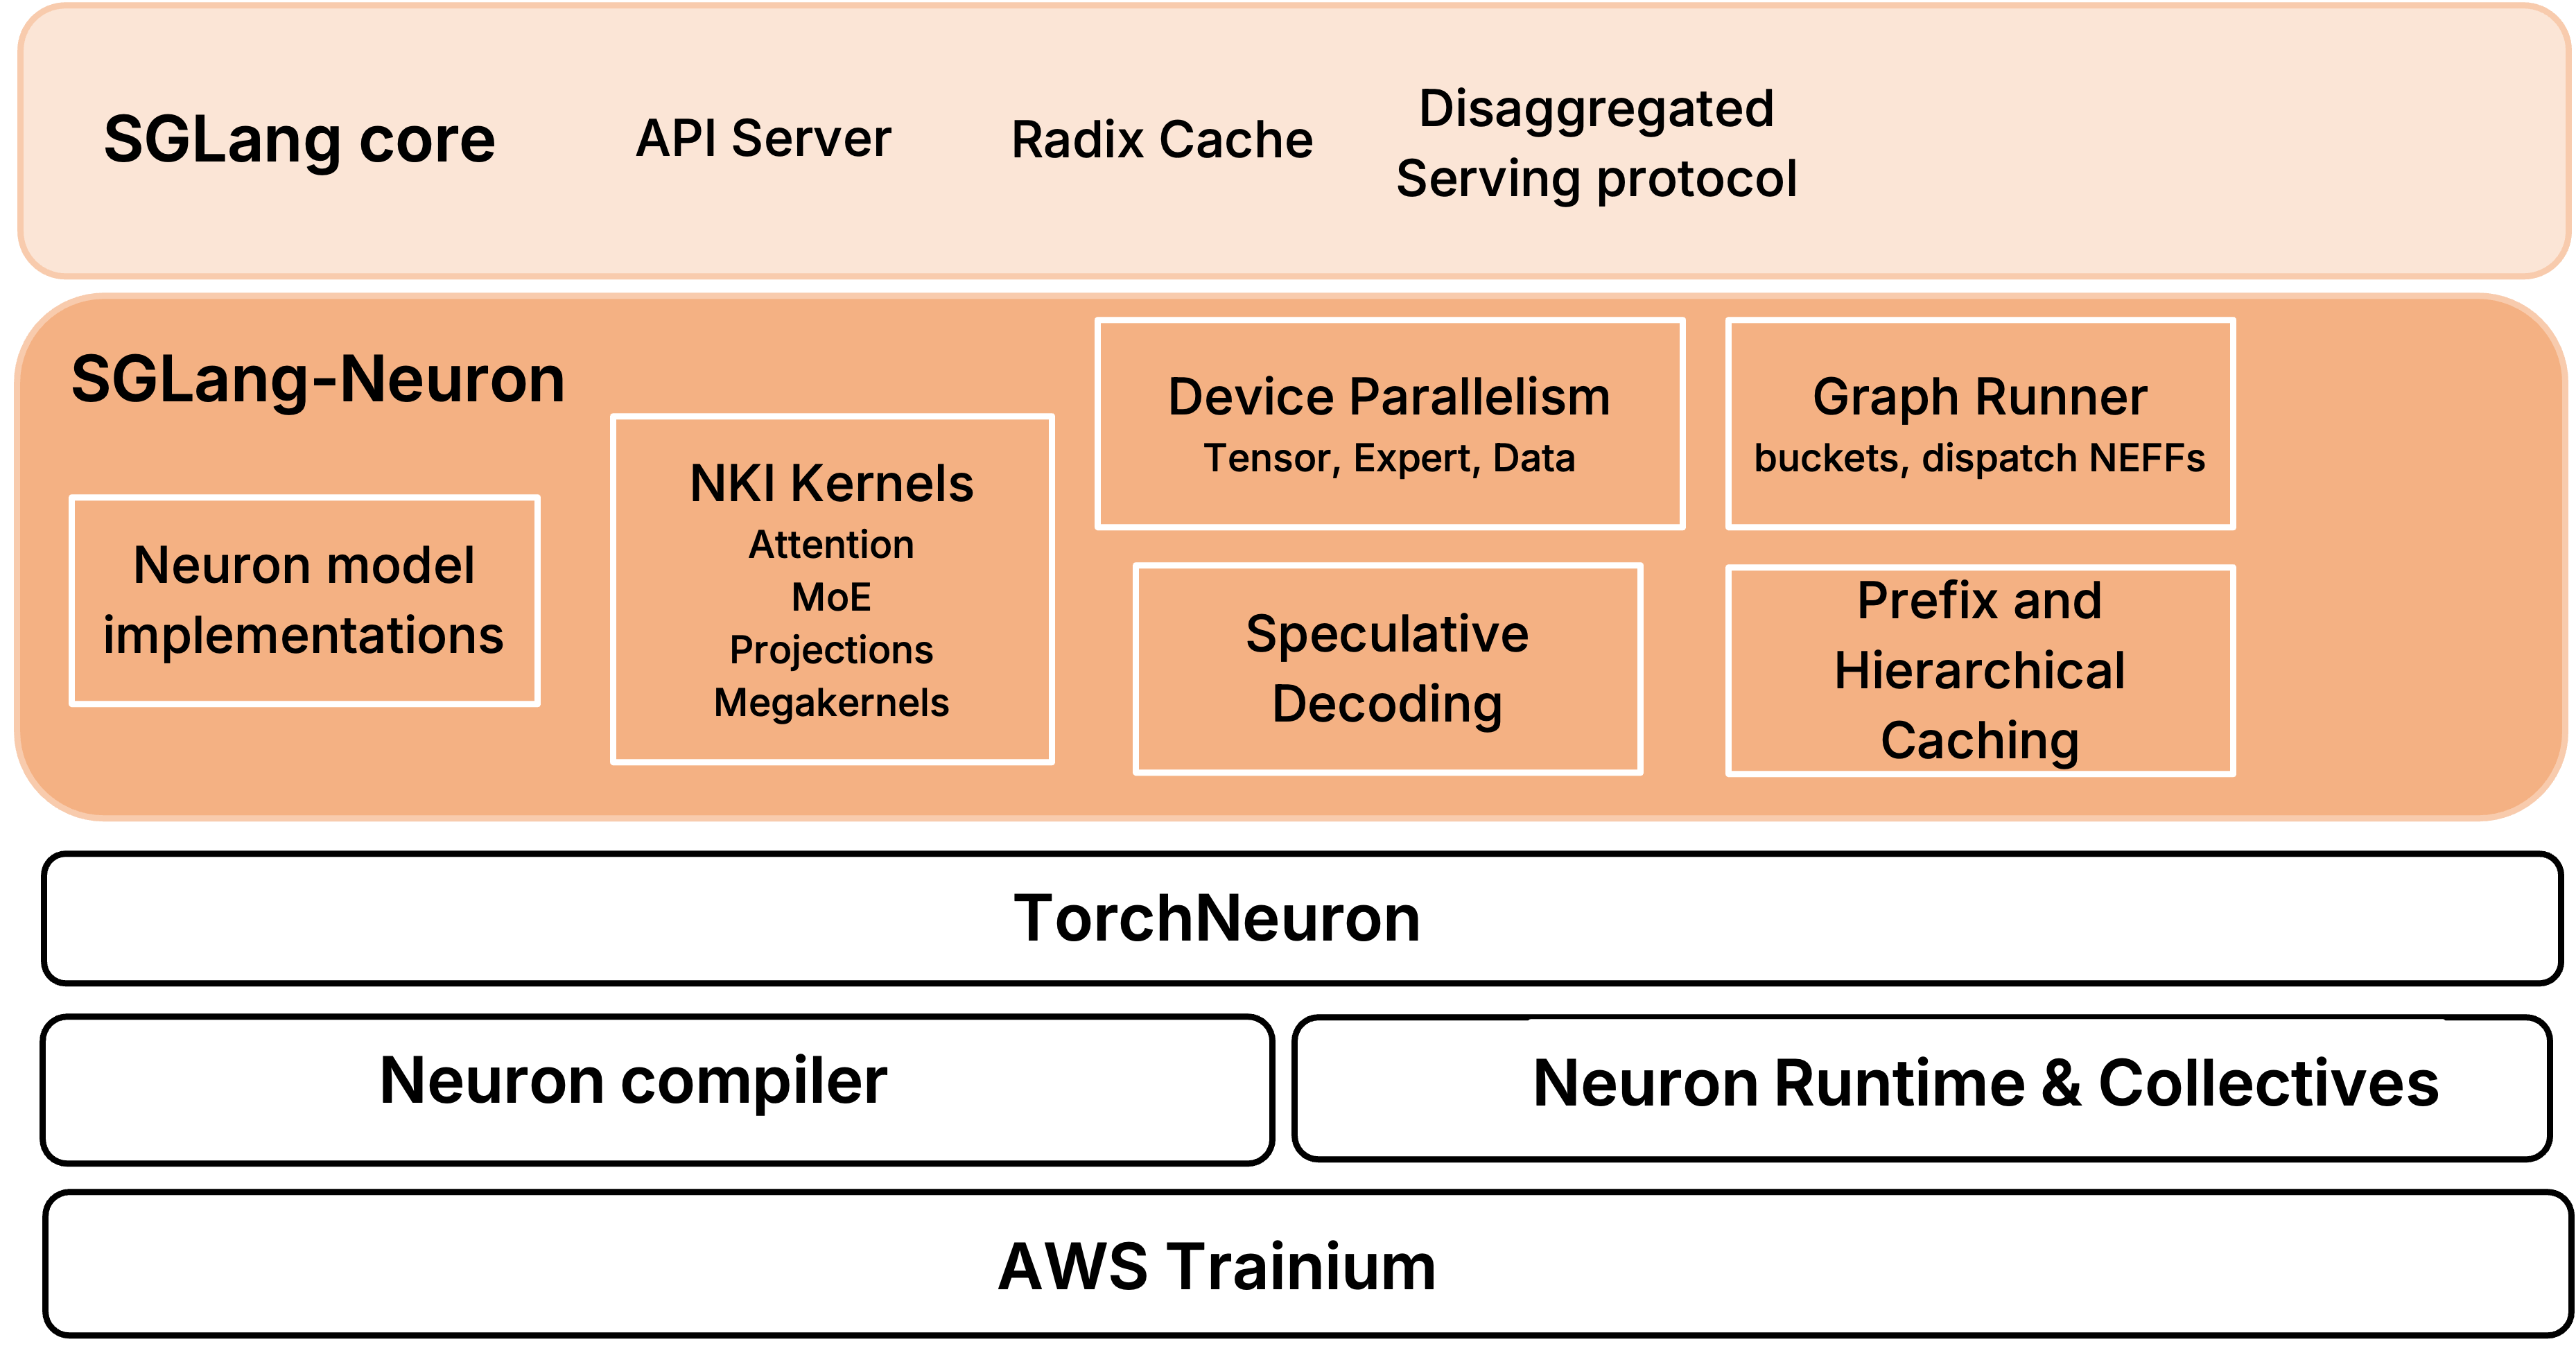
Today, Amazon announced that SGLang-Neuron is publicly available and can be accessed through an AWS Deep Learning Container, released by RadixArk in collaboration with Annapurna Labs. With SGLang-Neuron, you can serve models and generate reinforcement learning (RL) rollouts with SGLang on AWS Trainium using the same SGLang interface you use today. Trainium is a portfolio of AWS AI chips that...
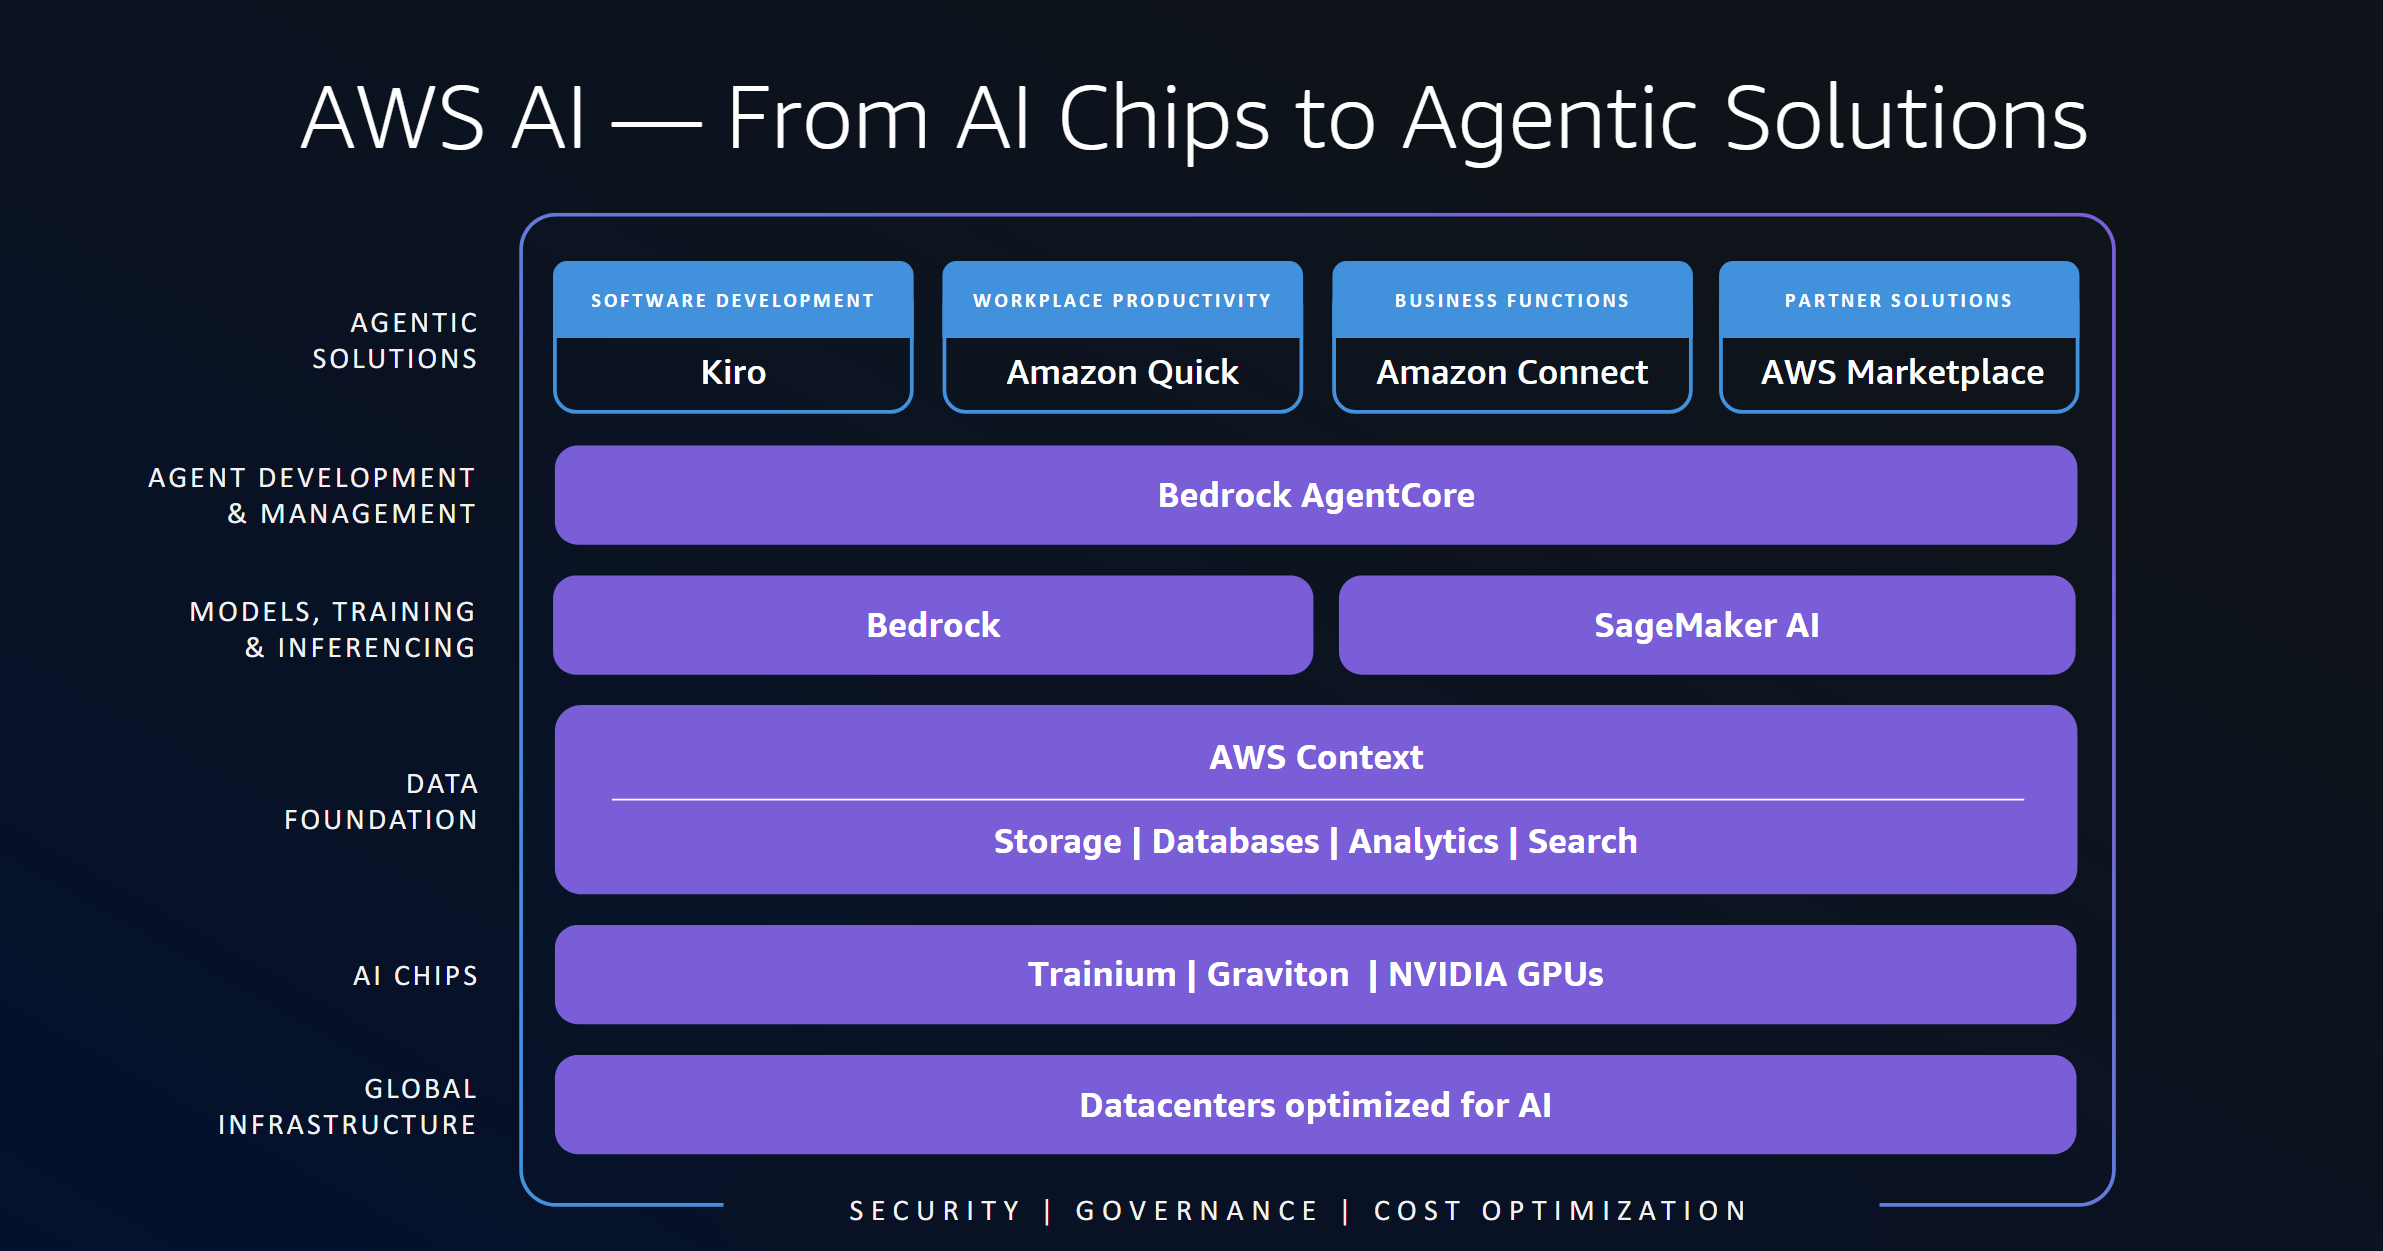
From November 30th to December 4th, Amazon Web Services (AWS) will hold its annual premier learning event: re:Invent. At this event, attendees will become stronger and more proficient in various areas of AWS technology through a variety of experiences: keynotes given by AWS leaders, interactive working sessions led by AWS experts, and fun, immersive activities such as live entertainment and ...
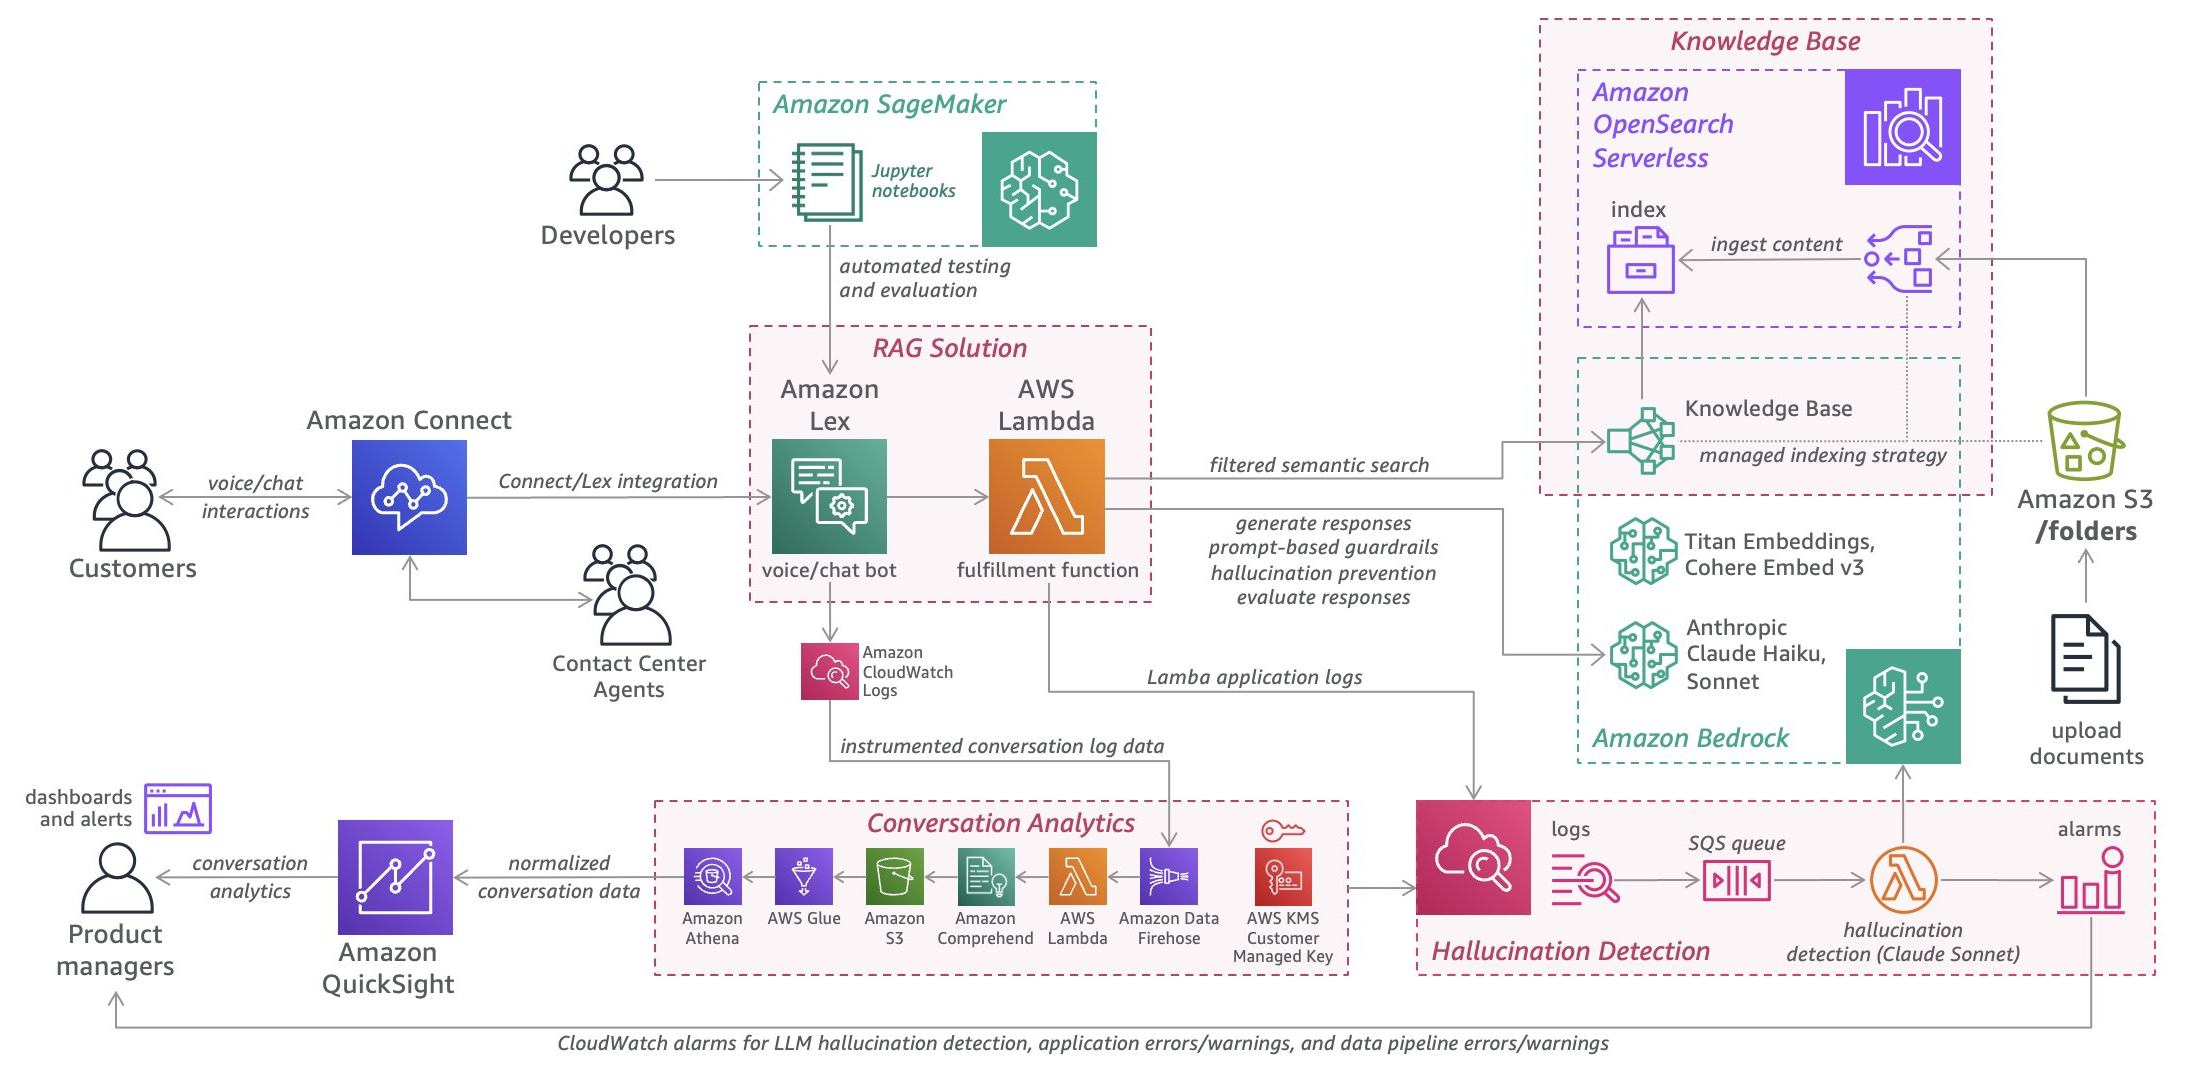
In this post, you will discover how reusable assets from the AWS Generative AI Innovation Center can help reduce development time and costs for generative AI solutions. These assets, including Retrieval Augmented Generation pipelines, document processors, and agent scaffolding, can save teams months of development time as shown by companies like DoorDash, Lyft, and Ricoh. The post also explains...
Overcoming Unnoticed Data Corruption in Amazon SageMaker HyperPod: Detection and Recovery Strategies
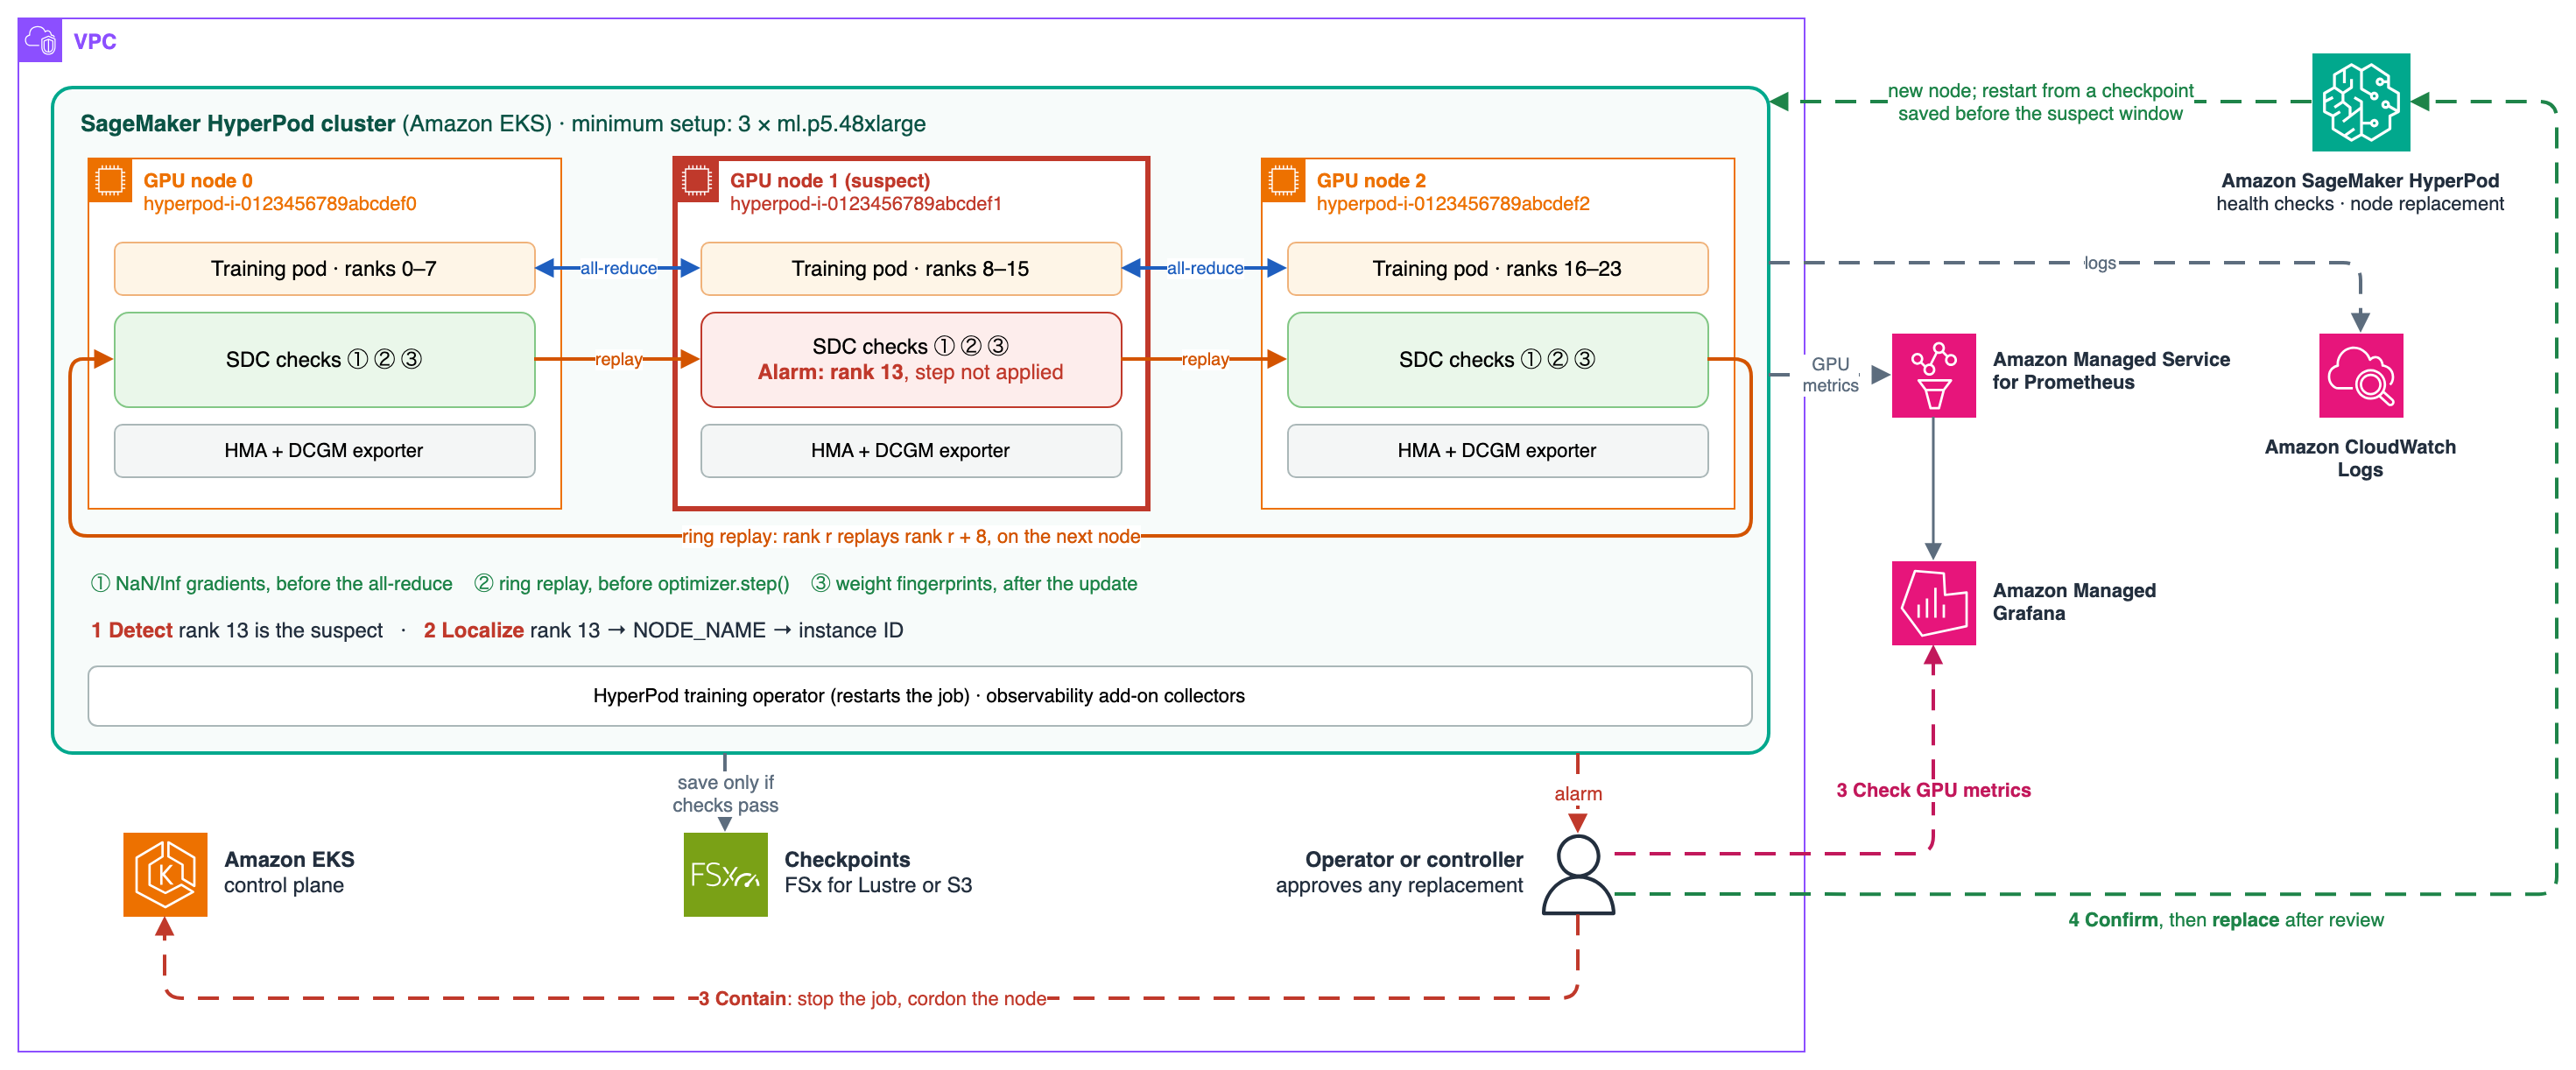
Silent data corruption (SDC) in machine learning training occurs when hardware, such as a GPU, returns incorrect but plausible numbers without raising errors. This can lead to the propagation of incorrect data into gradients and weights in distributed training, resulting in a weaker model or unexplained divergence. Detection of SDC is challenging as it does not trigger hardware errors and can s...
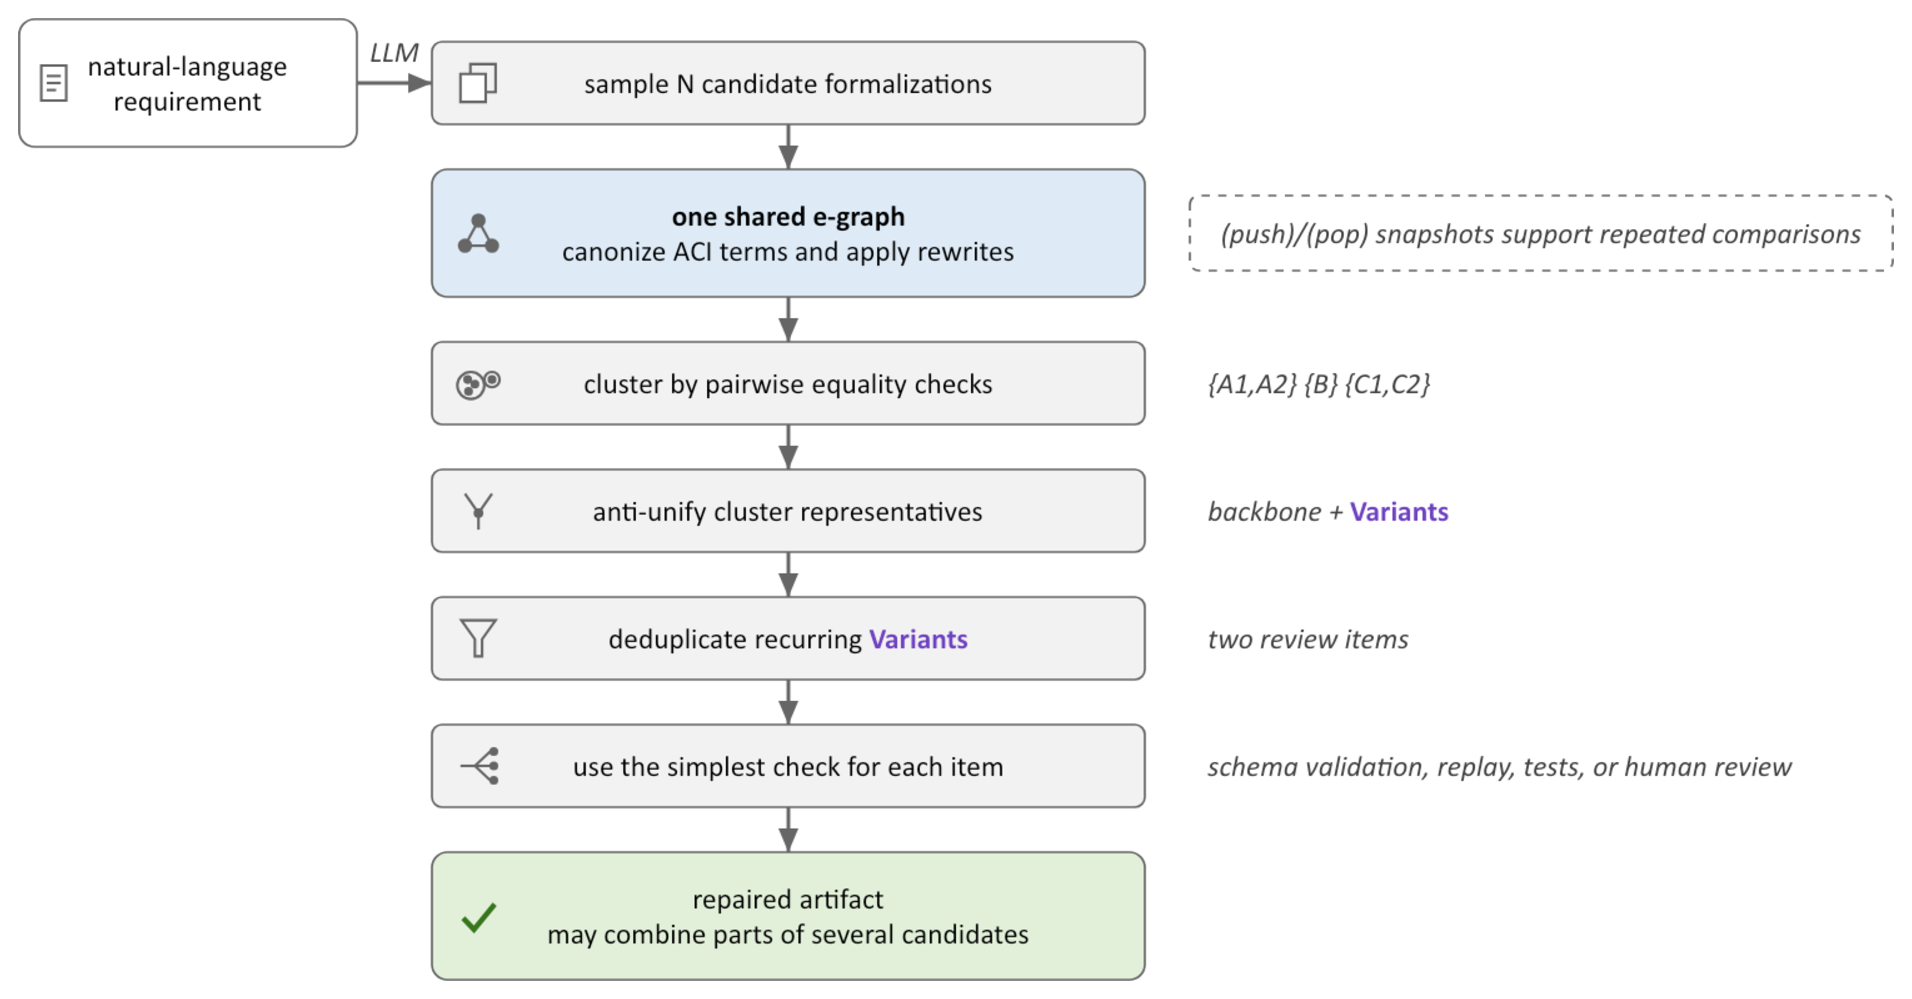
In code review, using a textual difference between files can be misleading due to syntactic changes that don't affect meaning. A semantic diff, computed using anti-unification, identifies shared parts and disagreements between policies. This is useful when generating formal language models from natural language or comparing different policy formats like Cedar, Dogwood, or OpenShell policies. Ag...
Moonshot AI's new post-trained version of Kimi K3.1, named Kimi K3.1 Pro Highspeed, is now accessible on Amazon Bedrock. With the same open-weight architecture and context window, this upgraded model benefits from additional post-training compute, focusing on long-horizon tasks and reducing factual errors. It enhances professional functions, including financial modeling and document processing,...
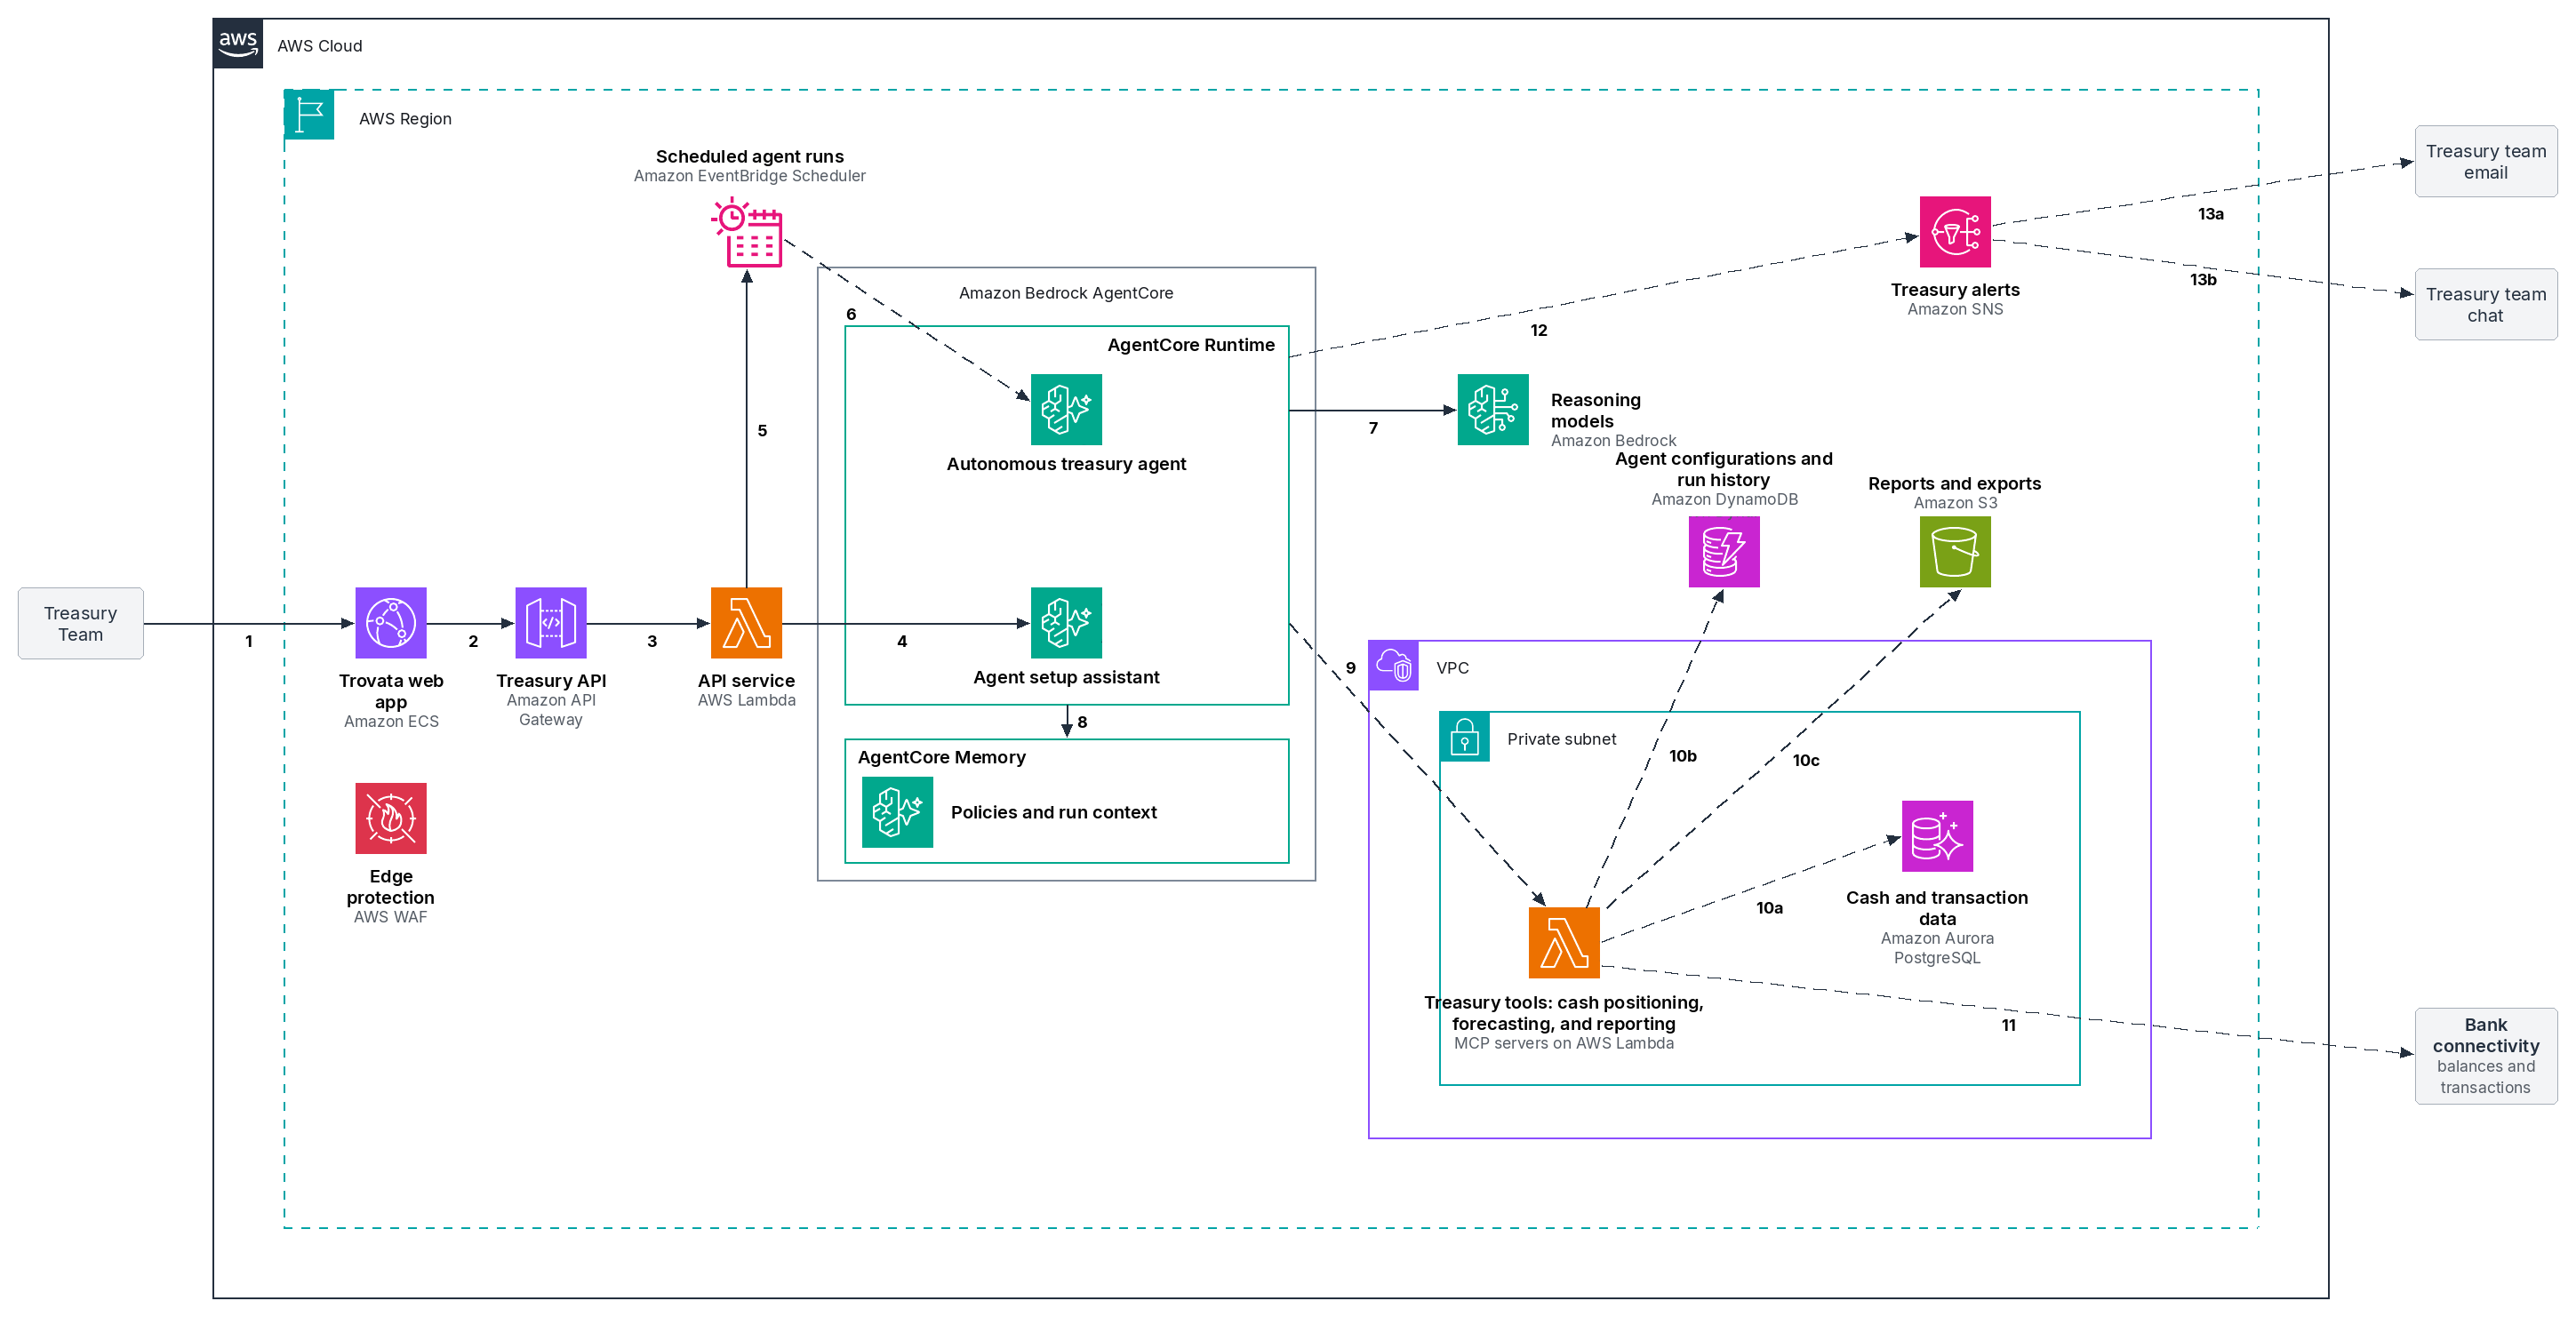
Trovata is an AI-driven platform for corporate cash and liquidity management, offering direct access to over 10,000 banks through a single system. Treasury teams face challenges with fragmented banking data, manual reporting, and outdated Treasury Management Systems (TMS). Trovata's innovative solution addresses these issues by introducing autonomous agents that act on behalf of treasury teams,...
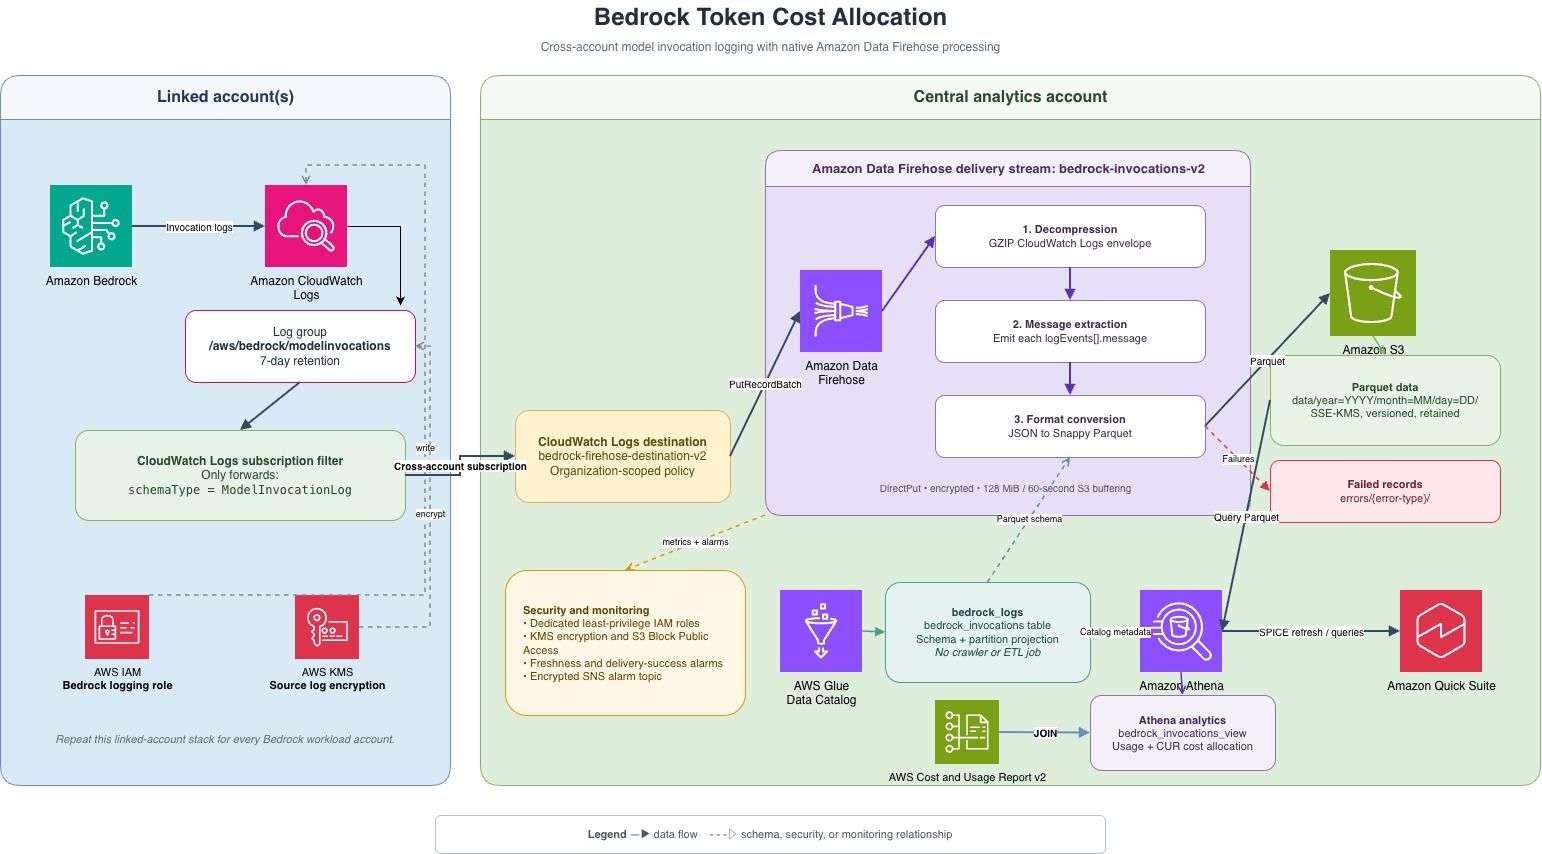
In this summary, I will describe a solution for observability data lake needs in Amazon Bedrock workloads. When running multiple model invocations daily across different accounts, it becomes challenging to understand what happened after a request was sent. Questions arise, such as which prompt was used, the model response, token usage, handling model, and response quality. As a platform or ML e...
In the given study, the author explores the performance of two encoding techniques for tree-based machine learning models, focusing on gradient boosting regression with decision tree weak learners. The first technique, referred to as super simple, uses ordinal encoding for categorical variables. The second technique, referred to as complex, employs smoothed-target encoding for continuous variab...
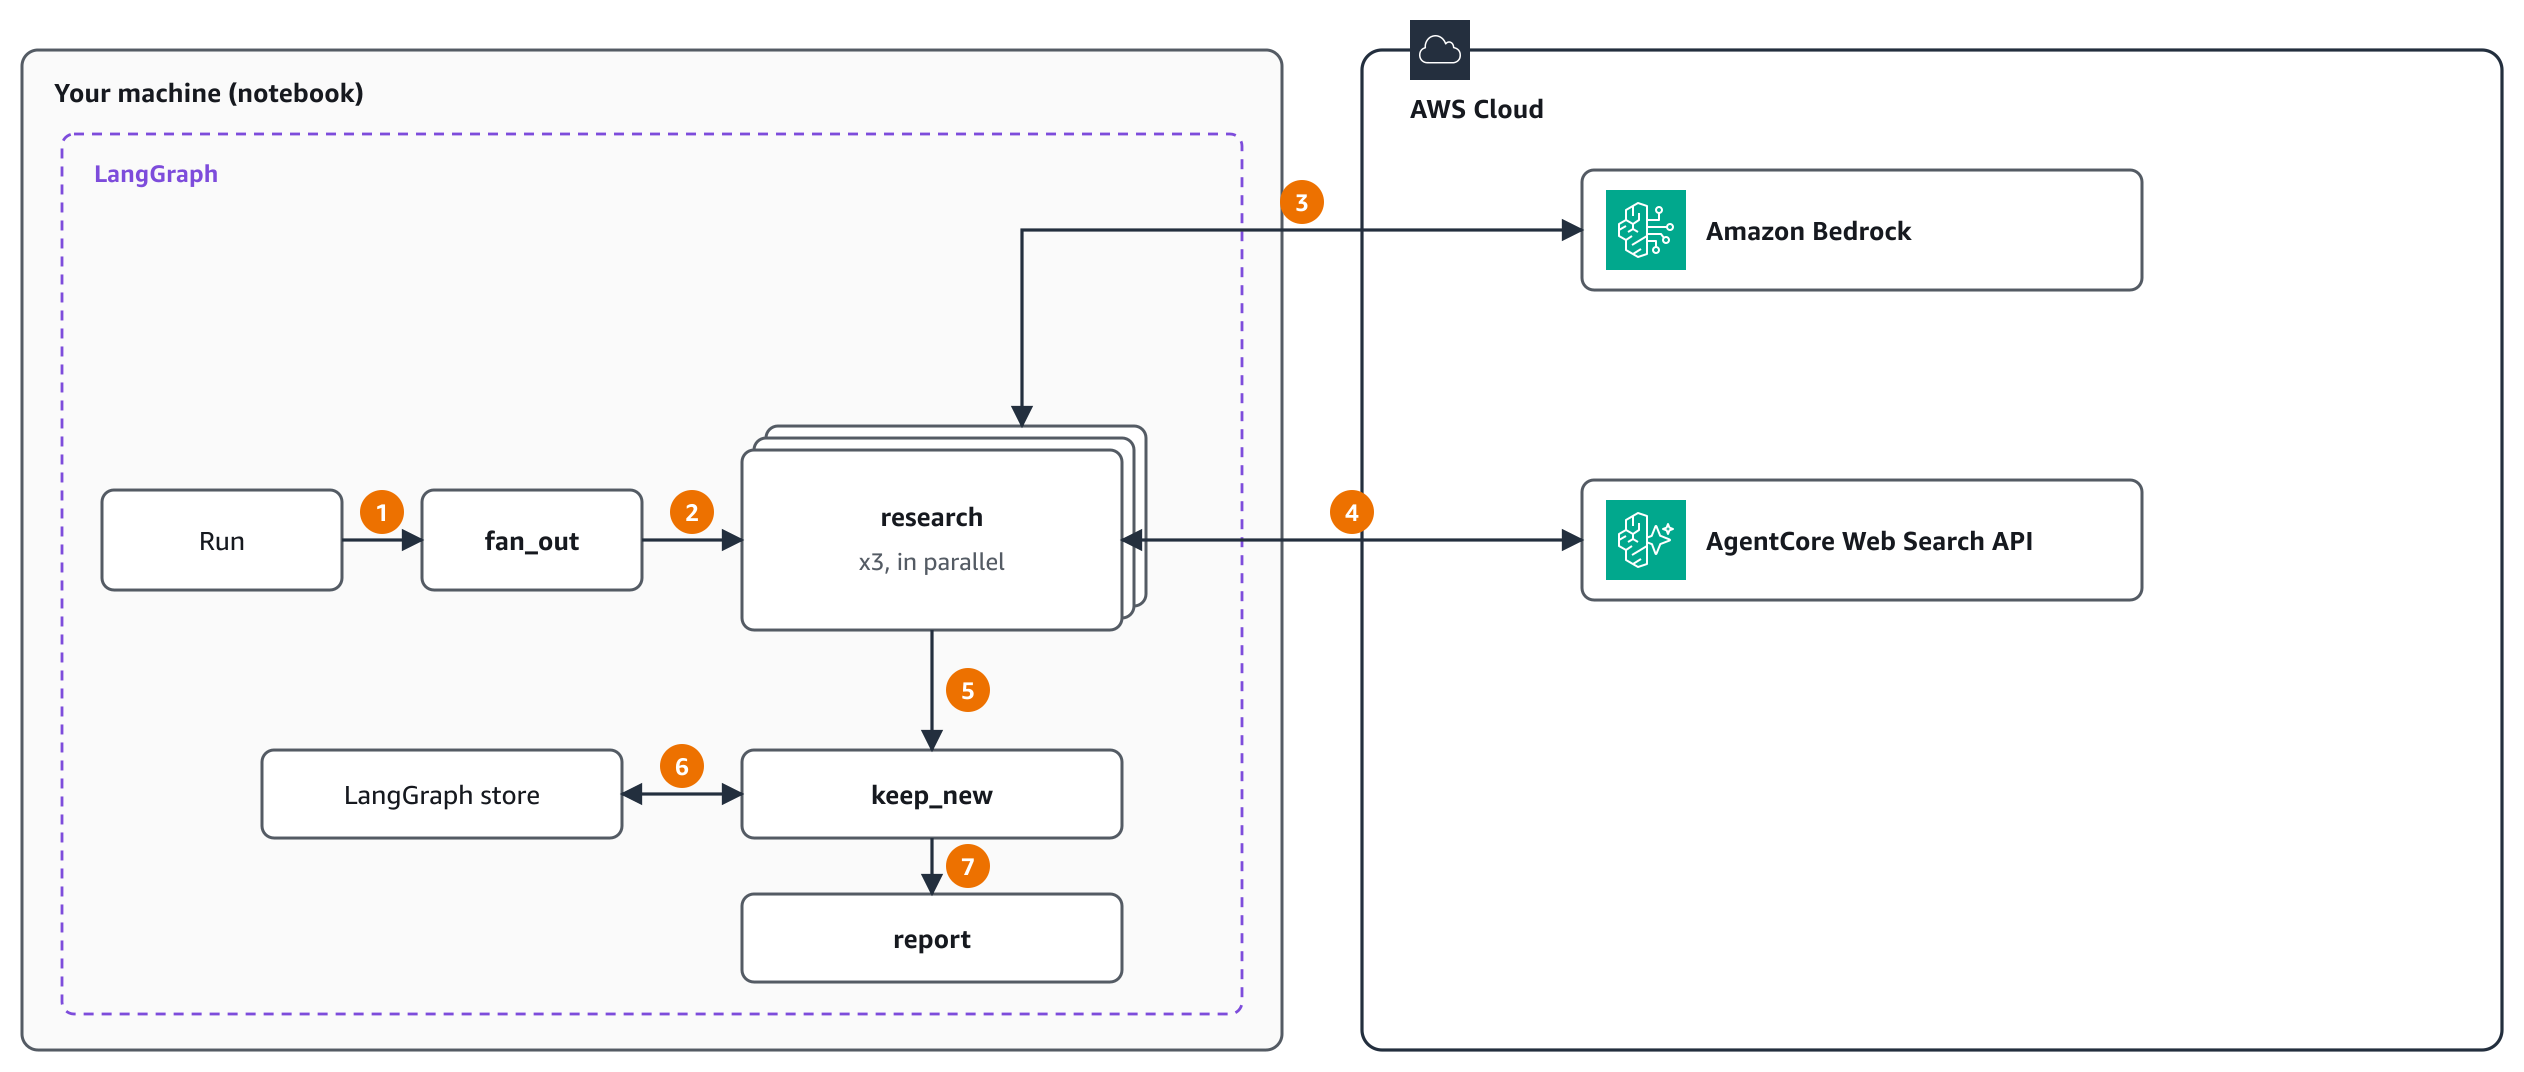
In this summary, we highlight Amazon Bedrock AgentCore's new feature, the Web Search API. This API enables AI agents to access current web results through a single API call, using their existing AWS credentials. The results include titles, URLs, publication dates, and extracts relevant to the query, while users can also specify domain restrictions and publication date ranges. The Web Search API...
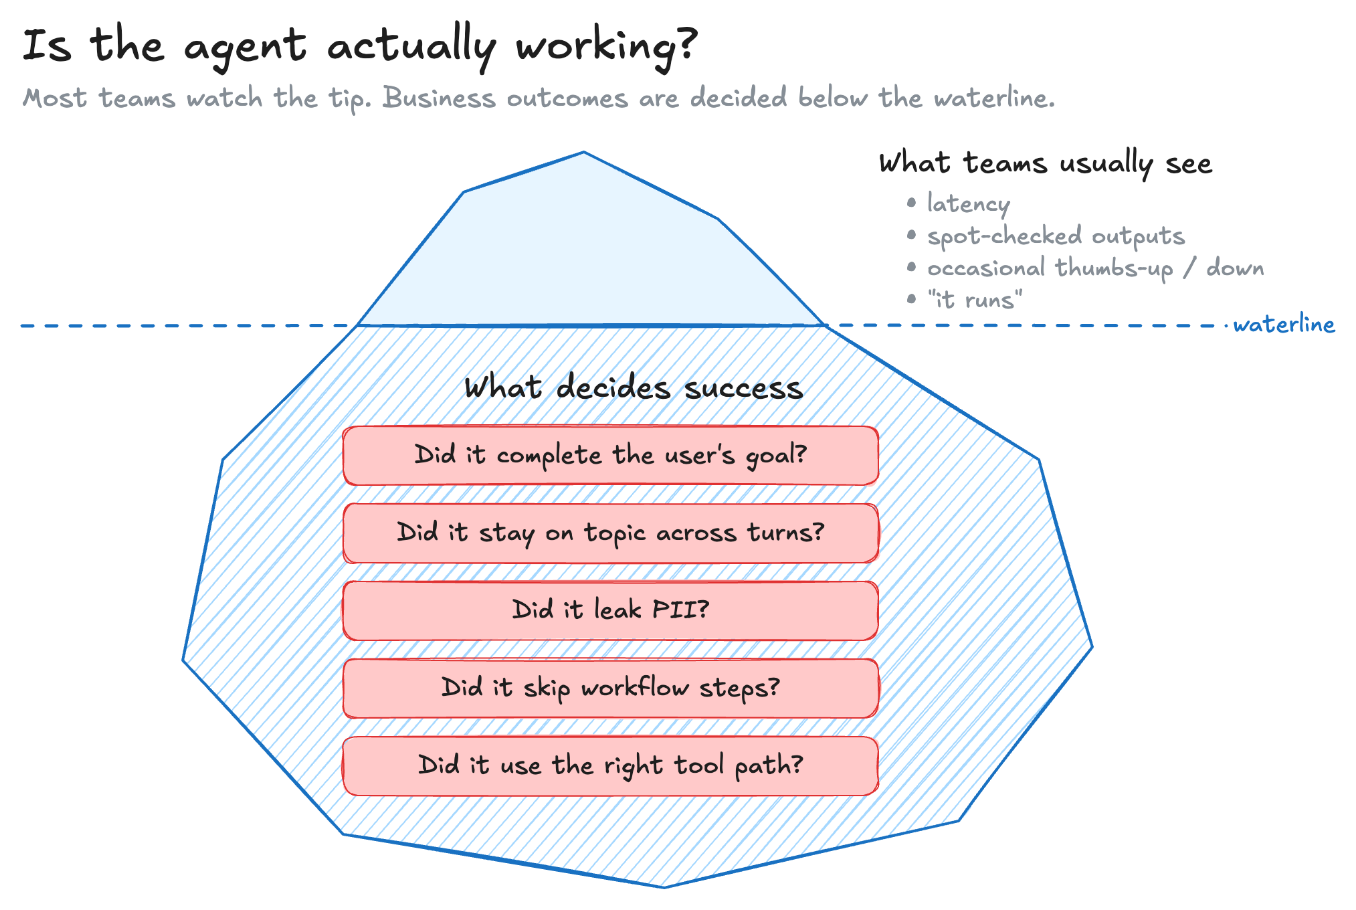
When deploying an agent in production, ensuring it's effectively meeting business requirements at scale is a common challenge. Teams often rely on surface signals such as completion rates and latency, but these do not provide insight into whether the agent is finishing tasks, staying on topic, leaking PII, or accurately following intended steps. This issue is addressed through agent evaluation....
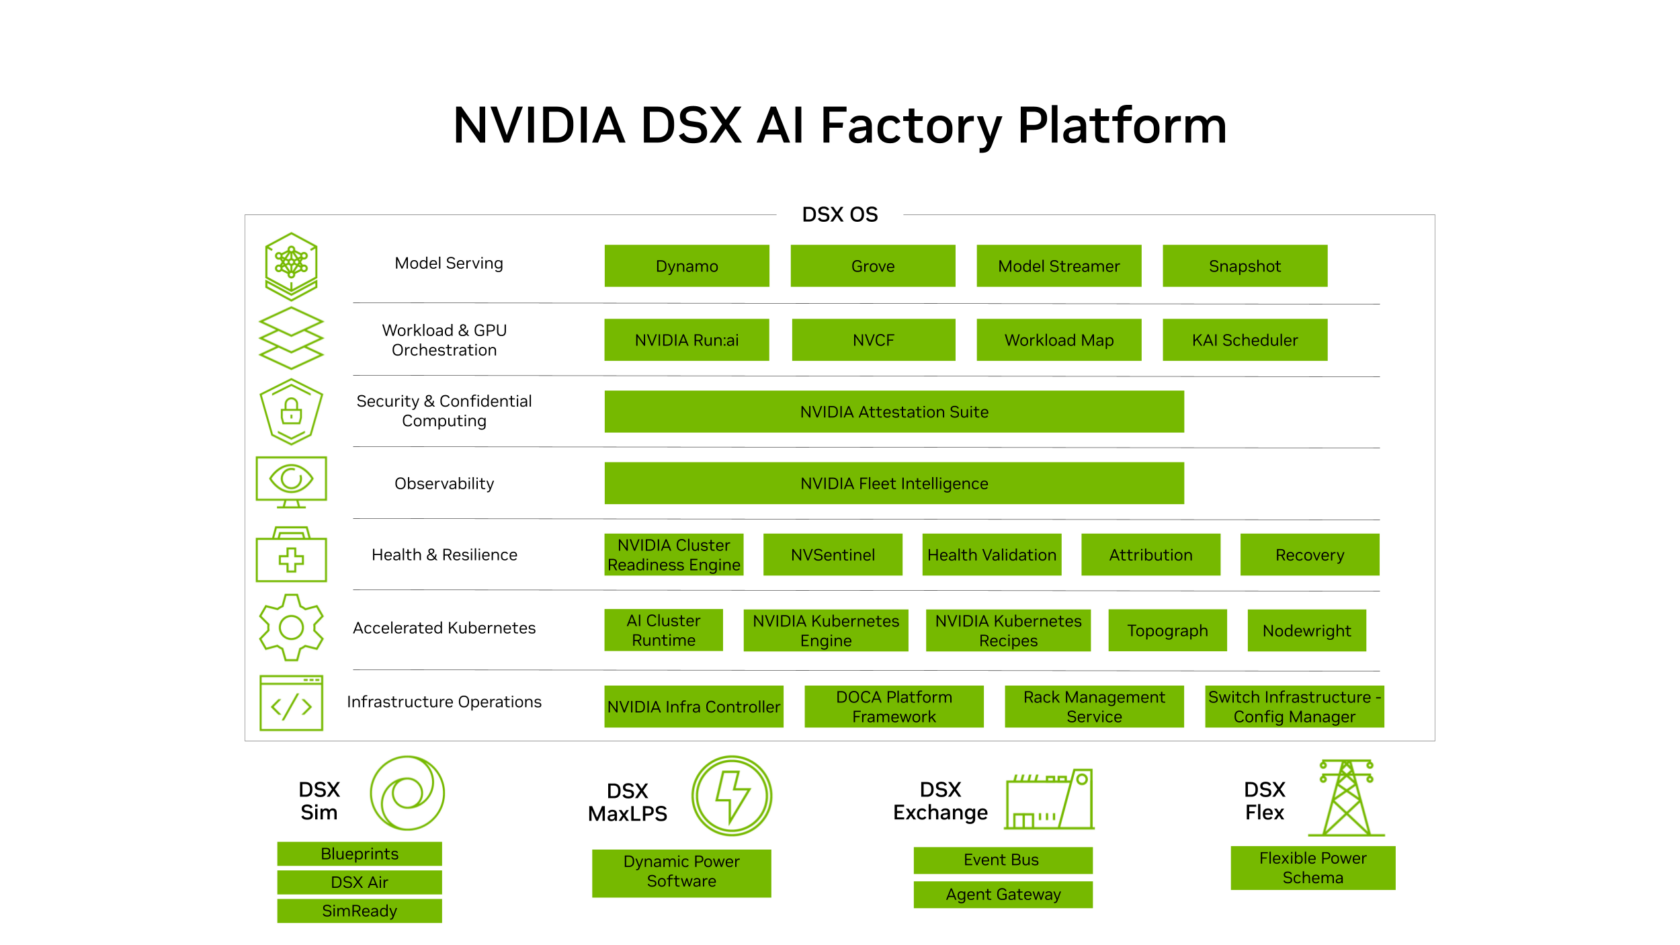
NVIDIA is strengthening its commitment to the open source Kubernetes system, which manages applications across thousands of AI factories, by contributing new tools to enhance security and scaling at the KubeCon + CloudNativeCon conference. NVIDIA is contributing NVIDIA OpenShell, an open source runtime for securing and governing autonomous agents, to the Cloud Native Computing Foundation (CNCF)...