

NVIDIA AI for Media enhances broadcast and production workflows with real-time intelligence at IBC 2026. Dalet, TwelveLabs, and Wowza integrate NVIDIA's Synthetic Video Detector for content verification and compliance in media and entertainment industries.
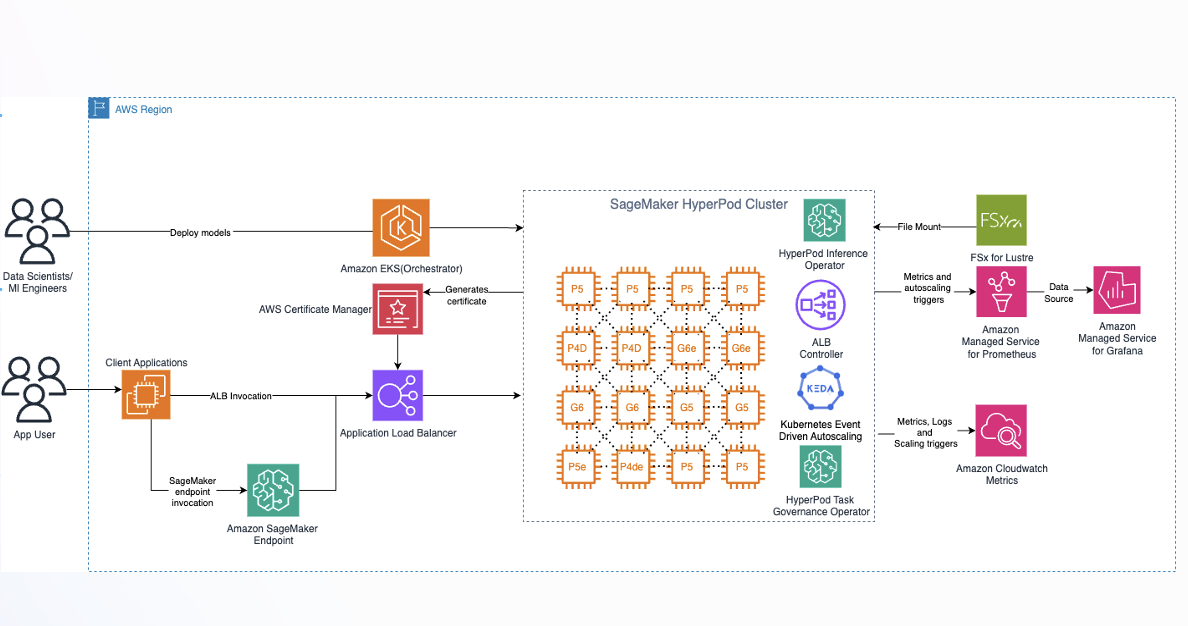
Alibaba's Qwen team released Qwen3.8-2.4T-A95B, the first open-weight Qwen-Max-class model with 2.4 trillion total parameters for demanding agentic and reasoning tasks. Deploying on Amazon SageMaker HyperPod enables customized inference behavior and native Multi-Token Prediction for speculative decoding.
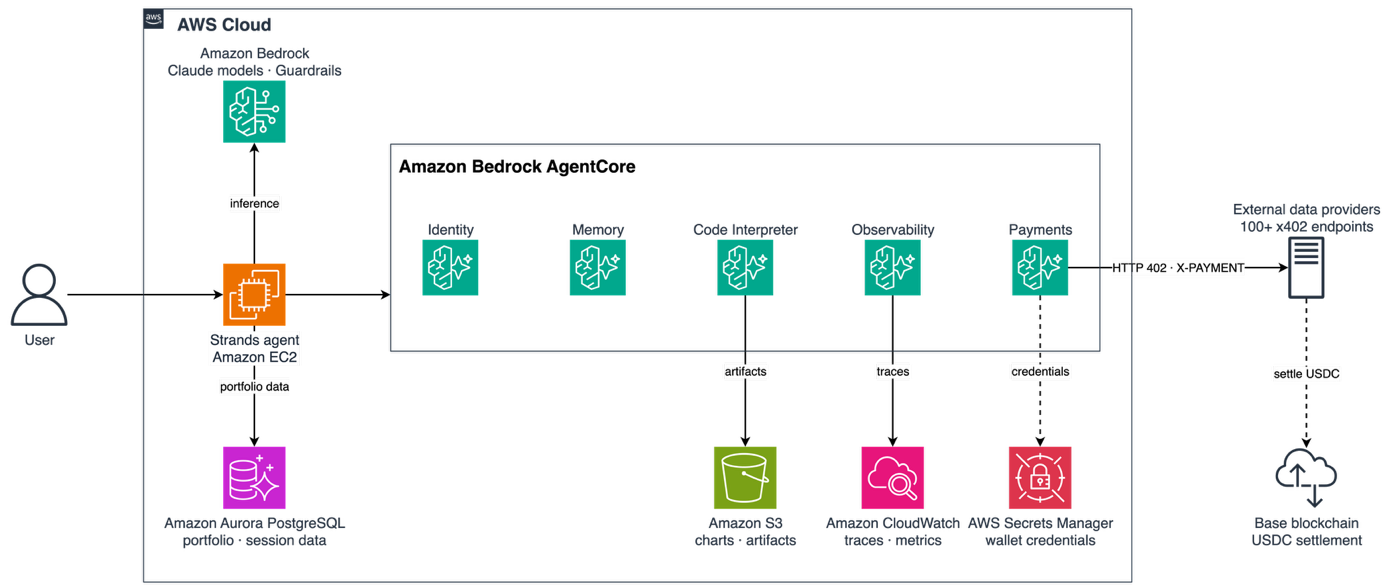
Heurist uses Amazon Bedrock AgentCore to create AI-powered financial intelligence for retail investors in a unified chat experience. By leveraging AgentCore payments, Heurist provides access to premium data per query, making complex financial tools accessible to all.
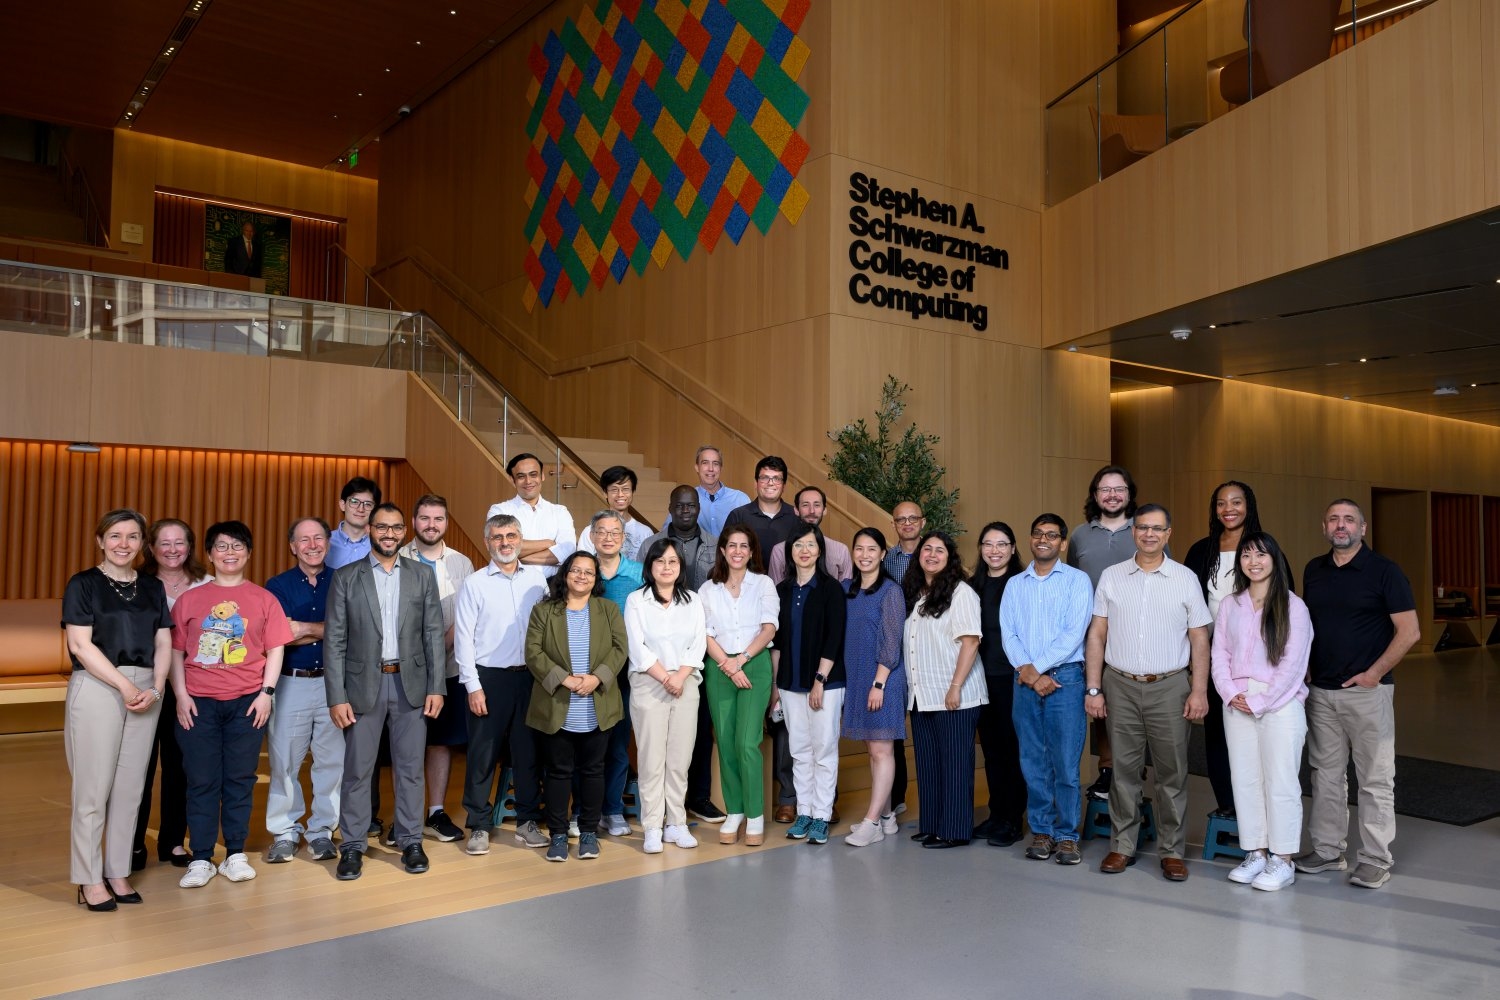
MIT hosted AI Educators Pilot workshop to expand AI education, empowering instructors to teach foundational concepts across disciplines. Collaborative effort involved faculty from various universities adapting MIT's Modeling with Machine Learning course materials for their classrooms.
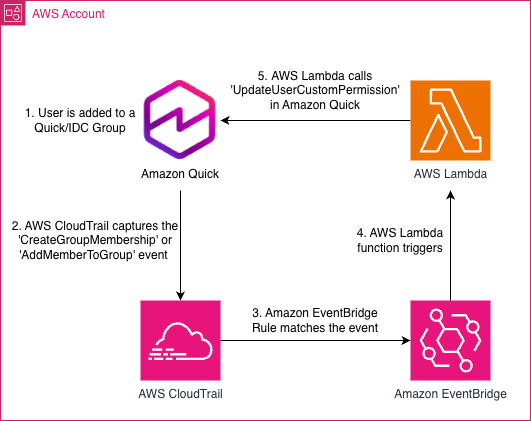
Automating custom permissions in Amazon Quick ensures fine-grained access control for users. Four architectural patterns automate custom permissions at key stages of the user lifecycle.
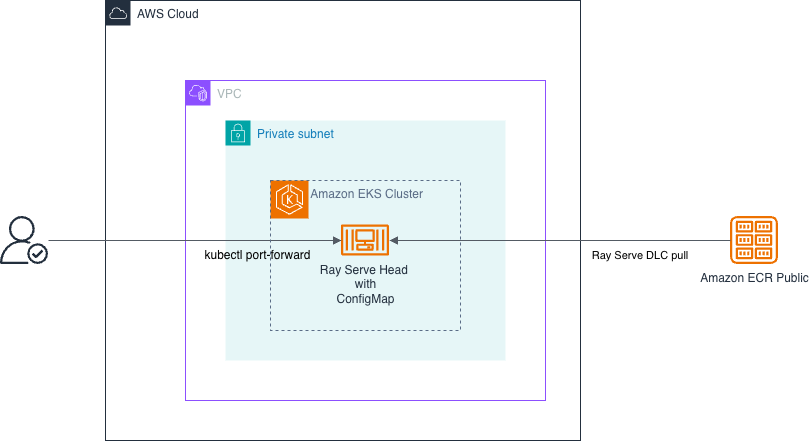
TorchServe is no longer maintained, leaving teams to handle security patches and compatibility issues. AWS introduces Ray Serve DLC for efficient model inference deployment on AWS platforms, streamlining the process with pre-built Docker images.
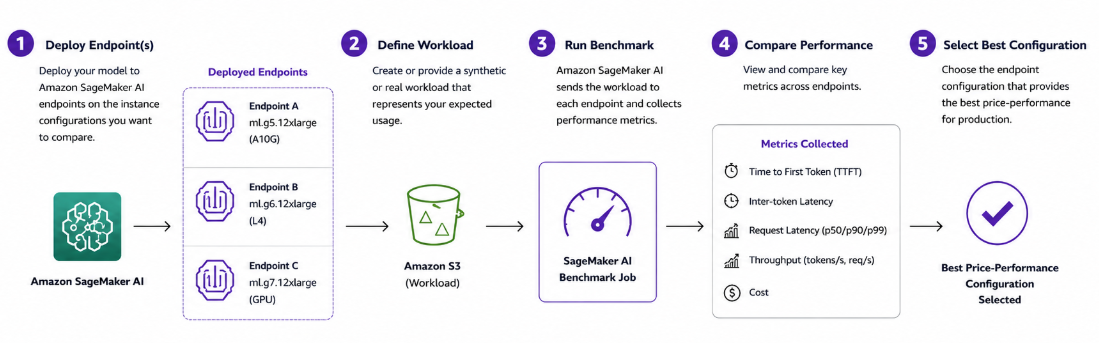
Choosing the right GPU instance for large language model inference is crucial for deploying generative AI at scale. Benchmarking shows how the new G7 instances deliver gains in throughput, latency, and cost-per-token for enterprise coding and reasoning tasks.
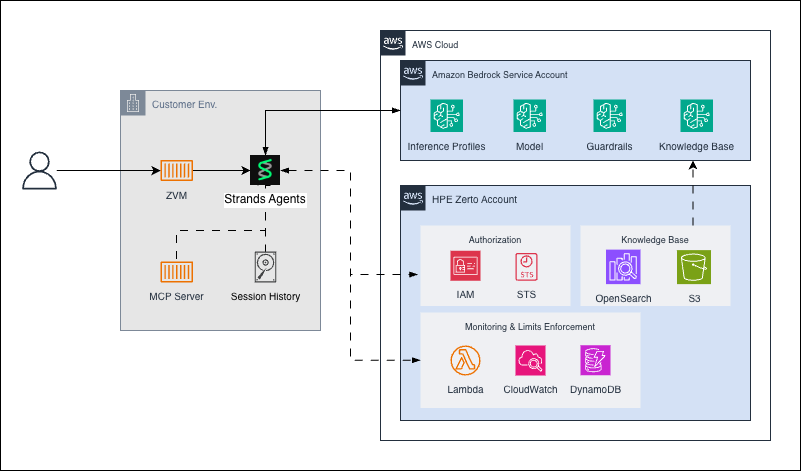
HPE Zerto teams up with AWS to create an AI-powered agentic troubleshooting system for hybrid and multi-cloud infrastructures. The system provides natural language support for faster recovery decisions, reducing data loss and downtime.
Pathway's brain-inspired BDH offers a new approach to AI reasoning, avoiding traditional sequential token generation. Amazon SageMaker HyperPod helps scale out training for models like BDH, addressing limitations of transformer architecture.
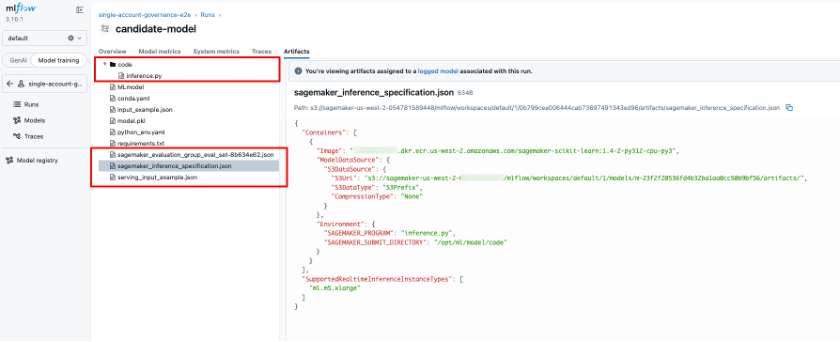
Automating model registration between MLflow and the SageMaker AI Model Registry streamlines governance and lifecycle management for data scientists and governance officers. The richer sync now includes training metrics, evaluation results, lineage, and lifecycle stage promotion, simplifying the process of moving models from staging to production seamlessly.
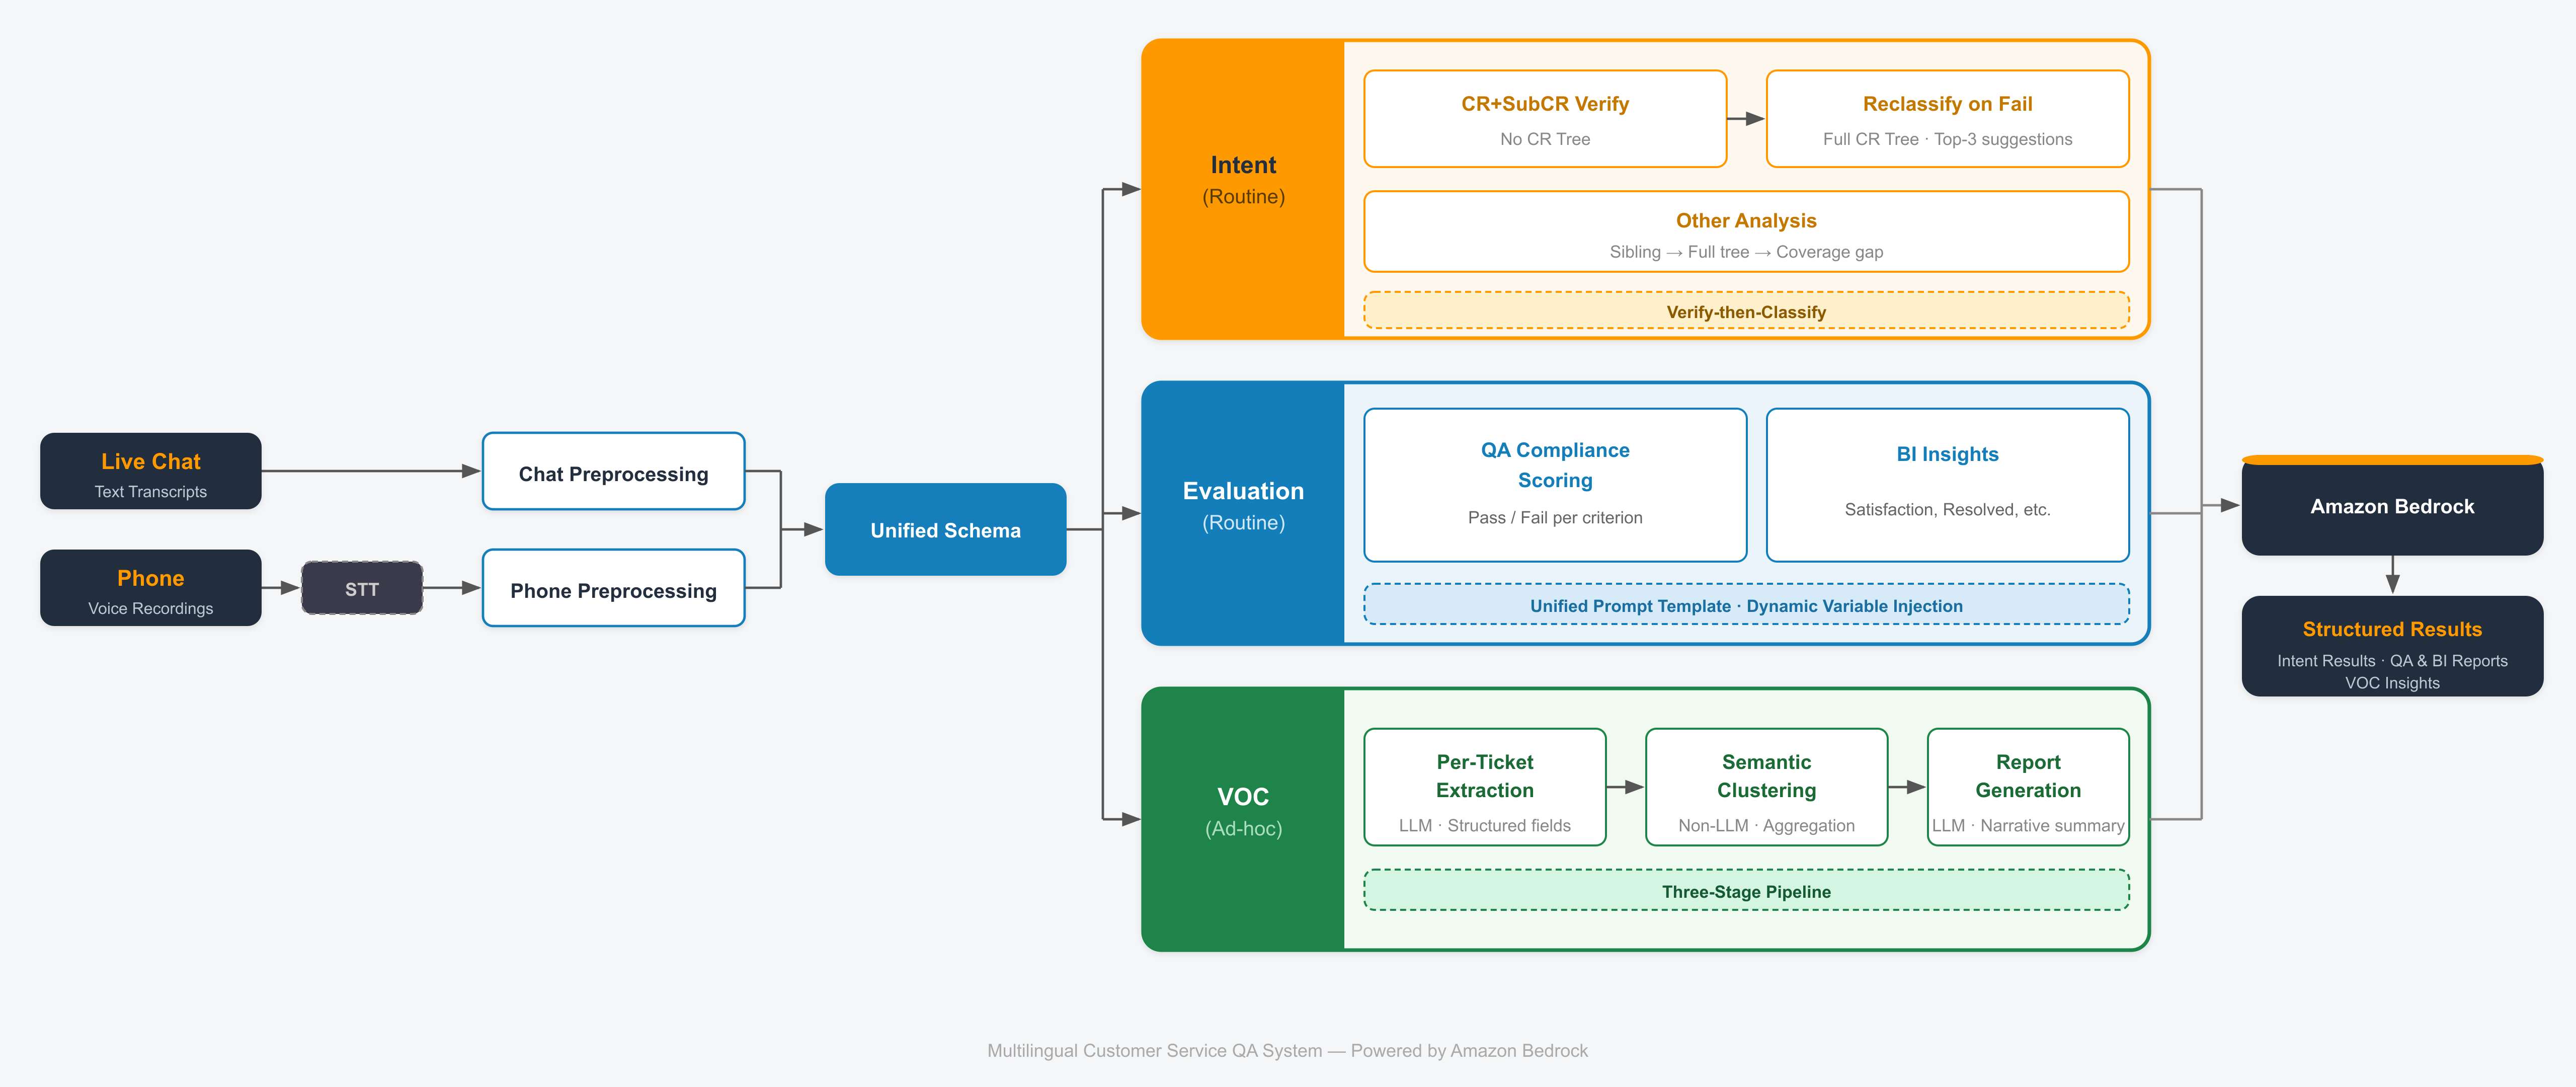
DiDi and AWS collaborated to develop a transparent AI-driven contact center QA system on Amazon Bedrock, enhancing accuracy and efficiency in intent verification, compliance evaluation, and VOC analysis. DiDi IBG's CX department overcame challenges of traceability, combinatorial complexity, QA standard changes, and trend detection to improve service quality for millions of users across ride-hai...
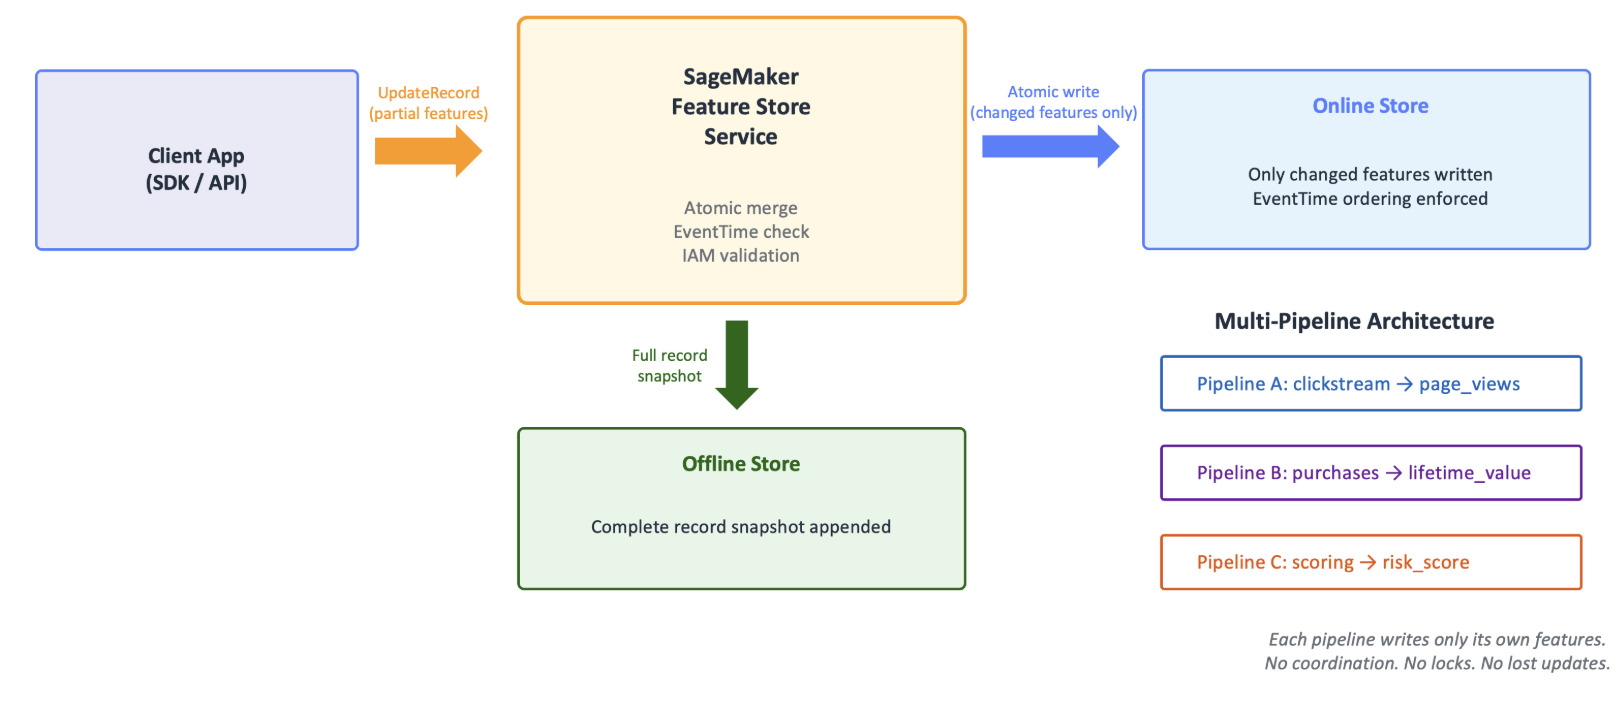
Amazon SageMaker Feature Store introduces UpdateRecord API, allowing feature-level writes to enhance ML model training efficiency. This eliminates the need for full-record writes, reducing latency and costs associated with unnecessary read capacity units.
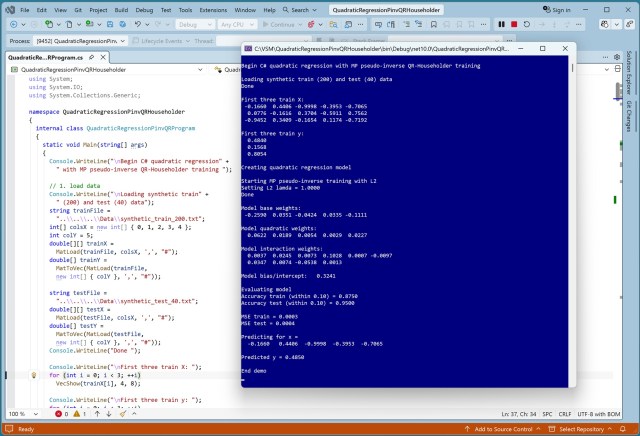
Summary: Implementing L2 regularization in quadratic regression with MP pseudo-inverse via QR-Householder training improves accuracy and handles bias term. The demo showcases how to augment training data and target values before applying the training algorithm.
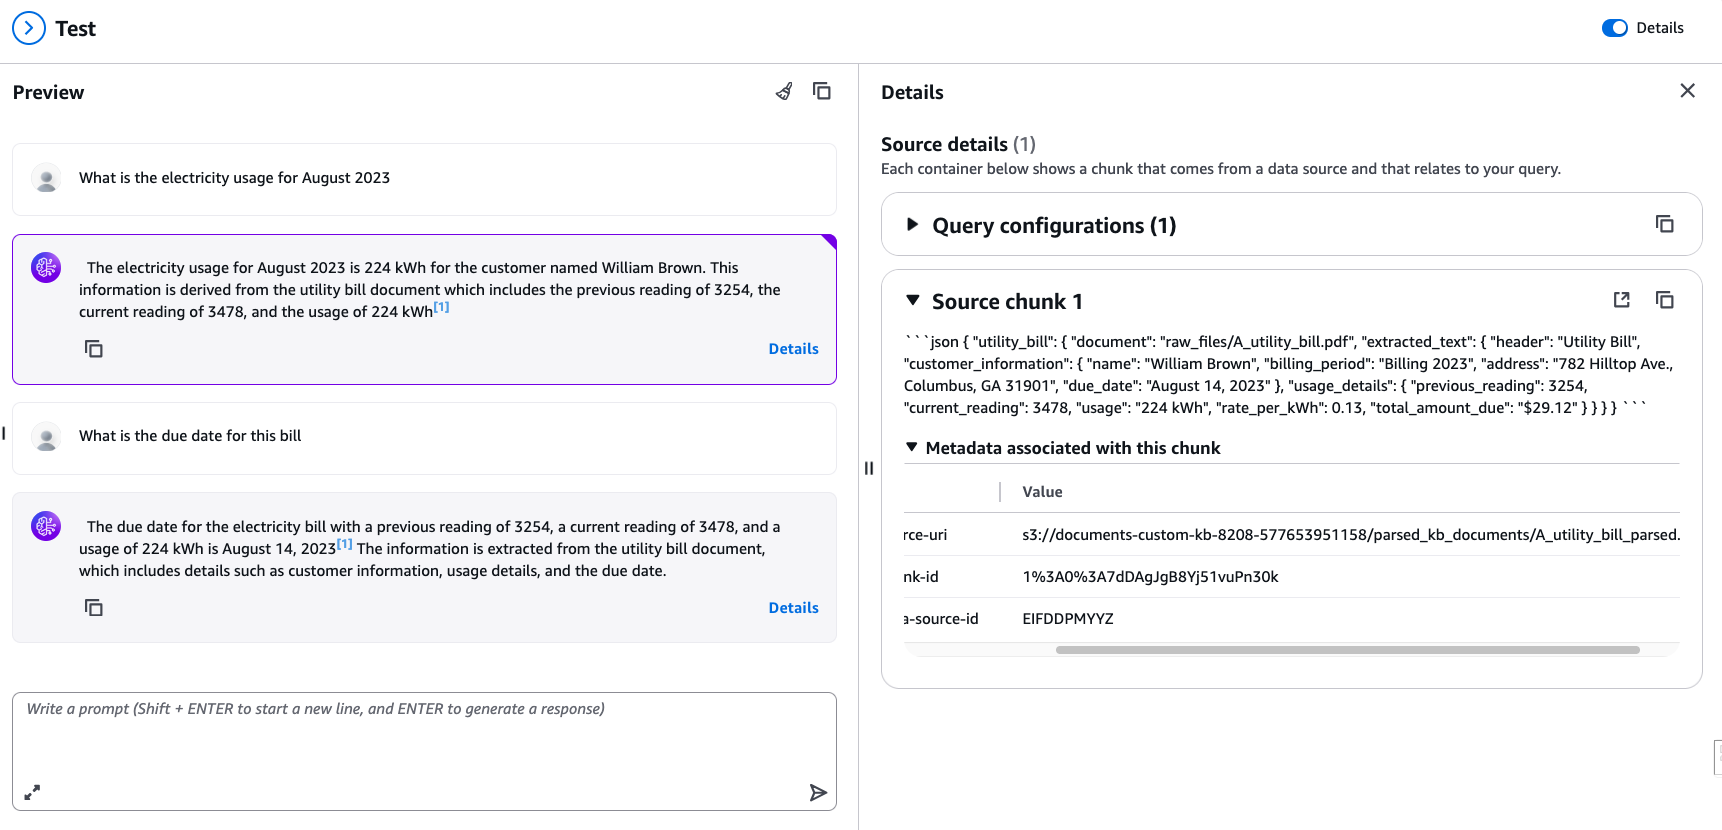
Amazon Bedrock, integrated with Amazon Textract, enables customer service teams to efficiently extract and analyze utility bill data, improving response times and accuracy. By combining structured and unstructured content extraction with generative AI capabilities, organizations can unlock actionable insights from complex documents, leading to faster and more precise customer interactions.
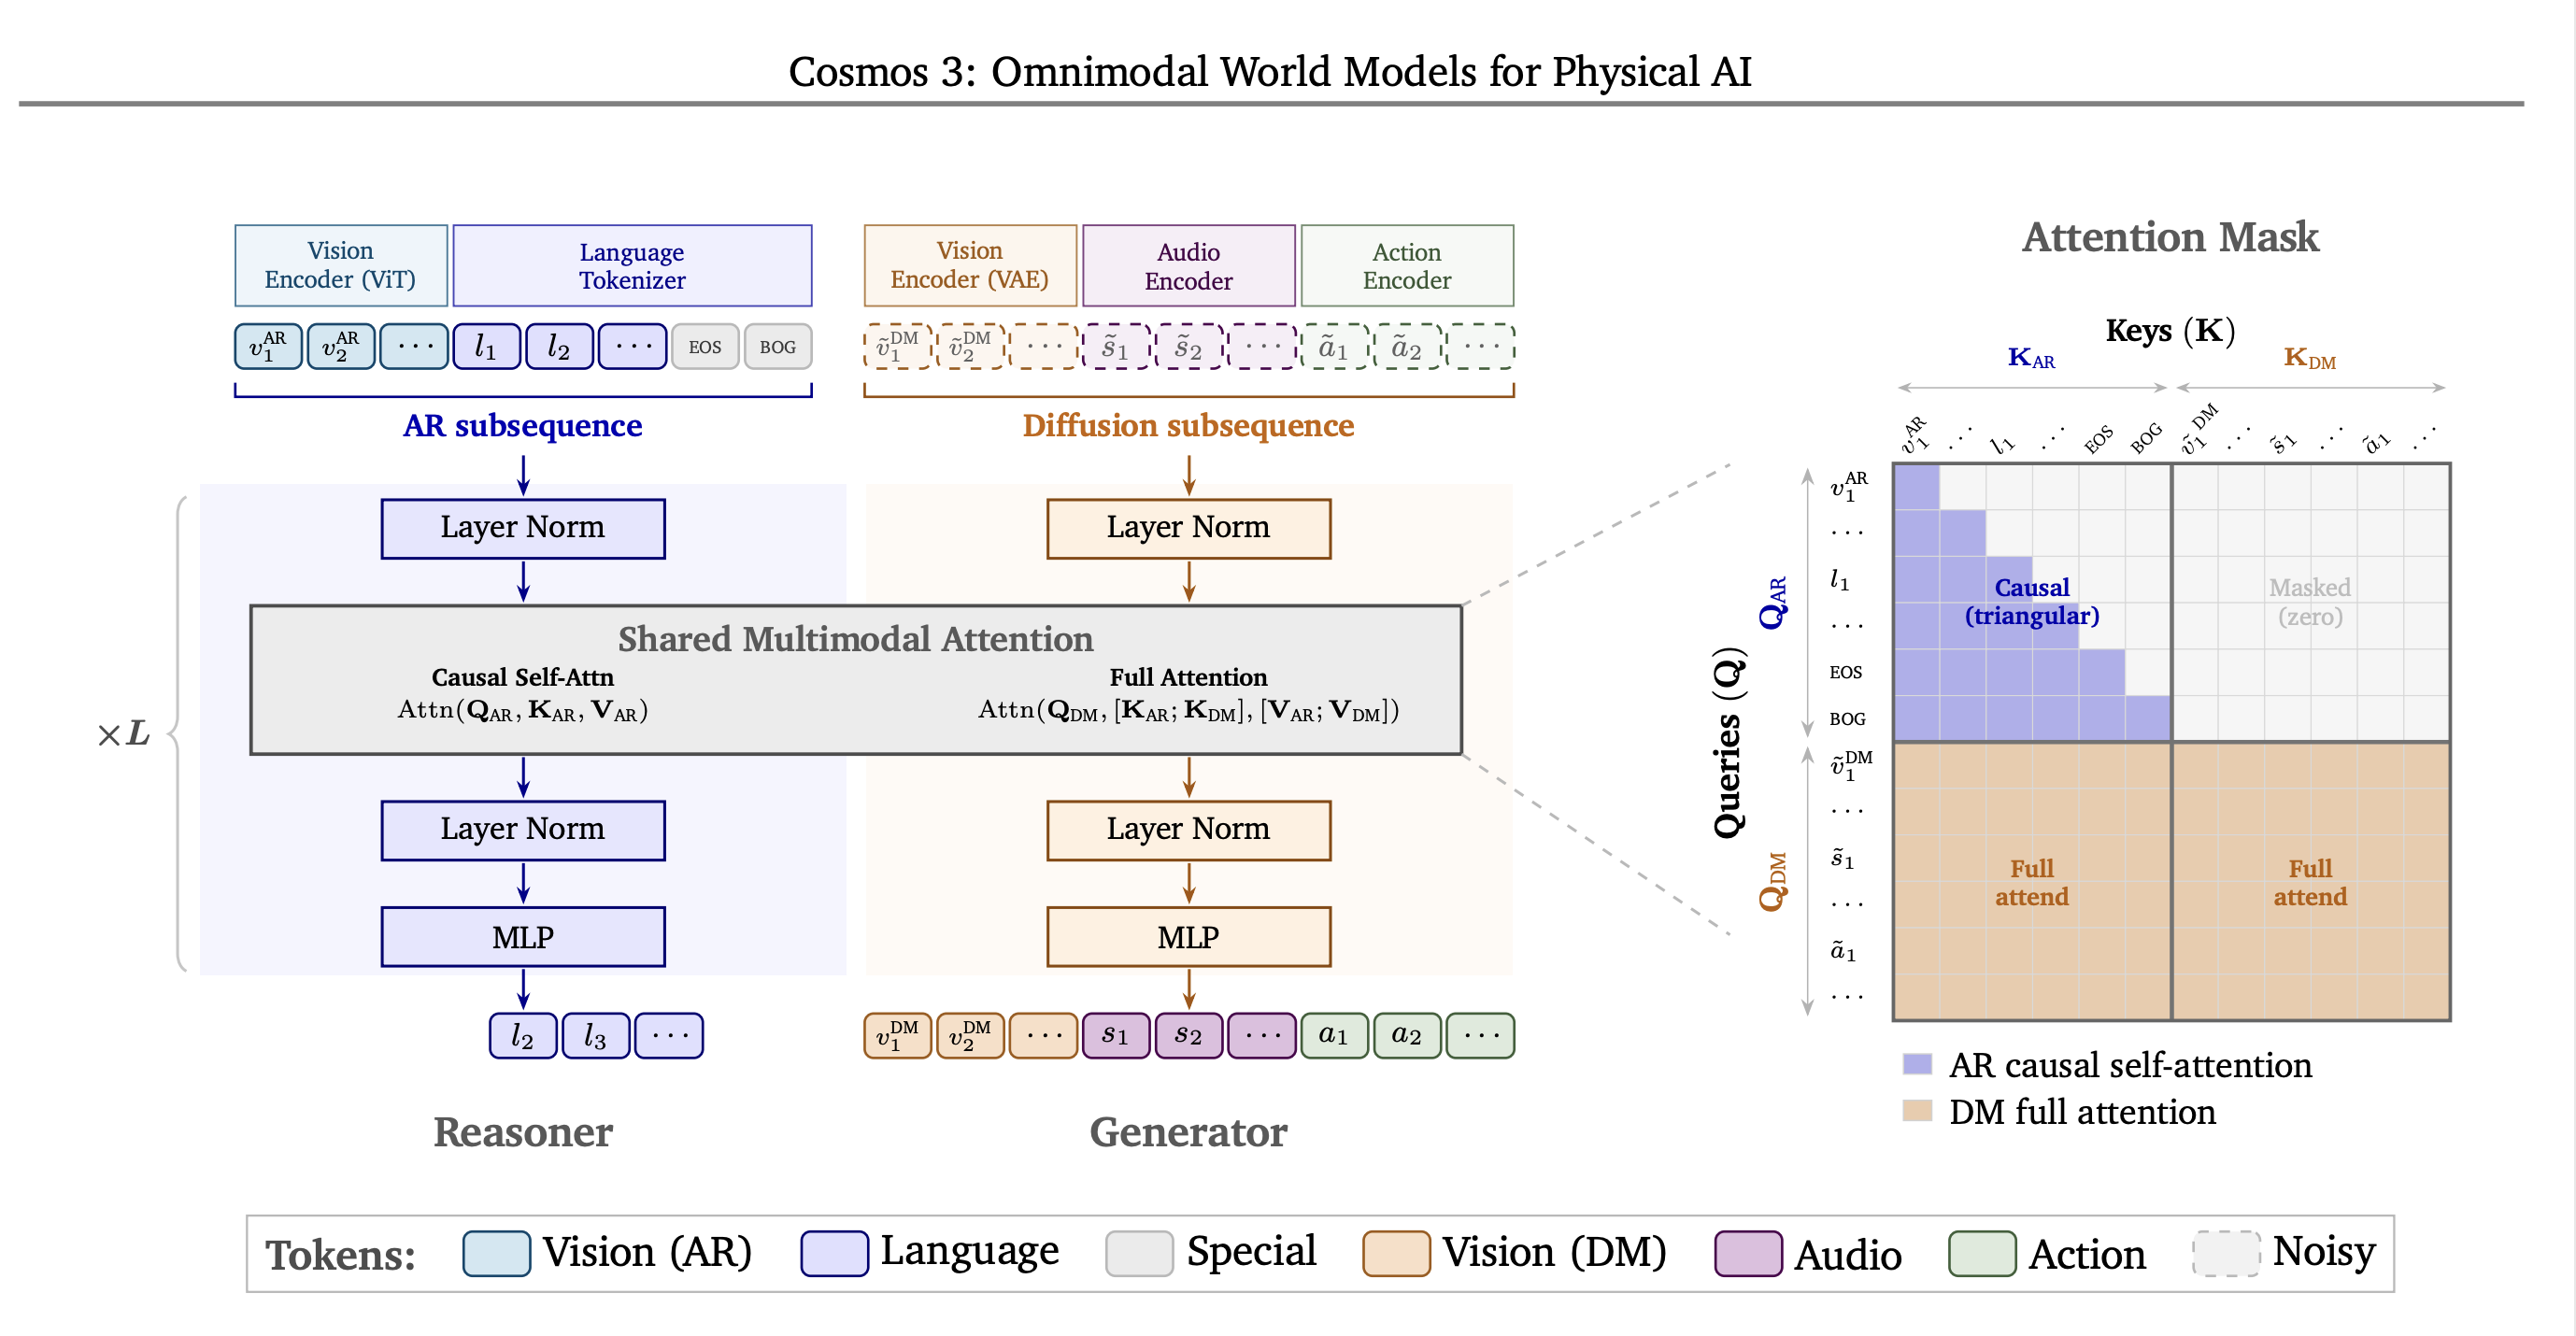
A Physical AI model factory uses NVIDIA Cosmos 3 on Amazon SageMaker HyperPod for continuous pipeline training, offering unique MoT design and distributed post-training. Cosmos 3 simplifies Physical AI pipelines by consolidating stages onto one GPU node pool for efficient capacity utilization.